What do diffusion models, representation learning, reinforcement learning, and test-time reasoning have in common? Each can be seen as learning an energy function or using one to guide sampling and search.
Excited to share our tutorial on energy-based models with @daibond_alpha!
We breathed life into LLM system.
Introducing Evolving Infra⚙️: an inference framework that adapts diverse and dynamic agent workload purely online and retires fixed PD disaggregation.
vs. NVIDIA Dynamo on up to 256 GB300 GPUs:
➡️ Up to 4.1× lower latency
➡️ Up to 14× lower P95 TTFT
➡️Up to 2.36× more revenue
on real agent traces(Computer Use, Coding and math agents) and opensource models.
🌐 Website: https://t.co/7I3iERjE6b
📄 Tech report: https://t.co/qDGcwl0svx
💻 Code: https://t.co/0VOBCptKcb
Which agent(e.g. Pi/Openhands) do you want us to accelerate next? Tell us below 👇
AI agents do remarkably well in discovering new ideas and solving hard science problems.
Do we understand how LLMs search their way to a final idea?
How do they recover after getting stuck during ideation?
We study LLM ideation by turning it into a two-agent game of question-answering with binary feedback.
Never underestimate people’s ability to get used to things. Bad management, promo-driven engineering, perpetual re-orgs; it’s the tech version of the boiling frog
💯💯 I'm personally comfortable saying it precisely because it's disingenuous to let PhD (or undergrad/MS) students be misled by things which stick to the old guard when the closed doors conversations are already moving differently. It's worth pointing out that I don't like the way things are evolving because it's inherently becoming more nepotistic in that access based on who you know or recommends you starts to matter disproportionately more and I would like a way to return to meritocracy (I know people will disagree with me on this last bit)
About 90% of RNA molecules in our cells are tRNAs. To date, we have mostly been blind to their abundance and regulation in single-cell sequencing. Today, I’m excited to share a new manuscript from my MD/PhD work
https://t.co/pQqVF7tAZI
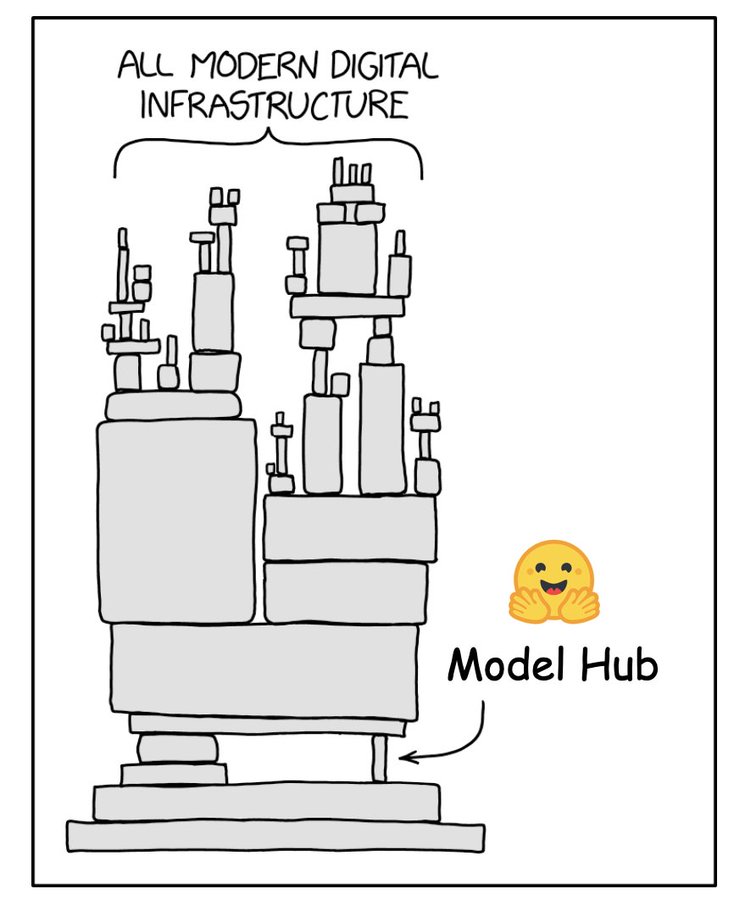
Over the last few months we optimized the llama.cpp CI to keep up with the fast pace of development
- We now use HF Buckets to store most of our Github Actions cache
- We use HF Jobs to enroll additional CI runners
More info in this blog post:
https://t.co/uZmpAWjnun
ECB's Isabel Schnabel: 🇩🇪 export-driven business model is "no longer viable in a fragmenting world". Germany's problems are not mainly due to competitiveness, but due to a "sustained weakness in domestic demand that makes 🇩🇪’s economy more prone than others to crises abroad".
Totally agree. There are many risks, but AI deciding to kill us all is BS, instead humans will use AI to do bad things (and good things too), just as with other tech (only faster).
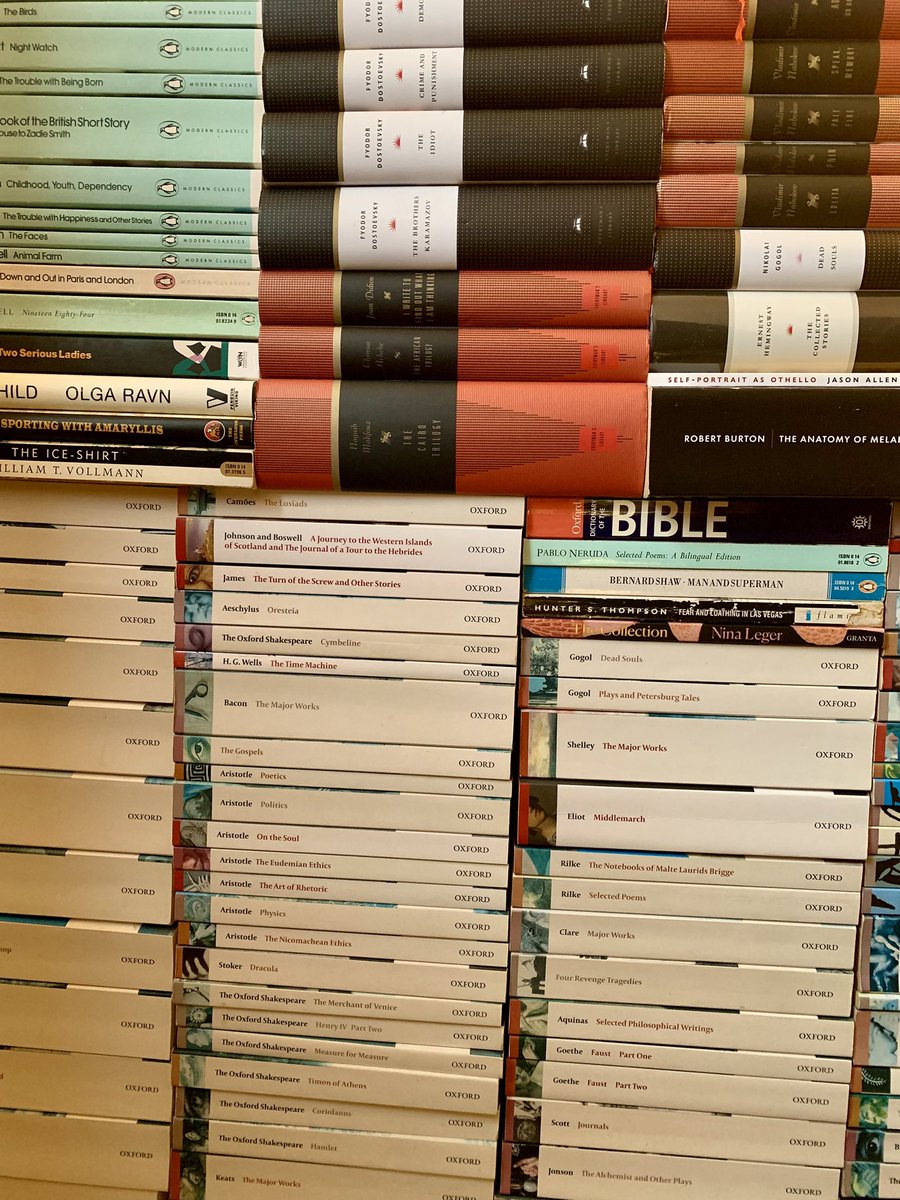
People ask if I’ve read all the books I own. No, not at all. A private library is not merely a storage facility for once-read books, but a tool box, a spice rack, a medicine cabinet — an investment in future health and happiness.
How much HIIT is enough?
A meta-analysis suggests ~11 min/session achieves 80% of the modelled maximal VO₂max improvement, vs ~52 min for moderate continuous exercise.
These are estimates, not universal thresholds. HIIT appears more time-efficient.
https://t.co/tsRWYFy1ns
High-quality data is limiting modern pretraining. But it turns out you can reach the same performance with far less data, in 4 lines of code.
Introducing 𝐋𝐚𝐭𝐞𝐧𝐭 𝐅𝐞𝐞𝐝𝐛𝐚𝐜𝐤 𝐈𝐬 𝐚 𝐂𝐨𝐦𝐩𝐮𝐭𝐞 𝐚𝐧𝐝 𝐃𝐚𝐭𝐚 𝐀𝐦𝐩𝐥𝐢𝐟𝐢𝐞𝐫.
Feed a Transformer's own top-layer states back in as input, and every token and every FLOP counts for more. The more data each parameter sees, the more you save.
TL;DR:
- On the same data, latent feedback reaches the same loss with 15% 𝐥𝐞𝐬𝐬 𝐭𝐫𝐚𝐢𝐧𝐢𝐧𝐠 𝐜𝐨𝐦𝐩𝐮𝐭𝐞 at 100 unique tokens per parameter, and 46% less at 400 (2-epoch budget)
- At the same number of epochs, it reaches the same loss with 10% 𝐥𝐞𝐬𝐬 𝐮𝐧𝐢𝐪𝐮𝐞 𝐝𝐚𝐭𝐚 at 60M parameters, and 20% less at 778M (1 epoch, 50 unique tokens per parameter)
- Downstream (109 tasks in 37 suites): ahead in all 17 settings at a 4-epoch budget
- Our fitted scaling law predicts the savings keep growing with model size. On a 2-epoch budget, the compute saving goes from 15% at 271M parameters (measured) to 34% at 10B and 45% at 100B (predicted)
🧵 𝐏𝐚𝐩𝐞𝐫, 𝐜𝐨𝐝𝐞 𝐚𝐧𝐝 𝐜𝐡𝐞𝐜𝐤𝐩𝐨𝐢𝐧𝐭𝐬 𝐚𝐭 𝐭𝐡𝐞 𝐞𝐧𝐝
This whole thing sucks, and I wish none of it had happened. It’s a really sad day!
But I want to make one thing clear: we’ll keep fighting for open-source AI, harder than ever. This is too important to slow down now. Let’s go!