Hudi 1.0 is the most powerful release to date for data lakehouses. Read the blog for details:
Secondary Indexing, Expression Indexes, Partial Updates, Non-blocking Concurrency Control, New LSM timeline, +more: https://t.co/QHi7rnNsn9
#datalakehouse#opentableformat
For column renames + deletes + complex evolution: opt into schema-on-read with https://t.co/psHuYs25bV.enable=true. Spark 3.2.1+, can't be disabled once on.
Proven at scale at Uber, Walmart, LinkedIn.
Links ↓
#ApacheHudi#SchemaEvolution
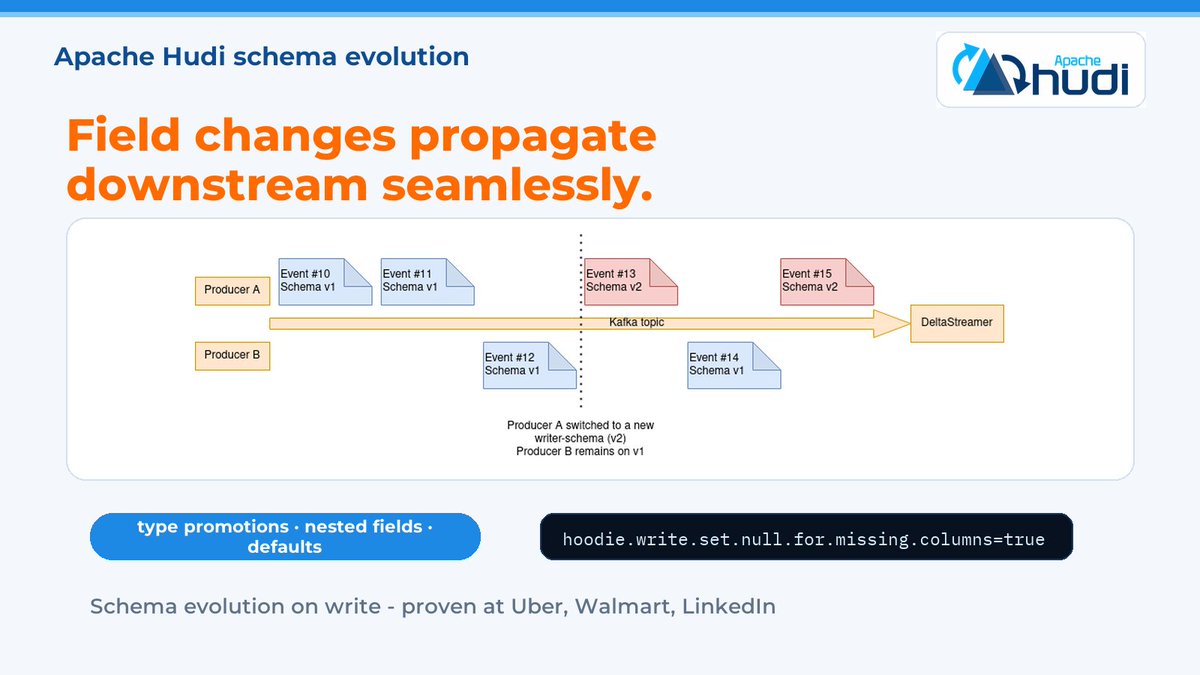
Safe (writes succeed, reads return the full dataset): add nullable column at root or nested level, add complex type with default, promote int→long / float→double / string↔bytes, add Hudi meta columns.
Upstream added a column. Did your pipeline survive?
Hudi supports schema evolution on write out of the box — the changes that happen in production all the time.
Upstox — one of India's largest online trading platforms — ingested 300 GB of new data per day for 12 million customers on Apache Hudi.
Capital markets workloads stress every part of a lakehouse ↓
Hudi tables are streaming sources. Read changes, not whole tables.
Spark Structured Streaming on Hudi is spark.readStream.format("hudi").load(basePath). That's it.
Pair with KEEP_LATEST_COMMITS retention long enough that your longest checkpoint lag never falls off the table.
Flink streaming reads work the same way — incremental read mode, checkpoint-driven, commit-aware.
Links ↓
#ApacheHudi#StreamingData