Founder @Onehousehq — Data Infra for Agents. Creator of @apachehudi, built the first #DataLakehouse @Uber. Databases, Dist. Systems. LinkedIn, Confluent.
SITUATION DETECTED: Amazon CEO Andy Jassy says that AWS capacity for 2026 is completely sold out, 2027 is largely sold out, and "a good chunk" of 2028 is already sold as well.
Spark on Kubernetes at scale is hard. Onehouse runs a lot of it, and tomorrow we're sharing what we've learned.
In most places, the knowledge required to get all of this right lives across the data team and the Kubernetes/infra team.
We've collected a list of things that looked simple at first, but hard in production:
- OOM kills
- Shuffle storage
- Spot interruptions
- Autoscaling
- Long-running drivers
- Cluster upgrades
- Keeping streaming jobs alive while the infra underneath changes
Most of it lives in the gap between the data team and the infra team.
Webinar tomorrow. Bring your worst production problem.
Link in comments.
Last week, I posted on why warehouses still default to closed formats. What I learned: they won't flip the default. Open formats are opt-in.
So the fix is with the users. Give every open format (Delta, Hudi, Lance, Vortex, ClickHouse, DuckLake) the same consideration on performance and flexibility that you give the closed ones.
Your data will thank you.
Back to building on open formats.
@rmahindra Does the technical problem simply boil down to a very large table on object storage with fast writes and fairly fast analytical and point lookups?
Not at all. Customers are stuck. We speak to dozens every week. They have to pay hefty egress costs to do the migration.
The question I raised is more about first principle and forward-looking. Why not make open formats the default for any new table created from this point forward? That costs the vendor nothing.
Btw the LinkedIn counterpart for this x post has a lot more thoughts if you are curious about this topic .
Last week, Databricks CEO Ali Ghodsi and I debated Iceberg and open table formats on a post. Then I caught myself.
Why are we debating each other while Snowflake, BigQuery and Redshift still default customers to closed formats?
Two years of Iceberg announcements. Still no public retirement date for their closed formats.
Open-source projects get scrutinized for interoperability on every release. The largest warehouses should meet the same bar.
We’ve spent a decade building open formats and data lakes. I think it’s time we asked.
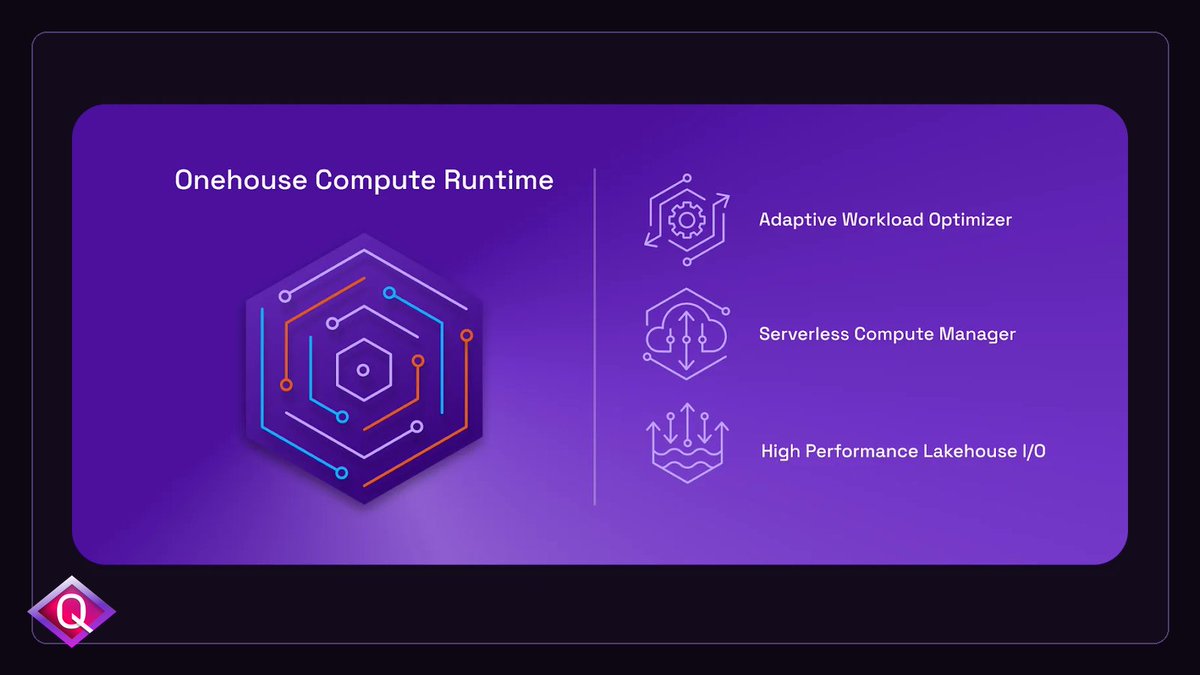
To squeeze the performance out of our runtime components, we implemented a good amount of concepts from - SEDA: an architecture for well-conditioned, scalable internet services https://t.co/RhXodpXFX7
The seminal work at MIT around writing high-performance server software and the gift that keeps on giving.
A cloud VM’s network I/O, CPU, and storage IOPS taking turns instead of running concurrently is bad news: the CPU sits idle while a file downloads, then works through it once the download finishes.
@shcallaway@sazabi I don't have extreme opinions on unit tests, but I hate the false sense of security they give developers, who only later realize the end-to-end functionality doesn't work at all.
@a16z Consumer lives and livelihood improving will the ultimate test for this AI wave? Once we start to run out of ideas to use AI to make enterprises efficient.