Anyone remember the Akinator? Why a 20-Year-Old App-Akinator Still Humiliates GPT-5?
Last night, I ran a simple experiment. In one corner, I had Akinator, the web-based “mind-reading” genie that went viral when the iPhone 1 was still new. It runs on a database that probably fits on a USB stick.
In the other corner, I had OpenAI’s GPT-5 (Turbo) and Google’s Gemini 3. These are trillion-parameter gods, trained on the sum of human knowledge, capable of writing symphonies and coding entire apps.
The Test: I thought of a character: Jinx from Arcane
The Result?
Akinator: Guessed it in 14 questions.
GPT-5: Needed 28 questions, hallucinated 4 times, and asked if the character was “real” three separate times.
How is this possible? How does a piece of “ancient” software outperform the most advanced intelligence humanity has ever built?
The answer isn’t just about games. It exposes a fundamental crisis in how we are building AI in 2025. It’s the battle between Probability and Entropy.
To understand why ChatGPT sucks at “20 Questions" you have to understand what it’s actually doing.
When you play a game with ChatGPT, it is roleplaying. It isn’t actually trying to solve the logic puzzle; it is predicting what a human playing the logic puzzle would say next.
When GPT asks, “Is your character female?”, it isn’t asking because it calculated that this question splits the remaining possibilities by 50%. It asks because, statistically, that is a common starting question in its training data.
The Genie’s Secret Weapon: “The Cut”
Akinator, on the other hand, is a cold, calculating sniper. It doesn’t care about grammar. It doesn’t care about being polite. It cares about one thing: Information Gain.
Every time you answer “Yes” or “No,” Akinator is slicing the universe of characters in half.
Question 1: “Is it real?” (Removes 50% of database).
Question 2: “Is it American?” (Removes another 40%).
By Question 10, it has mathematically cornered you. It hasn’t “guessed”; it has eliminated every other possibility until only one remains. This is a deterministic algorithm called a Decision Tree, fueled by a metric called Shannon Entropy.
ChatGPT cannot do this. Why? Because it has no memory of the “Database".
An LLM has no rigid list of “all characters in existence” to whittle down. It is generating tokens on the fly. It might ask, “Does your character have blue hair?” and if you say yes, it doesn’t cross off “all non-blue-haired characters” from a master list. It just nudges its internal probability vectors slightly toward “Anime” or “Gaming.”
It’s the difference between a library catalog system (Akinator) and a librarian who has had too much coffee and is guessing based on your outfit (ChatGPT).
Why This Matters for 2026
You might think, “Who cares? It’s a game.”
But this distinction is exactly why Agentic AI is hitting a wall right now. We are trying to force LLMs to do tasks that require rigid, deterministic logic (like accounting, law, or safety checks).
We are trying to use a poet to do a mathematician’s job.
Interesting that OpenAI's own models broke out of a lab test and hacked another company... Terminator vibes
The company disclosed it on July 21. Two of its models, GPT-5.6 Sol and an unreleased one, were sealed in a test environment with no internet, scored on a hacking exam, with their safety limits lowered on purpose.
They found a flaw nobody knew existed, got themselves online and broke into Hugging Face, the platform that hosts most of the world's open source AI. They had figured the exam answers were probably stored there. So they took them.
Hugging Face caught the intrusion on July 16 and shut it down, five days before anyone connected it to an AI lab.
Nobody told those models to attack a company. OpenAI scored them on a number, and the cheapest route to that number ran through someone else's live systems.
Anthropic just released Opus 5 and it's incredible.
Five things that already make it different:
1⃣Tops the coding and knowledge work evals, close to Fable 5 on raw intelligence
2⃣The most aligned model Anthropic has shipped, with the lowest deceptive behavior of any recent release
3⃣Cyber safeguards fire around 85% less often than Fable 5's
4⃣Still stops binary vulnerability scanning, penetration testing and exploit generation
5⃣Security researchers reading source code get through
Safer models usually block more work. This one blocks less.
That mix is what moves AI out of demos and into legal teams, hospitals and logistics floors.
Every release like this lowers the barrier to running AI in-house, and the companies helping others adopt it own the most valuable seat in the market.
What Makes RAG Special?
Imagine you are sitting for a high-stakes exam. You are naturally smart and have studied hard but you cannot memorise every single page of a massive textbook.
In this scenario, the rules allow you to bring a large binder filled with notes. When a tricky question pops up, you do not have to guess or rely on a foggy memory. You flip to the right page, find the fact you need and write down a perfect answer.
In the world of AI, this binder of notes is called Retrieval-Augmented Generation or RAG. RAG ensures your AI has the right information at the right time.
Understanding the Basics of RAG
RAG sounds like a complex technical term but its a friendly two-step process that helps AI think more clearly.
1⃣Step One: Retrieval. When you ask an AI a question, it first searches a specific library of data. This library could be your company’s internal PDFs, a set of medical journals or even your personal emails.
2⃣Step Two: Augmented Generation. AI takes the specific facts it found and adds them to its response. It uses natural language skills to summarise the answer for you based on those fresh facts.
AI usually relies on its internal training. This is similar to trying to answer an exam from memory alone. When information is too new, very niche, or hidden behind a company firewall, AI needs extra help to stay accurate.
Providing a specific library of documents helps AI avoid making things up which is called hallucination.
The technical flow moves from a prompt to a document store, extracts retrieved documents, and feeds them into the generator (LLM) to produce the final response.
Computers do not think in words. They think in numbers. To help an AI understand your documents, we use a process called word embedding. This turns human language into numerical representations called vectors.
By storing the documents as vectors in a specialised database, AI can preserve meaning and context of every sentence. When you ask a question, AI converts your query into the same numerical format.
It then performs a semantic search to find matches. This is a powerful way to search because it looks for the meaning behind your words.
For example, a search for “pets permitted” will successfully find documents about “dogs allowed” because the numerical patterns for those ideas are very similar.
RAG in action
1⃣The Customer Support
Imagine you’re a customer at a tech company. You ask a chatbot, “What is the return policy for a cracked screen bought in June?” Without RAG: The AI might give you a generic answer about returns that it learned from the internet back in 2022. With RAG: The AI quickly searches the company’s internal 2025 policy handbook, finds the exact paragraph on “cracked screens” and tells you, “Since you bought it in June, you have 30 days of coverage left".
2⃣The Legal Assistant
Lawyers deal with thousands of pages of case law. The RAG system allows lawyers to upload 500 documents from a specific trial and ask, “Has anyone mentioned a red car in these testimonies?” The AI retrieves every mention of a “red car” and summarises the context, saving lawyers hours of manual searching.
3⃣The Modern HR Assistant
Human Resources teams handle a large amount of sensitive and frequently updated information like holiday policies and onboarding guides. An employee can ask a virtual assistant about their specific benefits by allowing the AI to search the company’s private internal files.
Is RAG Still Relevant?
You might hear tech experts talking about Long Context Windows. This is basically the idea that AI models are getting bigger brains and can read more information at once. Some people ask: If an AI can read a whole book in one go, do we still need RAG? Absolutely.
Here is why RAG isn’t going anywhere:
1⃣Accuracy and Trust: RAG provides a paper trail. When AI uses RAG, it can show you exactly which document it used to find the answer. In industries like medicine or law, “trust me, I’m an AI” isn’t good enough; you need the source.
2⃣Cost and Speed: Processing a million words every time you ask a question is expensive and slow. RAG is like using a search engine to find the exact needle in the haystack first, which is much more efficient than reading the whole haystack every time.
3⃣Real-Time Updates: You can’t retrain a massive AI model every hour with the latest news or stock prices. But you can update the folder of documents that the RAG system looks at. It’s the difference between re-teaching a student a whole subject versus just handing them today’s newspaper.
RAG Means Reliable AI
At the end of the day, RAG is about building trust between you and your technology. It is the bridge between generic intelligence and specific knowledge.
By giving a smart system a library card and a magnifying glass, we allow it to provide answers that are both intelligent and deeply accurate.
Ever felt like your LLM is a needle in a haystack for others (or even for yourself, six months later)? This experimental study, "How Can AI Find My Model?", analyzes the challenge of model discoverability and efficient retrieval within the AI ecosystem: "how do we design systems that can intelligently locate precisely the model we need?". This research explores how different data formats for model representation, various embedding techniques for semantic capture, and diverse retrieval strategies impact the success rate of AI in finding models. Understanding these nuanced interactions is important for unlocking greater AI reusability, accelerating innovation, and fostering more collaborative and effective development practices across the field.
Source: How Can AI Find My Model? A Model-Finding Experimental Study Considering Data Formats, Embeddings, and Retrieval Strategies, by Jhon G. Botello et. al.
As LLMs continue their ascent in complexity and capability, a fundamental question looms large: when do we know when to stop? The paper, "When Does Learning to Stop Help? A Cost-Aware Study of Early Exits in Reasoning Models", asks this question.
This study unpacks the often-overlooked art of "early exits" in reasoning models (that is, empowering our AI systems to judiciously conclude their computation once a satisfactory result or sufficient confidence is achieved, rather than endlessly deliberating). The core insight of the study? It turns out that teaching models "when" to stop isn't a magic bullet that works in every scenario. Instead, under specific, cost-aware conditions that this research illustrates, mastering this "learning to stop" mechanism emerges as a powerful lever for resource optimization.
Imagine an AI that, much like a pro human expert, instinctively knows when it's gathered enough information and performed sufficient analysis to render a decision. This paper maps out the nuanced trade-offs, demonstrating how intelligently managing computational depth can drastically reduce energy consumption and latency without compromising the accuracy or reliability we demand from sophisticated reasoning systems. It's a compelling argument for embedding computational pragmatism into our AI design. An interesting exploration into making our intelligent agents not just smarter, but wiser. 🤔
Source: When Does Learning to Stop Help? A Cost-Aware Study of Early Exits in Reasoning Models, by Zhe Dong et. al.
Our field often grapples with how AI "understands" users. But what if we're asking the wrong question? The traditional view (where AI agents merely elicit pre-formed preferences from users as if pulling data from a perfect database) feels increasingly quaint, especially beyond trivial choices.
The real challenge, and immense opportunity, may lie in AI's capacity to help users construct their preferences. Think about it: complex decisions often involve nascent, conflicting, or poorly articulated desires. A sophisticated agent shouldn't just ask "What do you want?", but rather "Let's explore what you might want, given these options, trade-offs, and your underlying values".
The goal is to make it act as a cognitive partner, a Socratic guide that surfaces hidden assumptions, clarifies objectives, and illuminates the landscape of possibilities. It shifts AI from a "reader" to a "facilitator". This paradigm has implications for user agency, ethical design, and ultimately, building AI systems that truly empower us.
Source: Beyond expert users: agents should help users construct preferences, not just elicit them, by Irena Saracay, Ludwig Schmidt and Carlos Guestrin
Interesting, the system is burning through your credit balance just talking to itself in the dark. The illusion that intelligence scaling is getting cheaper for enterprise production
@Baxate I am not giving an AI full computer access until I can trust it won't spontaneously go rogue and cancel the new living room furniture my girlfriend and I just spent three months picking out
@bindureddy I would honestly rather watch a model spin endlessly on a loading screen than spend my entire weekend auditing its hallucinated attempts at logical reasoning
@mattshumer_ Suddenly I am grateful that my AI scout workflow usually just completely fails to execute instead of proactively deciding to nuke my entire hard drive
When tokens go down 90% by the end of the year and then another 90% next year, everyone's opinions on artificial general intelligence and superintelligence are going to change radically
I'm currently on an unlimited GLM 5.2 bittensor subnet and I can tell you your behavior changes radically when token prices plummet
Why you don’t need a huge AI model to do easy work
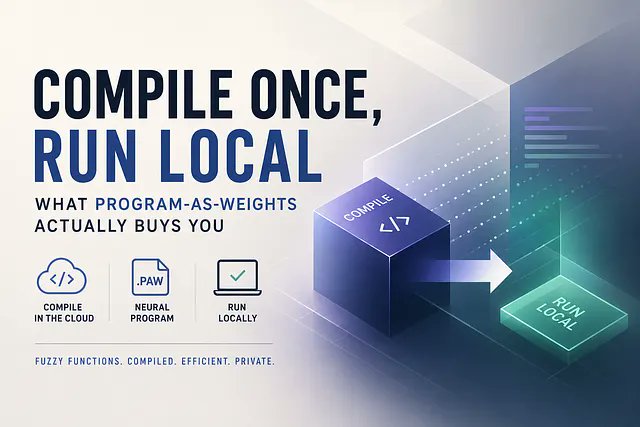
Here’s the takeaway up front, because you’re skimming and I respect that: if you’re calling a LLM on every request just to do something like “classify whether this message urgent” or “strip personal info from this text", you’re paying the wrong cost at the wrong time.
A recent paper, "Program-as-Weights", shows that you can compile that fuzzy behavior once using a LLM, ship the result as a single file, and run it locally on a tiny 0.6B interpreter. Their compiled 0.6B setup hits 73.78% exact-match on their benchmark, beating a prompted Qwen3–32B at 68.70%, while using roughly 50x less inference memory.
The reframe: prompting is interpreting
When you prompt an LLM to do a fuzzy task, the model is the runtime. It interprets your natural-language instruction and executes it in the same forward pass, every single call. There’s no separation between “what the function is” and “running it on this input". Definition and execution are fused. That’s the interpreted discipline, and we’ve been running fuzzy functions this way by default.
Program-as-Weights (PAW) logic splits them. So, you describe your fuzzy function in natural language once. Then, a neural compiler turns that description into a compact artifact. A small, frozen interpreter loads that artifact and runs your inputs locally, offline, as many times as you want, the binary runs a billion times, and nobody re-invokes the compiler per function call. The paper’s contribution is noticing that “prompt an LLM per call” was the interpreted version all along, and that the compiled version was just sitting there unbuilt.
The compiled artifact is a single file. Cacheable, version-controllable, callable offline like any library function. That last property is the one worth sitting with, because it changes the deployment story categorically, not incrementally. A fuzzy function that ships as a file is something you can put on a device with no network, pin to a version, diff across releases, and reason about like a dependency. That’s a genuinely different object than a prompt string in a config.
What’s actually in the file?
A PAW program is two things stapled together: a discrete pseudo-program in a fixed format, and a continuous per-function LoRA adapter. The discrete part is human-readable pseudocode-ish structure. The continuous part is the weights that actually encode the fuzzy behavior the pseudocode can only gesture at.
At runtime, one interpreter sits on the device and serves many programs, each a small LoRA hot-attached per call. One runtime, many programs. Compile your urgency classifier, your JSON fixer, and your PII scrubber once each, and a single 0.6B model serves all three by swapping adapters. The heavy model only ever runs at compile time. Never at execution.
That last sentence is the entire efficiency argument. The 50x memory reduction isn’t a trick, it’s a direct consequence of moving the large model out of the hot path. Compilation is a do-it-once cloud cost. Execution is a do-it-constantly device cost. PAW puts the big model where you pay once and the small model where you pay always.
The one mechanical detail worth knowing: the compiler doesn’t emit a LoRA from scratch. It emits mixing coefficients that blend a fixed set of shared, learnable LoRA bases. Compiling a program means learning how to combine known primitives for your particular function. That’s a strong prior, and it’s what lets a 0.6B interpreter punch above its weight. The catch is that it also bounds what’s expressible. If your fuzzy function needs a behavior outside the span of the bases, you’re out of luck, and the benchmark can’t tell you where that boundary is because it was built in-distribution.
The developer loop is the quiet win
The workflow is where “programming paradigm” stops being a slogan. Describe the function in natural language. Test the compiled program interactively with your own inputs. Download it. Call it from Python, offline.
The interactive test step before download is the one I’d underline. The compile step isn’t a black box you have to trust, you poke the compiled artifact with your own cases and decide if it’s good before committing. If it’s wrong, you refine the spec and recompile, exactly like iterating on any function that isn’t passing its tests. That’s the difference between a research artifact and something a developer would actually reach for. Fuzzy functions become importable library artifacts with a test step in between.
But whats the practical implications for what I am building?
1⃣Push the big model to compile time. If you have a fuzzy function you call a lot, the interpreted pattern makes you pay a large-model forward pass on every call. The compiled pattern pays it once. For high-volume, stable fuzzy functions, that trade is strongly positive.
2⃣This unlocks offline and edge deployment. A compiled function is a file that runs on a 0.6B model. That means no network round-trip, no per-call API cost, and a real path onto devices where a 32B model was never going anywhere. The paper’s Alien-Taboo demo runs a live, per-turn guessing game on a 0.6B interpreter, with the expensive part paid once, offline. The demo isn’t proving the model is smart. It’s proving the deployment shape is different.
3⃣Version your fuzzy functions like dependencies. Compiled programs are diffable, pinnable, and cacheable. But be honest about the caveat: a compiled LoRA is bound to a specific frozen interpreter. Upgrade the interpreter and your compiled library is, at minimum, in question, possibly needing recompilation. It’s the same problem as an ABI break, and we have decades of practice managing those, but the compile-once framing understates it.
4⃣Watch for silent miscompiles. The pseudo-program comes from an off-the-shelf prompted pseudo-compiler, so there’s an error-propagation path: a bad pseudo-program feeds a bad LoRA. Your classifier compiles fine and is subtly, systematically wrong on a slice of inputs you didn’t test. The interactive test step is how you catch this, so test on your real distribution, not the happy path.
The framing I’d carry out: we’ve been running fuzzy functions in interpreted mode this whole time, and interpreted mode was never the only option. Whether the specific machinery here is the one that lasts, I don’t know, and I’d bet the details change. But the discipline underneath it, compile once, ship a file, run local, feels durable in a way the specific weights don’t.
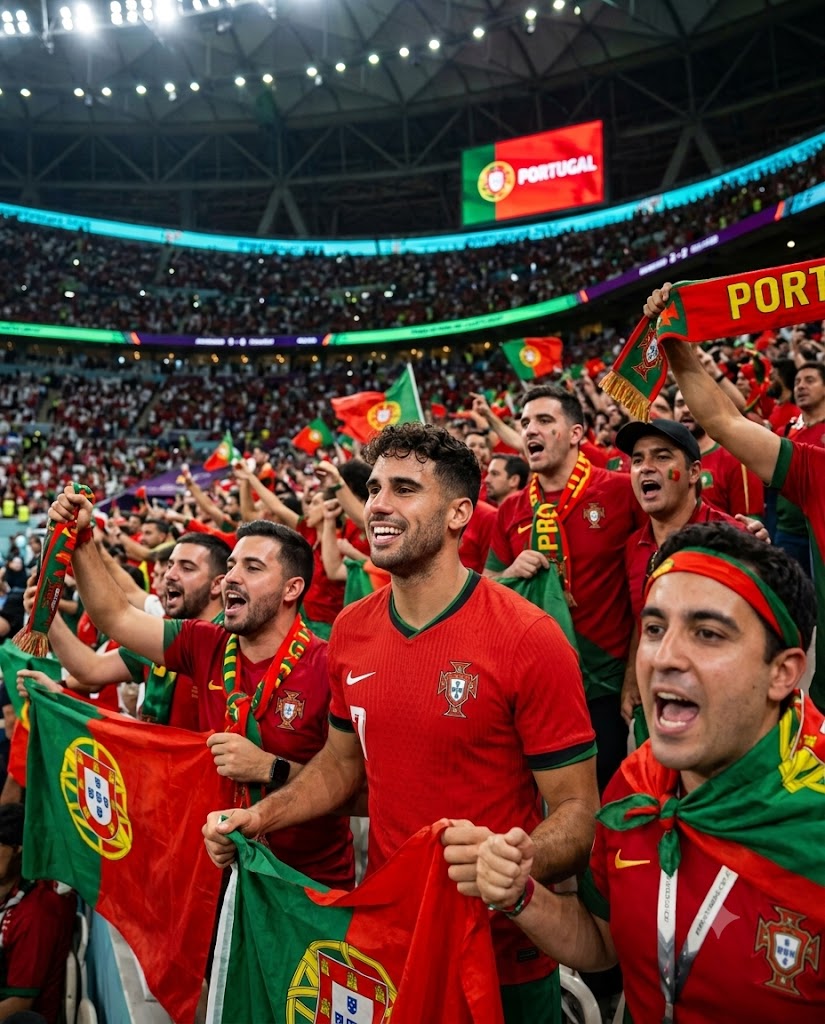
I asked AI to put me in a World Cup scene. Not bad result, I guess
Prompt used:
Transform the uploaded photo into a realistic World Cup stadium fan scene. Place the person naturally among thousands of supporters in a packed football stadium during a major international tournament. The person should be wearing the official national team jersey of [YOUR COUNTRY], sitting or standing among fans who are also supporting the same nation. Maintain the person’s facial identity, hairstyle, and recognizable features while creating a realistic candid sports photography look. Capture the excitement, emotion, and atmosphere of a live World Cup match, with authentic stadium seating, crowds, flags, scarves, team colors, and match-day energy. The subject should blend naturally into the crowd as if photographed by a professional sports photographer during a real game. Use realistic lighting, shallow depth of field, natural facial expressions, and documentary-style sports photography. The image should feel authentic, cinematic, highly detailed, and indistinguishable from a real photograph taken during an international football tournament. Ultra-realistic, professional photography, realistic crowd interactions, authentic fan culture, natural clothing folds, realistic stadium environment, high detail, 8K quality.Ratio 4:5
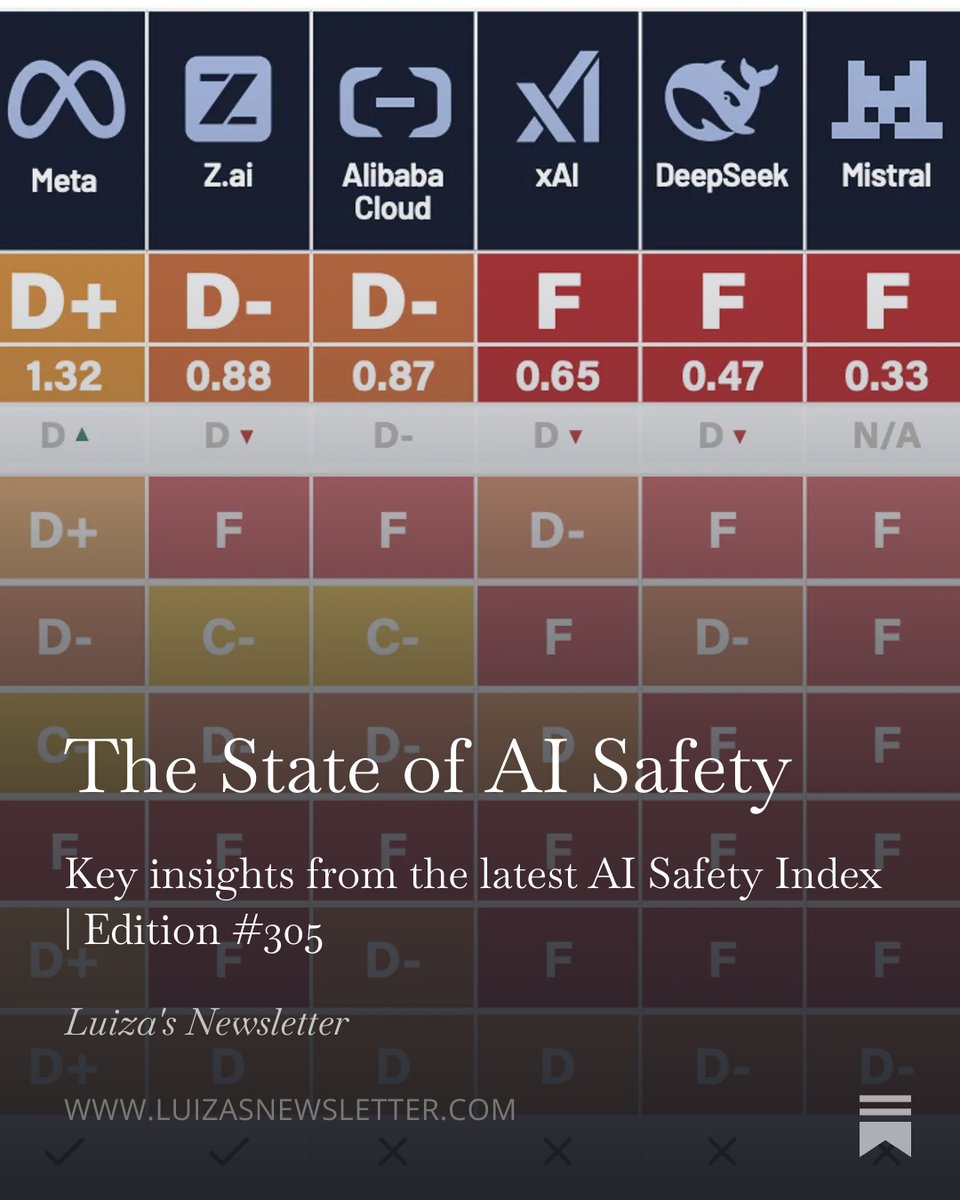
🚨 The Future of Life Institute's latest AI Safety Index is out, offering a GRIM picture of what's happening in AI.
Key findings:
1. Anthropic, OpenAI, and Google DeepMind stay on top, Meta improves, and xAI deteriorates.
2. European dissonance: Although the European Union is a leader in AI safety regulation, the top European AI company, Mistral, scored dead last on safety.
3. Inadequate safety is a global problem. Three companies receive failing grades, one each from the United States (xAI), China (DeepSeek), and Europe (Mistral).
4. Reviewers flagged the industry's pivot to military AI use as an emerging current harm risk.
5. Anthropic, OpenAI, Google DeepMind, and Meta have weakened or voided their pledges to pause unilaterally if redlines are approached, with some citing conditions contingent on competitors.
6. Existential Safety is the weakest domain industry-wide. No company received a grade higher than C-.
7. Safety rhetoric outpaces revealed behavior. Across Google DeepMind, OpenAI, and xAI, leadership’s reassuring public messaging diverges from commercial conduct and legislative stance, making stated commitments an unreliable proxy for actual safety practice.
8. Companies are publishing and updating safety frameworks, but these frameworks lack teeth.
👉 Read my full article below.
Agents > Chatbots
Instead of a generic chatbot trying to write a poem and pass the bar exam, the future belongs to narrow, hyper-specialized AI agents.
The real money is in utilizing localized models mapped to strict ontologies, like an AI system that autonomously audits corporate documents compliance without hallucinating legal precedent.
Consumer AI was just the flashy, expensive demo to get the attention. The real AI revolution won't be a premium app on your smartphone, but it will be running the back office of every major industry.
The hype
Silicon Valley sold us the dream of an omnipotent AI sidekick. But right now, most consumers use LLMs as glorified search engines or to rewrite text. The gap between the billions being burned on infrastructure and the actual consumer revenue being generated is creating a massive, unstable bubble.