My work has been accepted to ICCS 2026!
This summer, I’ll present it at DESY in Hamburg. The paper will also be published in the Springer Nature LNCS proceedings.
After a long research journey, I’m incredibly happy to see it reach this point.
https://t.co/nyLpChQSJU
tesla is a textbook tabby, so he’s naturally interested in our food and wants to taste it. i was like “classic animal instinct.” then this morning, while giving him food, i realized i was also curious what his food tasted like.
evolutionary anthropology laughed from the corner.
I wrote a piece about physics-informed neural networks. You can read it by clicking the link. Sending my best! #PhysicsInformedNeuralNetworks
https://t.co/VmlOIioqlJ
@techwith_ram congratulations! it's great to see physics-informed methods consolidated in a solid textbook form. i noticed electromagnetism is only light touched for now. if you ever plan to expand that direction i would be happy to contribute or share experience from recent EM PINN work. 🥳
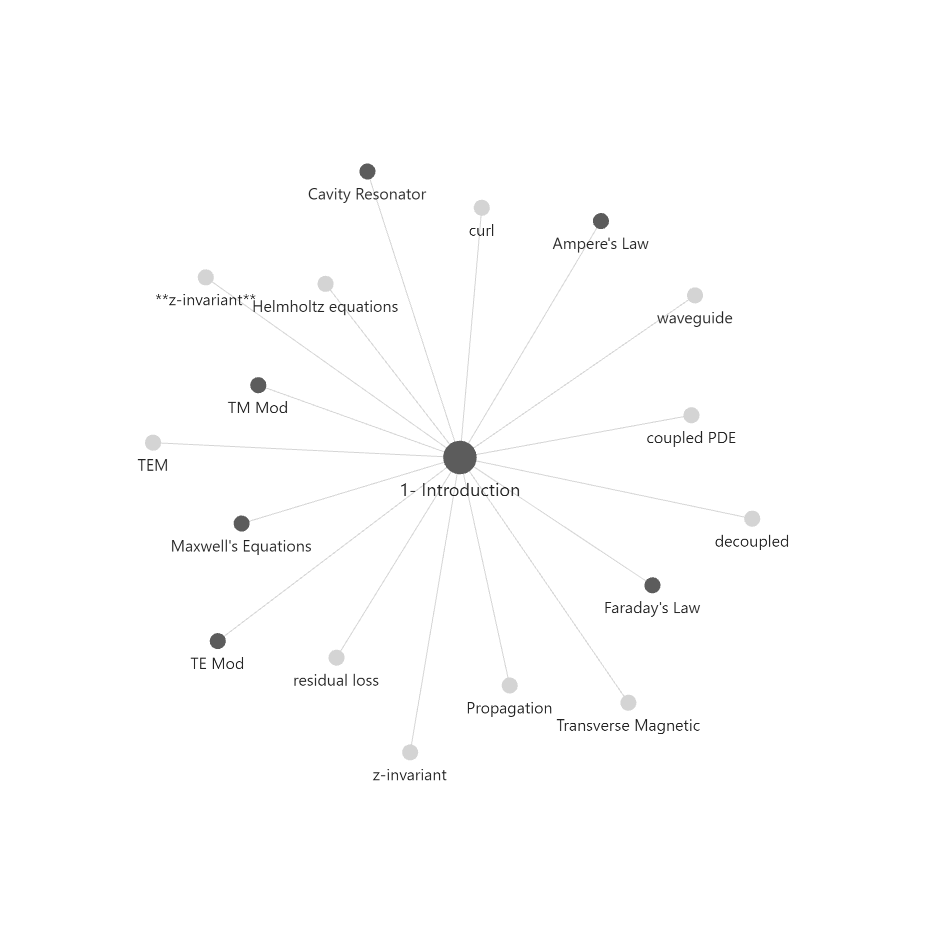
Preprint is out: PINNs for Electromagnetic Wave Propagation. Have a look if you’re into PINNs/EM. Code & docs on GitHub soon. ✨
#PhysicsInformedNeuralNetworks
https://t.co/WJ4uKDpZjL
first real job: designing a planar motor + levitation setup. the pay wasn’t exactly life changing but hey, at least now i get to pretend i'm an electromagnetic wizard. give me a decent magnetic array and enough coils, and i can make objects hover and move around in midair.
so the architecture and computational flow of neural networks are actually quite transparent. the reason they are considered black boxes is not a structural issue but a matter of interpretability.
when we say that neural networks are black boxes, it seems to imply that we cannot see how they work, but in fact we can see how neural nets work. for example, feedforward nets are by nature directed acyclic graphs, and their structure can be observed completely transparently.
even though RNNs and LSTMs seem to contain cycles, we can express them as DAGs as well. it is just a compact representation that expresses the reuse of the same parameter set over time. when we run an RNN for inference, the cycle becomes unrolled anyway.
indoors i measured 142 lux, but when i point my phone to the sky, it jumps to 33,000 lux. without measuring i’d just think “well, it’s bright outside.” the way our brains adapt to such a huge range still amazes me.
So there is a type of RNN that follows a simple form y_{t+1} = y_t + f(y_t, x_t). It has a state size that scales to billions of dimensions, handles sequence lengths in 10s of millions and has excellent memorization capability.
You might have guessed it, I'm talking about SGD.