AI business with zero moat: Vanilla Inference
A very small number of the best teams in the world might be able to build a long term business around inference based on owned fullstack infrastructure or full stack software for fine tuning etc or both.
The rest will look like the 1000s of hosting companies we saw in the late 1990s.
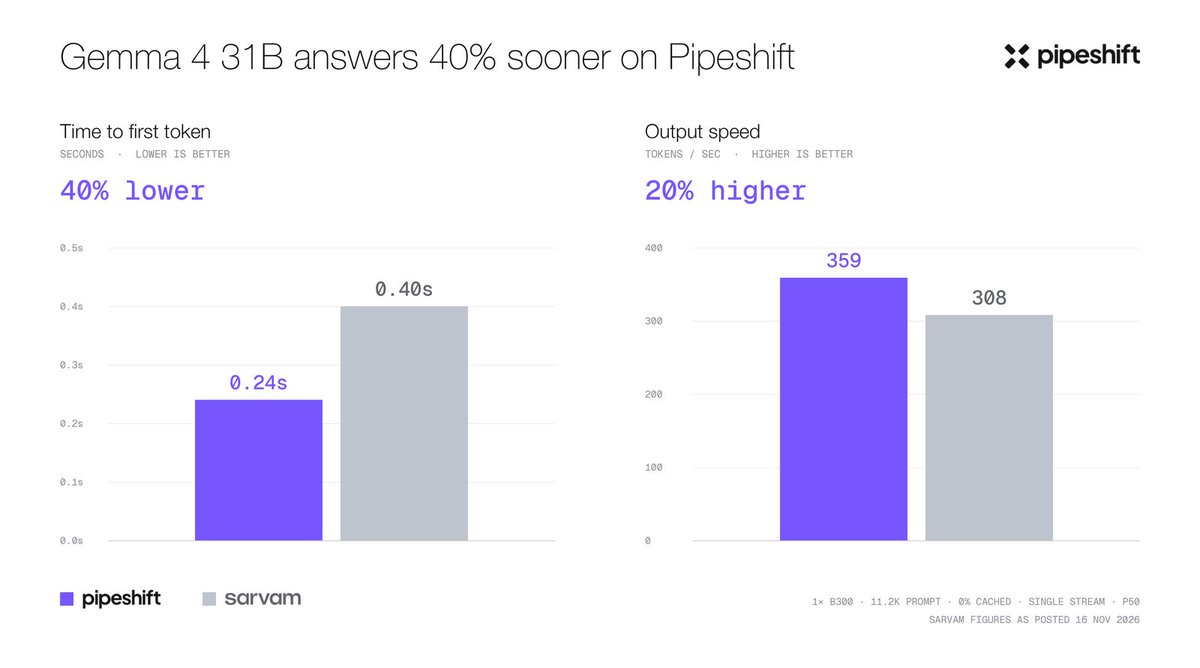
For real-time conversations, Gemma 4 31B is an efficient model that combines agentic capability with Indian language support.
On Sarvam Token Factory it returns its first token 5× sooner and generates 1.6× more tokens per second than the only other provider serving it.
We are already serving 150 billion tokens per day of Gemma 4 31B.
Today, we are launching Sarvam Token Factory for everyone.
We host our own models, and the full range of best-in-class open-weight models, in India. We match leading inference providers on performance and reliability.
For enterprises, this means more models to choose from, and an AI stack they can own without lock-ins.
overheard in Indiranagar today
founder:
our moat is rupee billing for tokens + govt subsidized gpus.
vc:
here’s $100m that we don’t wanna make returns on.
🤫
I've recently talked to quite a few people recently who believe they can just rent B300 nodes, install @vllm_project / @sgl_project, plug into @OpenRouter, and start printing money.
I think they seriously underestimate how hard the inference business has become.
A few facts everyone should know:
- Getting listed is extremely hard now! OpenRouter reportedly gets 40 provider applications every day and only approves 1. It could take months just to get listed!
- Competition is brutal! There are already 80+ providers serving @deepseek_ai models. Unless you have done extreme optimizations, you won't get any meaningful traffic!
- Some competitors aren't even trying to make money! Some providers intentionally price below cost to attract traffic. They treat the losses as marketing spend, and no one can even compete the price!
I think the era of simply hosting open-source models and selling tokens is coming to an end, especially for new entrants.
The real opportunity is moving up the stack. Sell solutions, not tokens.
All flights bound for the US are suspended until further notice, per US Federal Aviation Administration - which has issued the order citing extraordinary circumstances.
We've scaled past $100M run rate and we still don’t have a product roadmap.
If 5-10 customers from completely different verticals ask for the same thing in the same week, we build it immediately.
It’s happened at least once a month since we started. Every single month, something new gets requested in a cluster and we start moving on it.
Other than that, there are no quarterly commitments / annual planning.
comparing a 7yo company with a 37yo company already tells you why a nebius will not have the same upside and ceiling as a baseten.
nebius has spent $1.5b acq companies that can help them build the inference platform to look like a baseten.
the talent and customers that go to baseten aren’t the same. nebius is never their first choice.
for one it’s the platform is the core business and for the other it’s their s1 checkbox to show “path to margin expansion” or “path to profitability”.
building data centres against inference demand is a far more viable and scalable product business than trying to upsell inference as an org trained to buy and sell commodities (gpu).
received this email today.
open models >>>> closed models
but this is outright unethical.
i’m all for post training and truly believe that open models will win.
we’re probably 1 of 1000s of startups who these people mail.
@OpenAI@AnthropicAI@GeminiApp