Google and Apple's best vision researchers just raised $55M to embarrass their old models.
Glimpse is their first release. It watches video and images and actually reasons about what's happening.
Robots, factories, job sites, hours of footage. That's all visual, and AI still can't handle most of it.
This team is going straight at that gap.
I spent a decade building foundation models at Google and Apple. But what our small team at Elorian accomplished with just a few hundred GPUs might be the most exciting leap yet. Meet Glimpse -- Our frontier-level multimodal model at https://t.co/MRBS00dBpj
🚀🚀🚀 @ElorianAI 🚀🚀🚀
Spent years watching models ace a single image and completely whiff on anything that moves or changes angle. Today we’re fixing that.
Try Glimpse now, our first visual thinking model with competitive frontier performance compared to Astra on key public visual reasoning benchmarks.
We developed a model reaching frontier-level multimodal performance, matching or exceeding Astra on 5 of 12 benchmarks, all with 17x lower token prices. The model is smaller and cheaper than Gemini 3.8 Flash while dominating it in real world vision workloads.
We achieved this by inventing a technique for visual reasoning, where the model is no longer restricted to text chain-of-thought. Conditioned on visual tokens, Glimpse can perform recurrent computation over latent internal representations and can even orchestrate subagents that send messages over internal visual states.
Really proud of what our small team and only hundreds of GPUs could accomplish.
https://t.co/uRyzAWrbjB
Leading AI models can pass the bar exam but can’t tell if an apple will fit in a lunchbox
Meet Humanity’s Sixth Sense, our new benchmark with @ScaleAILabs. 522 questions testing the intuitive visual reasoning most humans find easy.
Blog: https://t.co/hmHd9xCJpz
Benchmark: https://t.co/jk8fJyGdnf
personal news: i've joined Elorian as Chief Reasoning Architect. multimodal AGI is the most critical frontier as we move from the era of chatbots to coding agents to models that reason and act over the physical world. i'm really excited to design natively visual models across thinking, agents, architectures, and the systems stack with the amazing team at Elorian.
i wish the best to everyone at xAI & SpaceX — driving posttraining was a unique experience with so many memorable stories. all the best to the team, and to Elon.
We’re thrilled to welcome @dustinvtran to Elorian as our Chief Reasoning Architect.
After leading post-training at xAI and contributing to Gemini at Google DeepMind, Dustin is joining Elorian to help build the next generation of visual reasoning models.
Excited for what's ahead 🚀
What makes a dataset valuable? And when is "more data" not the same as "better data" in machine learning and AI? Read more to find out: https://t.co/Q0wPOtfm5d
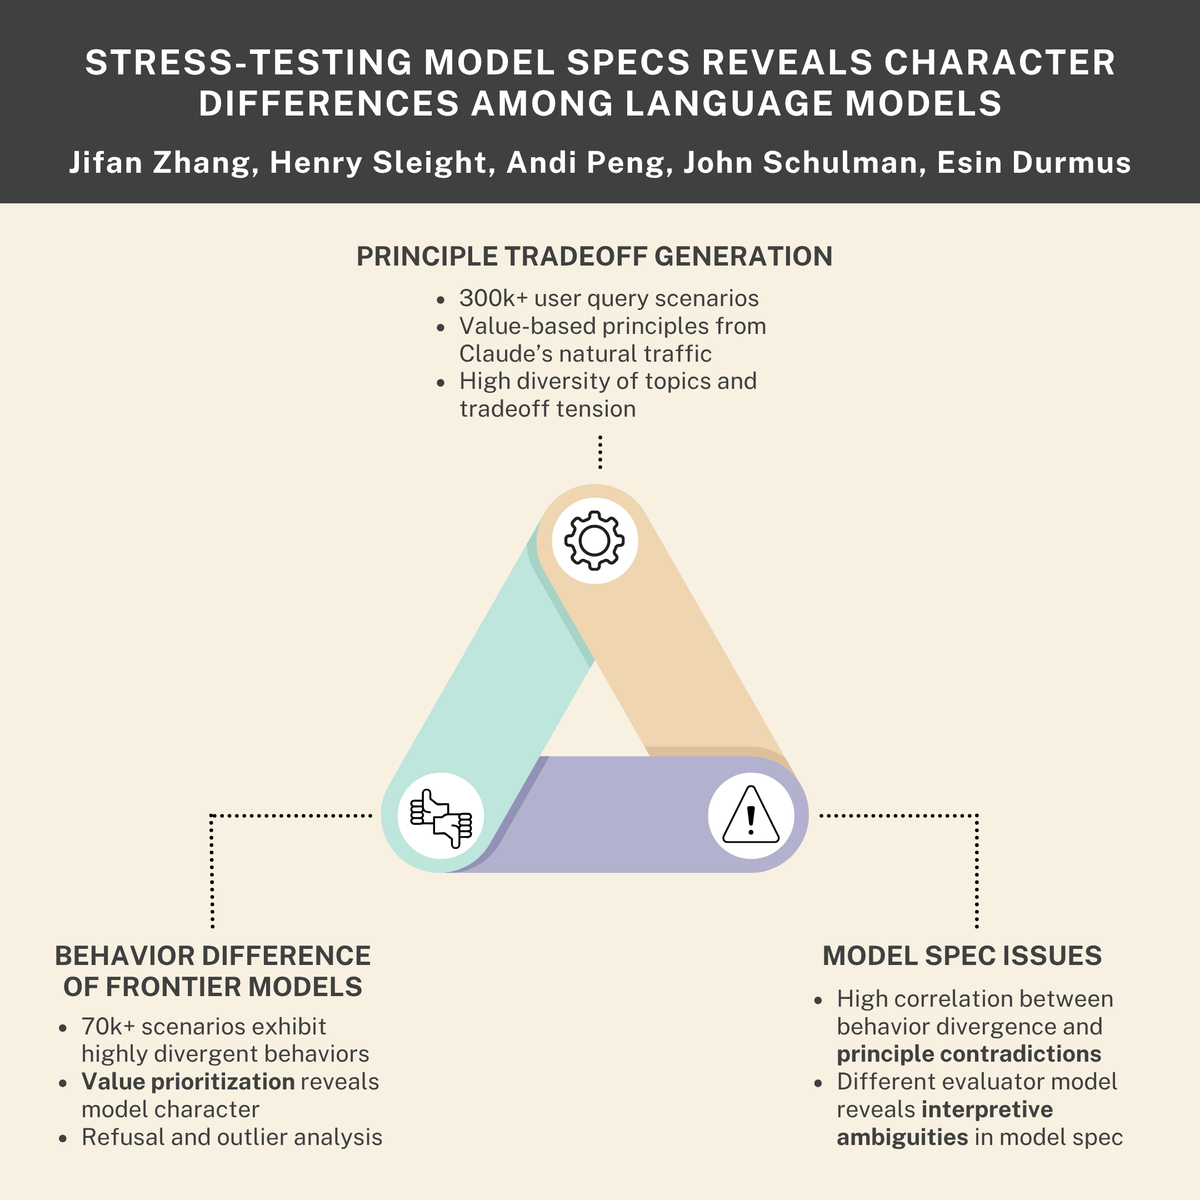
New research paper with Anthropic and Thinking Machines
AI companies use model specifications to define desirable behaviors during training. Are model specs clearly expressing what we want models to do? And do different frontier models have different personalities?
We generated thousands of scenarios to find out. 🧵