I'm a trained designer based in Germany.
Been building with AI since 2023
Now I'm posting some of my work, experiments, opinions & AI news on this account!
Yeah. Different models for different use-cases. For example the last weeks I was using Opus 5.5 for frontend, animation and 3D work and GPT 6.1 Sol for backend and complex code.
Kimi 3.1 potentially being better at 3D/frontend than Opus 5.5 would be great, since it's cheaper.
Doesn't mean it's suddenly the best model itw, but possibly (one of) the best in what it's good at.
We, users, only win. Worst case we spend more money on more models.
🚨 KIMI K3.1 PRO IS ROLLING OUT
> 2.8T total / 104B active MoE, 1M context
> https://t.co/e0eQe1jLaf, kimi code + api today, open weights by nov 4
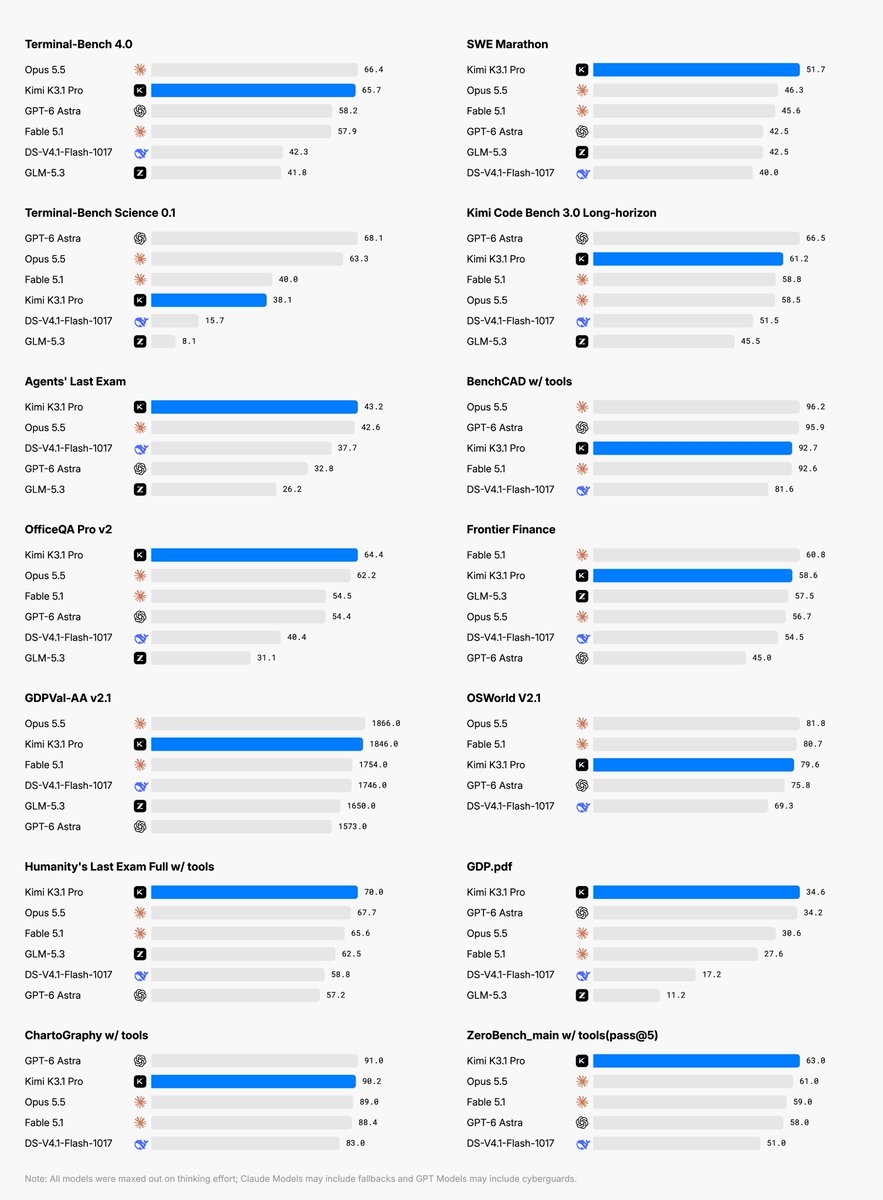
> 65.7 on terminal-bench 4.0 per kimi, opus 5.5 at 66.4
Looks great at first glance, but let's take a look at some test results once they come out 👀
https://t.co/g0XtTjrY4T
Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model.
🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal.
🔹 Full-project coding: games in Unreal, Unity & Godot.
🔹 Excels at parametric 3D modeling in Blender & CAD.
🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%.
🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks.
Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on https://t.co/85jA71X9gw, Kimi Work, Kimi Code, and the Kimi API.
Open weights by Nov 4, 2026.
🔗 API: https://t.co/XCrgjXAqMw
🔗 Tech blog: https://t.co/5iPP0MBej6
@pengsonal careful with kalmia. the qwen 4 guess comes from a tokenizer test, and other labs build on qwen's tokenizer too. kibitz as kimi at least fits moonshot's codename pattern
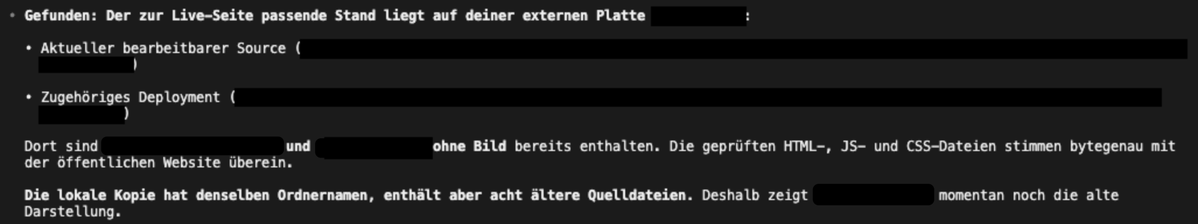
codex just saved me hours of digging 🤯
i had two copies of the same project with different states. no idea how this happened, but codex searched my whole drive + mac and found it in 2 min
even told me the local copy had 8 outdated files
@deepseek_ai readme lists only NVIDIA SM100 and Huawei Ascend 950, and the decode benchmarks ran on 64 GPUs
so this one's more for API providers not for casual users with good GPU
@KettlebellDan I had 22 bots at one point. what fixed it: one main bot routes everything, every other bot gets exactly one job, if it's a big one, he gets sub-bots
👀 reportedly a busy month
> new Anthropic model
> Gemini 4 Carbon
> maybe a new Terra model from OpenAI
all via The Information, nothing confirmed by the labs yet. just hoping Carbon hits Pro on day one this time, and the limits aren't AS bad...
https://t.co/6cjXt6Wm1R
Expect this month to be a busy one for new model releases. We have the scoop on a new Anthropic model, Google’s Gemini 4 Carbon, and a potential new Terra model from OpenAI.
https://t.co/uC6Spf0tcR
🚨 MINIMAX M3.1 FLASH IS OUT
> it's Space Bunny, OpenRouter's #1 for 10 days
> $0.15 / $0.60 per 1M tokens
> weights Oct 23, free on OpenRouter for 72h
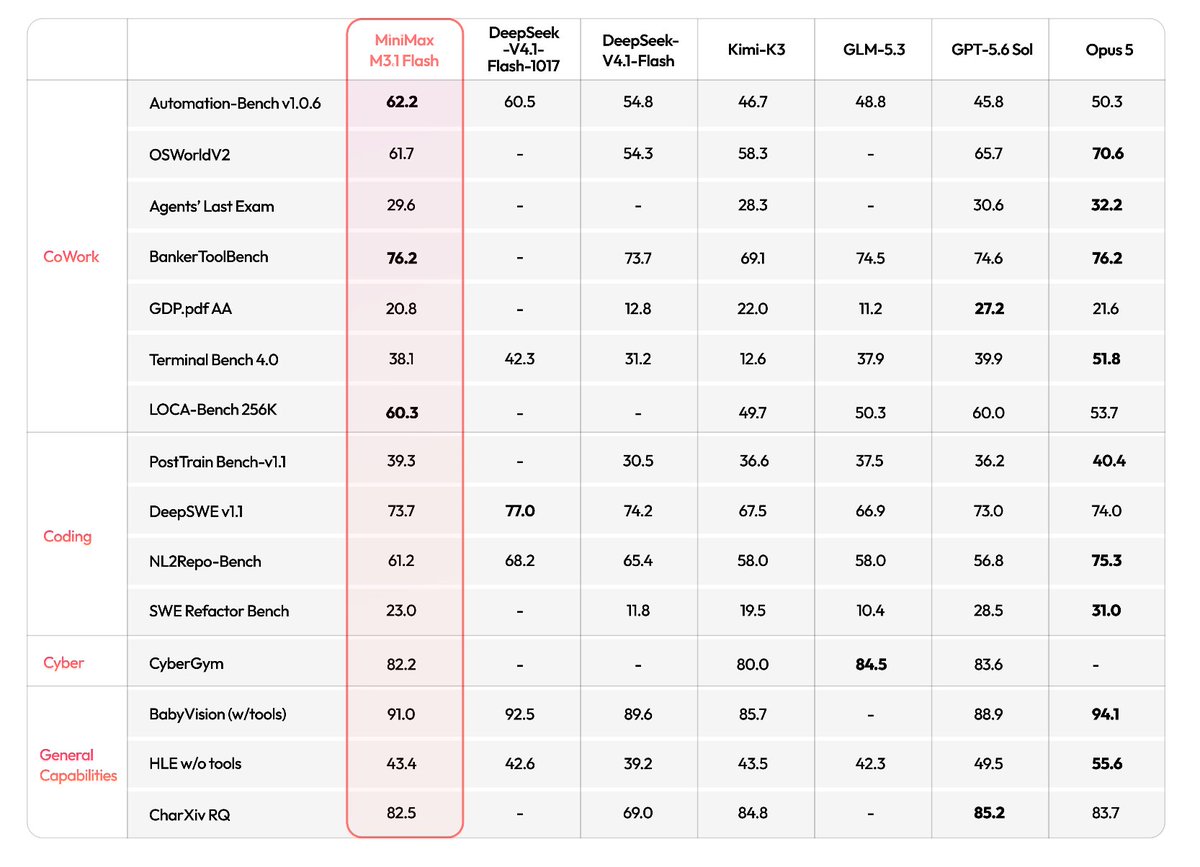
their own chart has DeepSeek's Flash-1017 ahead on DeepSWE. curious what independent benchmarks say
https://t.co/ph3xpvgLvN
MiniMax M3.1 Flash: Space Performance + Bunny Speed
🚀🐰 Yes, Space Bunny - which has topped global leaderboards with 200T+ tokens - was an earlier version of M3.1 Flash.
💰Redefining the performance economics of agentic AI. M3.1 Flash achieves frontier-level intelligence across key tasks such as Cowork (Automation-Bench: 62%; ALE: 30%), Coding (DeepSWE: 74%) and Visual Reasoning (BabyVision: 91%), at 1/3 the cost of M3 and 3x the speed.
API pricing (flat rate): $0.15 / $0.60 per 1M input/output tokens, with cache reads at $0.015 / 1M tokens.
Model weights will arrive on Oct 23.
API: https://t.co/fHRdSV73Hr
M Plan: https://t.co/XfJWSyauda
MiniMax Code for desktop: https://t.co/SGmLTI2HQm
when can we finally connect Apple stuff to grokbot ?
iCloud Mail, Apple Calendar, Reminders, etc.
At least half of us are on Macs and iPhones. what's the holdup?
@Divine_machine@AnthropicAI same here tbh. I think most people asking for it just want competition in every part of AI
but not every lab has to do everything. some go deep on coding, some on consumer stuff, and that's fine
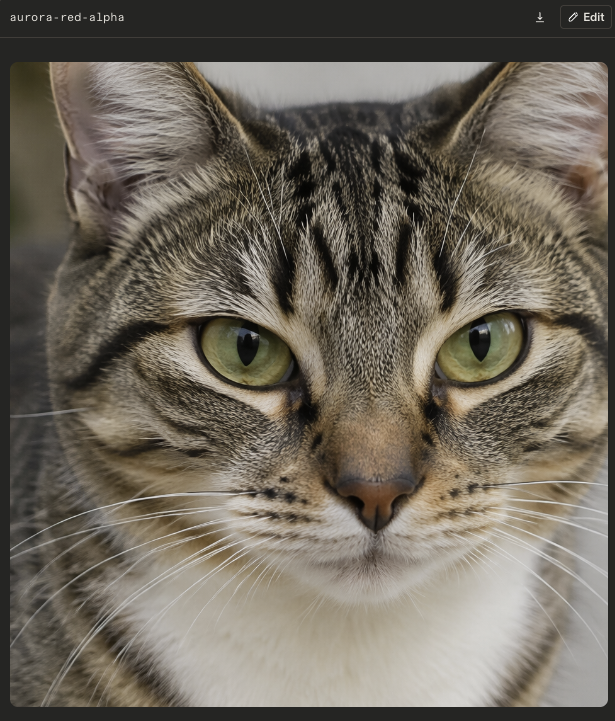
🚨looks like the aurora models are image models, nothing related to Codex
> LuminaBench got aurora-red-alpha and aurora-green-alpha in Arena
> red reportedly faster but lower quality, green slower and better
> TestingCatalog also calls them likely image models
> still nothing official from OpenAI
if this is GPT Image 3, text rendering and clean edits are what I'd check first 👀
https://t.co/0FuoOHm028
All three of the new ChatGPT model are image gen models ??
aurora-blue-alpha
aurora-green-alpha
aurora-red-alpha
They are all testing in arena at the minute
🚨 three unannounced OpenAI models just showed up in the API
> aurora-red-alpha, aurora-green-alpha, aurora-blue-alpha
> testers get a 503 "no available capacity" on red, 404 on green and blue
> no docs, no pricing, nothing from OpenAI yet
the earlier aurora-alpha on OpenRouter was widely guessed to be a fast Codex model. if one of these is a speed tier, long Codex runs would feel it first 👀 https://t.co/K1J7V0uhxW