Hello Ottawa,
Excited to connect with fellow researchers and dive into new ideas this week.
I’ll also be presenting a paper—looking forward to sharing my work!
#icse2025#icpc2025#RaiseLab#DalhousieUniversity
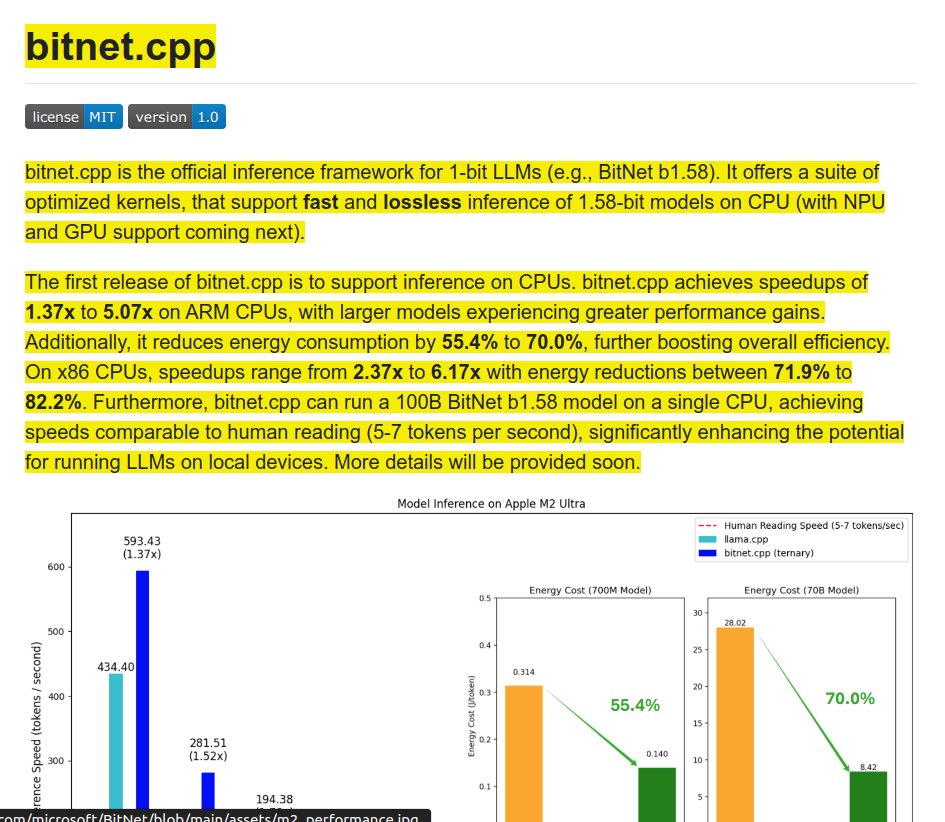
WOW. @Microsoft just open-sourced the code for one of "THE MOST" influential Paper of 2024 🔥
1-bit LLMs (e.g., BitNet b1.58).
Now you can run a 100B param models on local devices quantized with BitNet b1.58 on single CPU at 5-7 tokens/sec 🤯
The dream we have all been waiting for.
📊 Performance Improvements:
- Achieves speedups of 1.37x to 5.07x on ARM CPUs
- Larger models see greater performance gains
- Reduces energy consumption by 55.4% to 70.0% on ARM
- On x86 CPUs, speedups range from 2.37x to 6.17x
Mohammed Qahtani won the Toastmasters World Championship of Public Speaking. It’s easy to see why.
Please watch his speech. Words have power. Words can unite or divide. Words can spit venom or can mend a broken soul. Words absolutely matter.
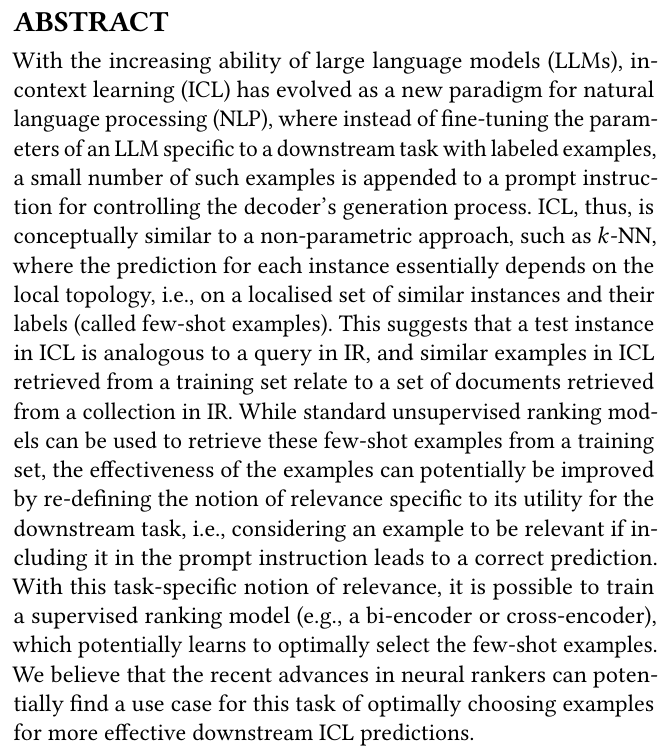
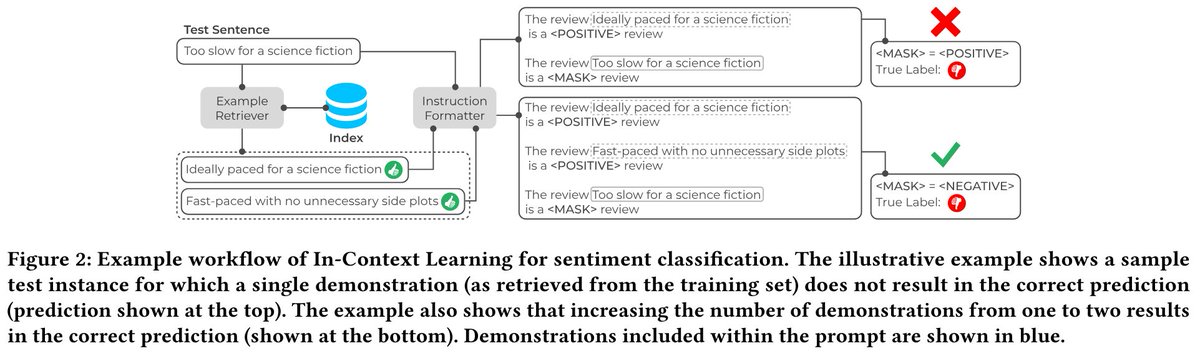
"In-Context Learning" or: How I learned to stop worrying and love "Applied Information Retrieval"
Draws an analogy between ICL for LLMs and IR, proposes IR techniques to improve few-shot example selection and enhance downstream genAI tasks.
📝https://t.co/0J9cMJVBrq
Introverts are attracted to authenticity. They don't care about how you look or the zeroes in your bank, they care about who you are as a person. Your wit. Your wisdom. Your idiosyncrasies. The rare inside you.
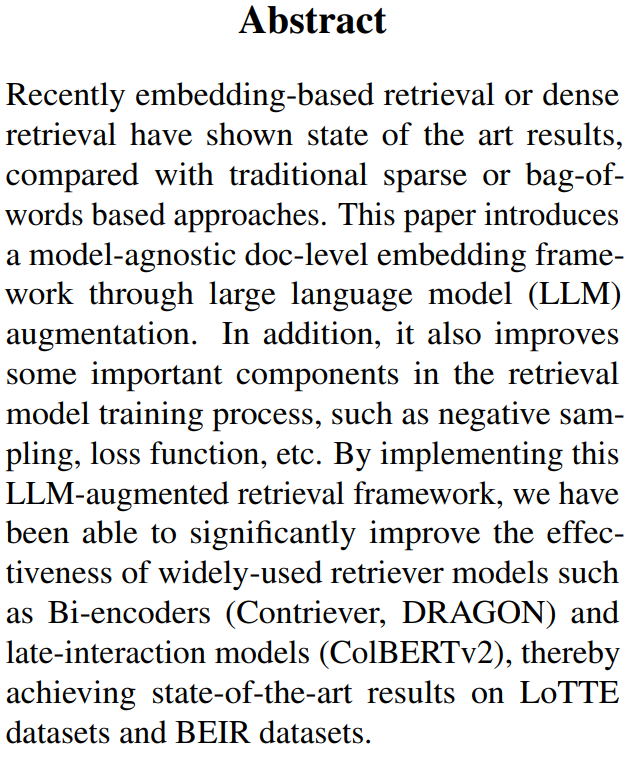
LLM-Augmented Retrieval: Enhancing Retrieval Models Through Language Models and Doc-Level Embedding
Improves the performance of existing retriever models by enriching document embeddings with contextual information.
📝https://t.co/wfZ3beaA4d
Introducing `gemini-youtube-researcher` 📈
An open-source Gemini 1.5 Pro agent that LISTENS to videos and delivers topical reports.
Just provide a topic, and a chain of AIs with access to YouTube will analyze relevant videos and generate a comprehensive report for you.
Language models struggle to search, not due to an architecture problem, but a data one! They rarely see how to search or backtrack. We show how LLMs can be taught to search by representing the process of search in language as a flattened string, a stream of search (SoS)!
Introducing `claude-researcher` 📈
A powerful Claude 3 research agent that delivers thorough reports in record time.
Just provide an topic, and a chain of AIs with **access to Google** will generate an incredibly comprehensive report for you.
And it's open-source!
This is just science - go for a walk.
This paper found walking (whether outdoors or a treadmill) increased key types of creative thinking for over 80% of undergraduates. The reasons are not fully clear, but there seem to be direct effects on the brain https://t.co/0EDfpzxHiL
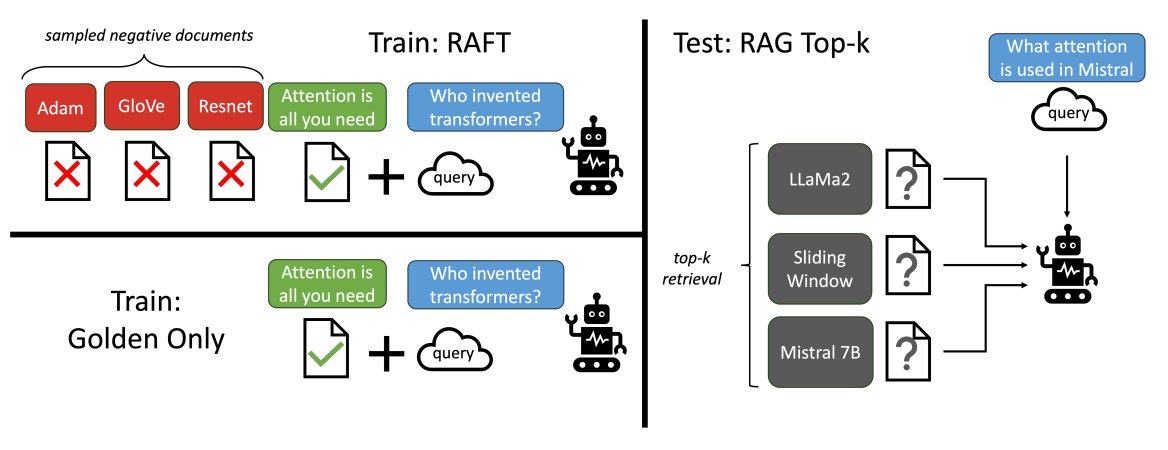
RAFT - Retrieval Augmented Fine Tuning 🔥
RAFT offers a method to fine-tune pre-trained LLMs for specific domain RAG settings.
Conventional RAG is like an open-book exam, retrieving documents from an index to provide context for answering queries. This makes it more effective than the closed-book exam setting where LLMs rely solely on their pre-training and fine-tuning to respond to prompts, but doesn't allow the LLM to learn the domain beforehand.
RAFT from @tianjun_zhang, @shishirpatil_ proposed a fine-tuning approach that enhances LLMs for domain-specific open-book exams, where the model is trained to attend to relevant docs and ignore irrelevant documents.
RAFT creates a synthetic dataset where each data sample consists of:
1️⃣ A question
2️⃣ Two docs: An "oracle" document relevant to the question, and a "distractor" documents irrelevant to the question.
3️⃣ An answer generated from the documents
4️⃣ A Chain-of-Thought explanation including excerpts from the relevant documents.
The created synthetic dataset is further used for fine-tuning to improve RAG performance.
Thanks to @ravithejads, you can now generate RAFT dataset using our brand new RAFTDatasetPack LlamaPack.
LlamaPack: https://t.co/TznwFsq16r
Video Tutorial: https://t.co/bQVVCvvgdS
Paper: https://t.co/zXrn5F6eWn
@xennygrimmato_ Nope. Only a multi vector model like ColBERT would work at that length. If you could make me one and open source it that would be great! 🤗 Or just have your colleagues turn this into one: https://t.co/OYcMX8IH3Q
Introducing `claude-prompt-engineer` ✍️
An agent that creates optimal Claude 3 prompts.
Just describe a task, and a chain of AIs will:
- Generate many possible prompts
- Test them in a ranked tournament
- Return the best one
And it's open-source: https://t.co/nrivU2BWmn
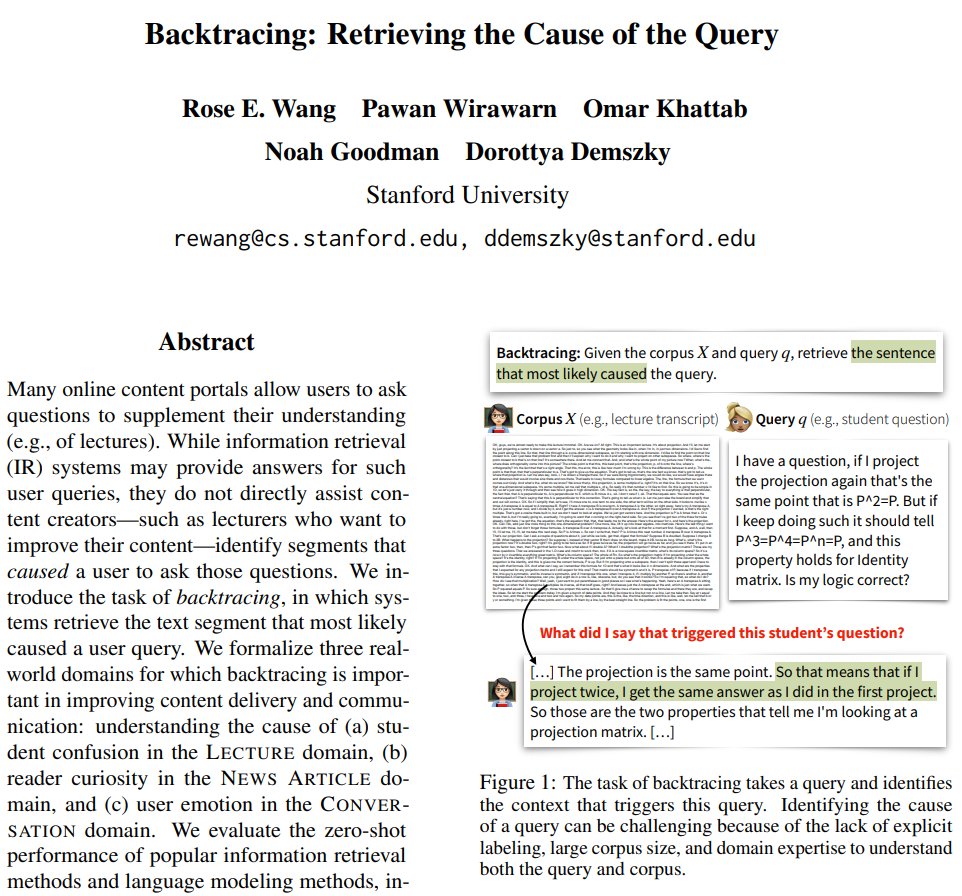
Backtracing: Retrieving the Cause of the Query
- Proposes a new task called backtracing where the goal is to retrieve the cause of the query from a corpus
- Shows limitations in current retrieval methods for performing backtracing
repo: https://t.co/ODgAB2zhA9
abs: https://t.co/EHj4waR8ZT
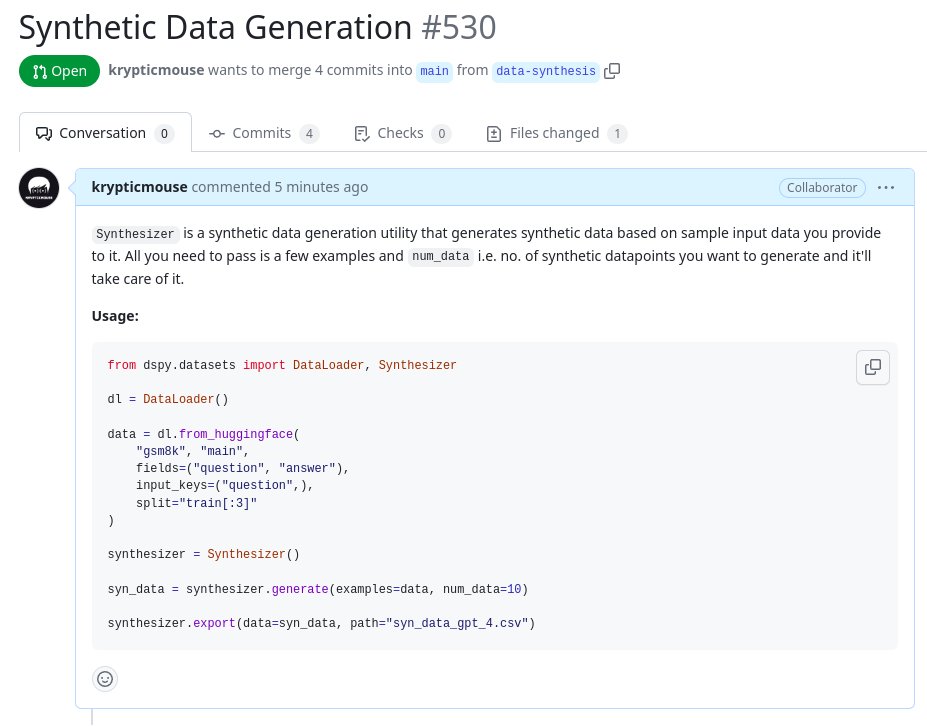
New to DSPy 🚀
Adding a Synthesizer class to generate synthetic data based on examples you provide!
Provide 3-5 examples from a dataset to the Synthesizer and it'll understand the task, generate data for input fields, and the output fields. Works great with gpt-4-preview!
You can export the data to CSV, JSON, or hf format too!!