Thrilled to announce that my paper, CALM: Class-Conditional Sparse Attention Vectors for Large Audio Language Models has been accepted into EMNLP Main Conference!
Excited to present it in Budapest in October 🇭🇺
https://t.co/F6HE2vwYO0
It feels like new AI accelerators are released daily, but the real bottleneck has always been the software needed to make them truly usable.
Hawkeye designs a minimal set of operations that provide coding agents with the concise and highly valuable information needed to bootstrap hardware aware optimizations for achieving performant kernels.
As a result, we are able to beat expert baselines over a variety of workloads!
We see in recent trends that models are increasingly able to even one-shot SOTA NVIDIA kernels, this work is exciting to see how we can harness these model's capabilities for new and unfamiliar accelerators.
Cool work with amazing collaborators!
Our research team has 9 papers at ICML next week!
Spanning the full stack from frontier agents to GPU kernels, we're excited to share what our researchers and collaborators have been working on.
If you're in Seoul for ICML come meet our team or catch a talk! 🧵
Excited to release PKB Parallel Kernel Bench, led by Willy Chan and Nathan Paek @asplencmnt!!
A benchmark of mostly net-new multi-GPU kernel problems (solutions are independently useful for real-world workloads).
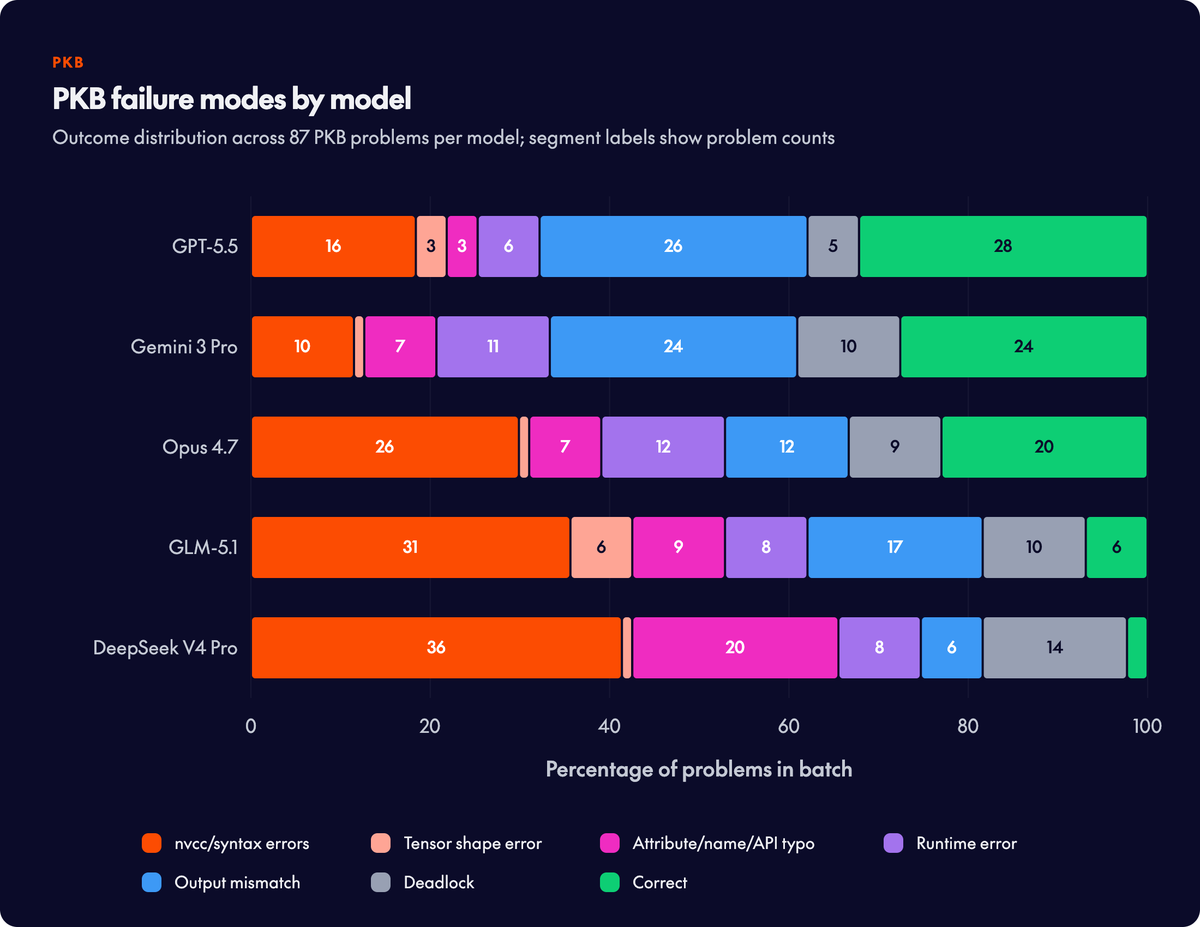
LLMs write fast single-GPU kernels. Ask for a multi-GPU one and they fall apart.
ParallelKernelBench measures how they fail by benchmarking against 87 problems pulled from real codebases including Megatron-LM, DeepSpeed, DeepEP, TensorRT-LLM, NeMo-RL.
New research from Willy Chan @asplencmnt@simonguozirui@simran_s_arora and @realDanFu
Super grateful to my coauthor Willy Chan, collaborator @simonguozirui, and awesome mentors @simran_s_arora and @realDanFu! And huge thanks to @togethercompute for making the project happen! Check out PKB here:
Blog 🌐: https://t.co/pTv4NBoBvd
Paper 📜: https://t.co/66ehPrU7nv
GitHub 💻: https://t.co/IPN65KRHgZ
HuggingFace 🤗: https://t.co/yDfidzRywJ
Excited to release ParallelKernelBench (PKB), a benchmark for measuring LLMs’ ability to write fast multi-GPU kernels! 😀
Multi-GPU kernel generation compounds several hard problems:
- a large parallelism design space
- a new communication axis to optimize
- and hardware-specific decisions around communication mechanisms
Existing kernel-generation benchmarks mostly target single-GPU workloads, so we built PKB to cover real-world multi-GPU workloads (many of which do not have existing optimized solutions). 🧵👇
That said, a few models did find solutions faster than the original repo code, producing net-new kernels! The example below speeds up a real vision workload.