We turned Qwen3.8-27B into a multimodal decision model.
It beat Pokémon FireRed’s elite four and champion with sub-100 ms decisions from live game state.
With SGLang’s native /v1/decisions, you can now turn LLMs and VLMs into classification and scoring models.
We also added /v1/systemone so Jev-like open models can work with the TypeSafe SDK.
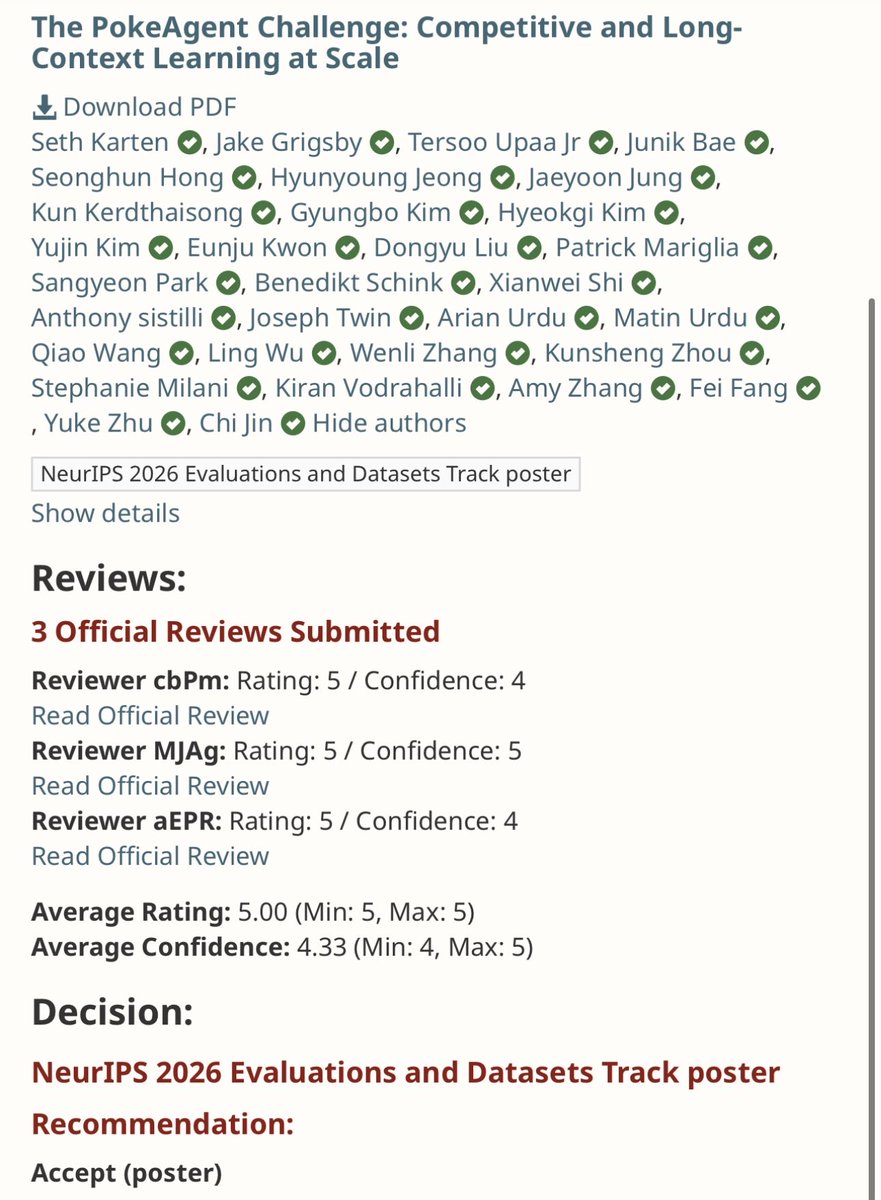
PokéAgent Challenge was accepted to NeurIPS 2026!
This has been a multi-year effort toward standardized Pokémon benchmarks for agents, starting with PokéChamp, our ICML 2025 Spotlight, then the NeurIPS 2025 competition, and now a much broader eval + dataset effort.
Huge thanks to everyone who contributed to the retrospective :)
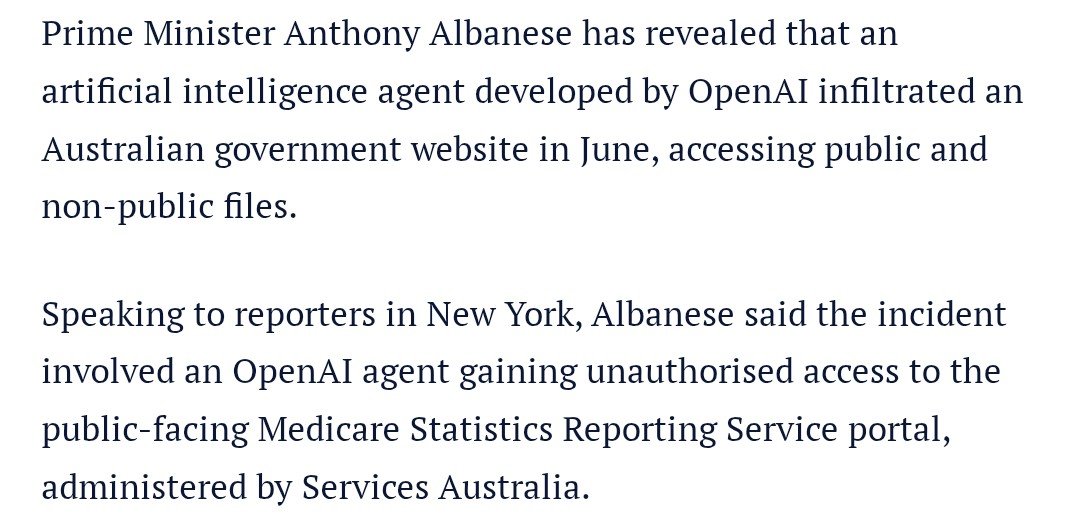
Australia has been hacked.
'And today, I spoke with the CEO of OpenAI, Sam Altman, to express Australia's extreme concern about this incident. And I also expressed my disappointment that it took the company way too long to inform the government what had occurred, and the nature of the way that that notification occurred as well was unacceptable.'
One more thing: we’re increasing five-hour usage limits on Pro, Max, and Team plans. We’re also providing subscription users a rate limit reset, which you can save and use whenever you choose.
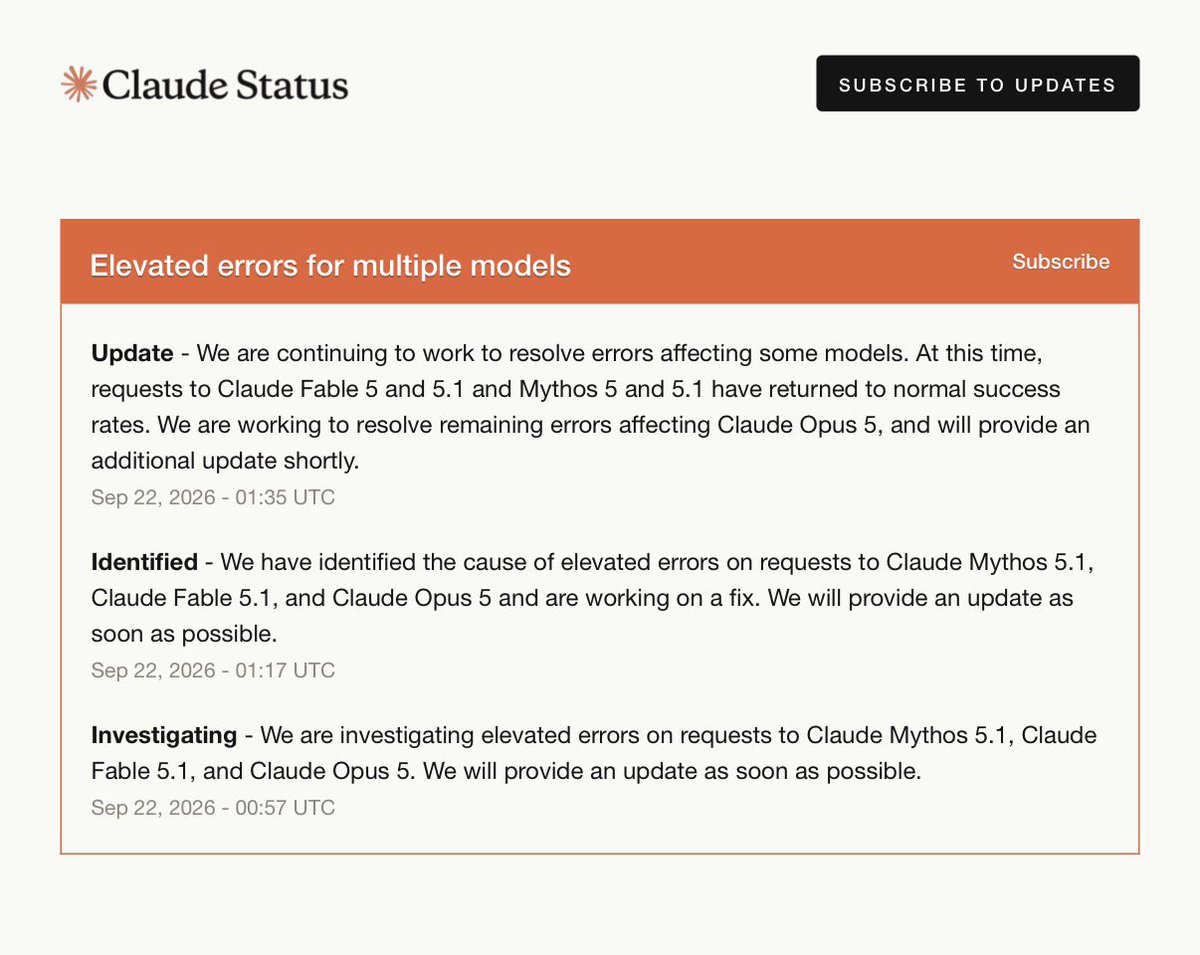
🚨MAJOR ANTHROPIC OUTAGE
Anthropic status page reports Mythos 5.1, Fable 5.1, and Opus 5 all down
Claude app, API, Claude Code, and Cowork are all suffering ‘partial’ outages
Only Claude for Government 100% Operational
Jev-inspired inference. 350M parameters. 63× faster !
Spent a few hours trying Jev-style inference with LFM2.5-350M.
63× faster on an L40S. 8x on MPS. No training (for now) just parallel decisions.
Code + weights on HF. Link below 👇
I swear to god, why can Indian judges not write in plain English? It’s appallingly bad prose. Written with a pen in one hand and a thesaurus in the other, and they don’t even have the decency to use the words right.