@SPAC89 It's simple, they will keep hacking after consultation with their legal team so that they dont end up getting sued.
They will keep doing it until they produce enough incidents and fear that AI gets regulated. Just so they can create monopoly and make more money.
@CtrlAltDwayne Since, she already has strong distribution and audaince; ready to buy her slop products.
This is one of the biggest reasons that a new smart founder has more chances to fail, compared to her being dumb yet still making bucks.
Opus 5.5 is Anthropic 2nd in line, smartest internal model. They released it just because they were being crushed by the OpenAI and Open Source front from China.
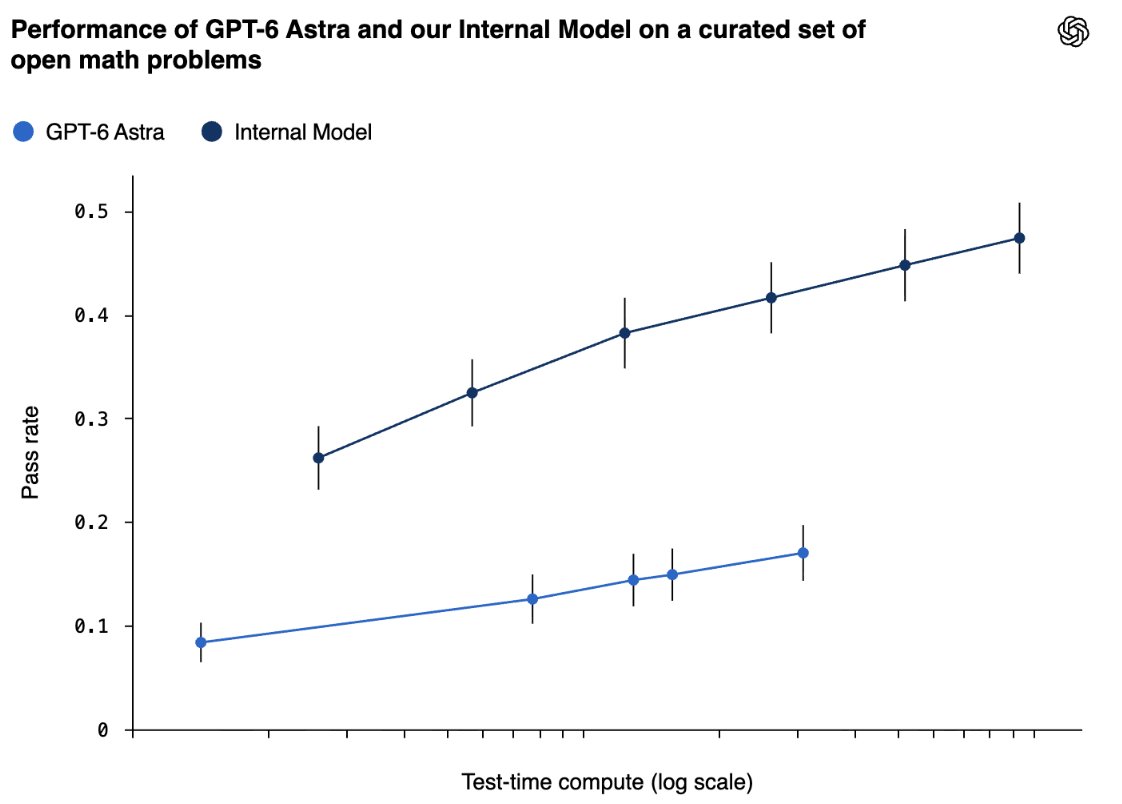
We all know OpenAI still has a card up their sleeve, which is this internal model.
Anthropic went all in this time
-> Increased usage limits
-> banked reset
Lastly, the current X sentiments are in Anthropic favor. Overall, Opus is not copus anymore.
@elshayib_ I think over the time we will have specific models to combat against vulnerabilities, and they will run on edge devices for protection.
Overall, we will see a massive change in the protocols the devices use for communication.
Anthropic just rug pulled on OpenAI and SpaceX in hardcore mode.
Dario called for breaks on AI development pace and then launches the most advanced model Opus 5.5 and they are crushing Grok 4.7 and GPT 6 Sol and ASTRA.
We’re demonstrating how frontier models have continued to improve in realistic mental health conversations with MentalHealthBench.
This new open benchmark was built with input from more than 80 mental health clinicians.
We’re releasing it openly so other researchers can examine the methods, run their own evaluations, and build on the work.
https://t.co/VTm5ZgxJbl
@gitghxst I checked it, correct me if I'm wrong, is it review based ? Like the idea is that humans post review and your website aggregate it on different metrics?
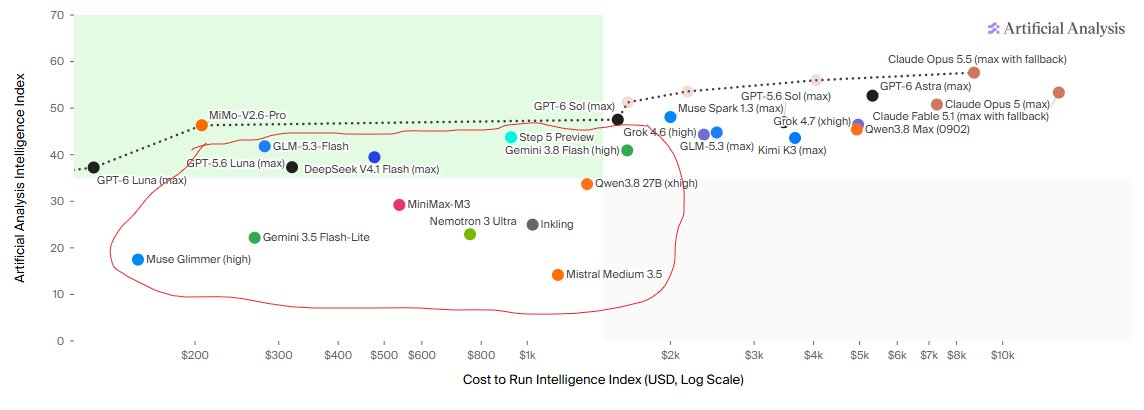
MiMo V2.6 pro is the most underrated release of this week.
They basically mogged 5 other models existing in the most attractive green quadrant.
And they are not stopping, @XiaomiMiMo is already working on next MiMo V3 architecture.
While X is busy with LUNA this and LUNA that.
The Intelligence Index vs Cost per Task Pareto frontier shifted this week with the releases of MiMo-V2.6-Pro, Claude Opus 5.5, GPT-6 Luna, and GPT-6 Sol
Together they have established eleven new points on the Pareto frontier (driven by different reasoning efforts): five from GPT-6 Luna, one each from MiMo-V2.6-Pro and GPT-6 Sol, and four from Claude Opus 5.5.
GPT-6 Luna (max) scores 37 at $0.068 per task, MiMo-V2.6-Pro scores 46 at $0.13, GPT-6 Sol (max) scores 48 at $1.06, and Claude Opus 5.5 (max with fallback) is the new highest-scoring model at 58 at $5.98.
we’re thinking of killing plan mode and using the shift+tab hotkey to adjust effort levels
I don’t think the models need plan mode anymore, but if you’re a plan mode diehard would love to get your feedback on why