Je suis d'accord avec Le Cun là dessus, et c'est orthogonal à l'étude d'Anthropic sur le J-space.
On sait (cf papier en commentaire) qu'un LLM est limité par sa profondeur (nombre de layers) à une certaine complexité maximale de problèmes.
En gros, pour un problème qui demande de panser à N coups d'avance (par exemple un "mat en N coups" ou le problème des tours de Hanoi), si la profondeur de ton LLM n'est pas supérieure à une fonction polynomiale de N, il n'y arrivera pas du tout.
C'est pour ça que Chain-of-Thought a tant explosé les scores et, après avoir commencé comme un gadget "let's think step-y-step" en 2023, est devenu un mécanisme fondamental de TOUS les LLM auourd'hui: CoT est un excellent moyen pour le LLM de loop sur un input. Les LLM passe une fois sur l'input, en déduit un token, repasse sur l'input +1 token, en déduit un autre...
ça débloque toutes les classes de problèmes. C'est expliqué plus rigoureusement dans le papier en commentaire.
Maintenant, si on accepte ce framework de "les transformers son naturellement limités en complexité, et le CoT est un moyen de loop"
Alors la loop est en effet un peu pauvre, on ne passe que quelques bits d'info à chaque l'itération suivante. C'est d'ailleurs un problème que des architectures de Recurrent Transformers dont HRM ou TRM pourraient résoudre en passant de vrais vecteurs.
De son côté, le papier d'Anthropic porte seulement sur "comment se passe une forward pass", pas sur la CoT. Ils y voient des représentations vectorielles complexe, mais ça ne dit rien sur l'efficacité ou pas de la CoT.
Had a Jane Street interview in 2014
Round 7. Interviewer says 'meet me at Washington Square Park, southwest corner, 2 PM.'
I show up. He's playing chess with a guy who's clearly hustling tourists. Interviewer's losing badly.
Without looking up he says, 'Take my position.'
I sit down. The chess hustler looks at me and grins. 'Your boy owes me $40. You covering his position?'
I look at the interviewer. He nods.
'Assume the debt,' he says. 'Now optimize.'
I study the board. I'm down a queen and two rooks. Completely hopeless.
'This position is unwinnable,' I say.
'Correct. Now make it profitable.'
'What?'
The chess hustler is getting impatient. 'You playing or what, kid?'
The interviewer slides me a $20. 'Market make this game.'
I'm confused. 'How do I market make chess?'
'Bid-ask on the number of moves until checkmate. Hustler takes the under, you take the over. Spread is your edge.'
I look at the position again. Maybe 8 moves max until I'm mated.
'I bid 12 moves, offer 15,' I announce.
The hustler laughs. 'I'll take the under on 12 all day.'
'Done,' says the interviewer. 'You're now short volatility on a deterministic outcome.'
Three moves later I'm checkmated. I owe the hustler $40 plus my $20 bet.
'How confident were you in that 12-move bid?' the interviewer asks.
'0.95,' I say, because that's what you always say.
'0.95 huh?' He chuckles. 'You just sold insurance on the Titanic.'
He stands up. 'The real trade was shorting your confidence and going long on the hustler's experience. You missed the obvious hedge: offering chess lessons to tourists at $25/hour while the game played out.'
'But I don't know how to play chess well enough to teach.'
'Exactly. That's called selling vol you don't have. Very Jane Street.'
Offer rescinded. Reason: 'Failed to recognize that the park itself was the market and the pigeons were the only rational actors.'"
Dario is wrong.
He knows absolutely nothing about the effects of technological revolutions on the labor market.
Don't listen to him, Sam, Yoshua, Geoff, or me on this topic.
Listen to economists who have spent their career studying this, like @Ph_Aghion , @erikbryn , @DAcemogluMIT , @amcafee , @davidautor
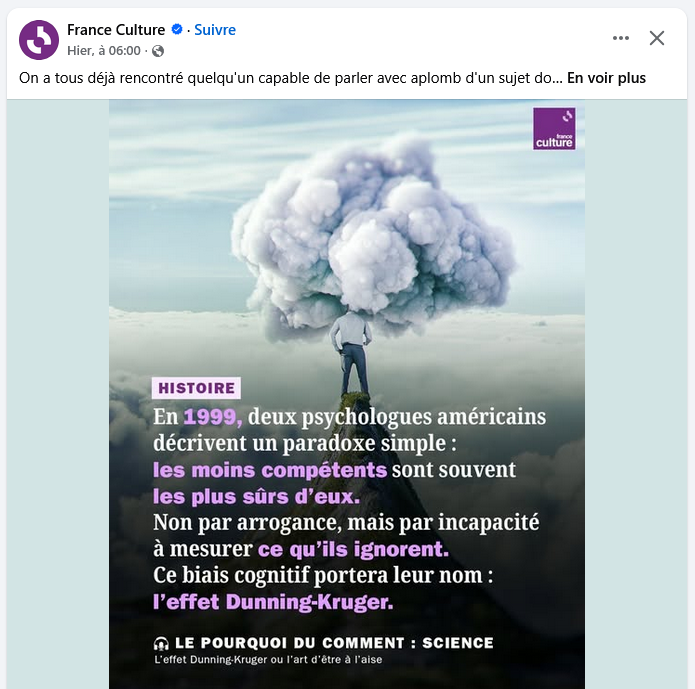
On appelle "effet Dunning-Kruger au carré" le fait de penser savoir ce qu'est l'effet Dunning-Kruger, en faire une émission de radio... et de se tromper à son sujet
En réalité, les compétents sont plus sûrs d'eux - c'est seulement la *différence assurance-compétence* qui diminue
PewDiePie didn’t “train his own LLM.” He fine-tuned an existing open-source model on coding benchmarks. His model started at 8%, crawled to 16% after format fixes, and one run hit 19.6% that briefly passed GPT-4o on a single benchmark before he couldn’t consistently reproduce it.
The tweet makes it sound like a YouTuber casually built a frontier lab in his bedroom. What actually happened is more interesting: a guy with a $41,000 home rig of 10 GPUs and 424GB of VRAM spent months failing, retraining, and iterating on dataset quality until he squeezed marginal gains out of a fine-tune.
This is the part worth paying attention to. The entire arc from October 2025 to now tells you where AI tooling has actually landed. PewDiePie went from building his first PC to running Qwen 235B locally, vibe-coding a custom chat UI, orchestrating multi-agent voting systems, and now fine-tuning models on custom datasets. He did most of this through AI-assisted coding itself.
The video is literally called “I wish I never did this project.” He’s documenting how painful and tedious the process was. That honesty is the signal. The hype accounts strip that away and replace it with “what the f*ck, YouTuber beats DeepSeek.”
The real takeaway: fine-tuning on specific benchmarks with curated data can let anyone temporarily spike a score past models that cost hundreds of millions to train. That tells you everything about how narrow benchmark gaming has become, and nothing about general capability. PewDiePie knows this. The people quote-tweeting him with shock emojis do not.