ACE Music v1 just hit #1 on @ArtificialAnlys' music leaderboard. It's the first model on this chart to outrank Suno's latest release.
Try it free at https://t.co/tPBsxSpUXU.
We'll open-source the model weights in the next few weeks. We're making the final tweaks so you can run it locally.
2,000,000,000 PCs sit on people's desks today.
The next billion computers?
They’ll be autonomous computers, driven by agents.
Introducing box by @Simular: one computer for ChatGPT, Claude, Codex, Gemini, DeepSeek and all your other agents.
With box, agents open apps, run the terminal, fill in forms, and stay signed in for whatever tasks come next.
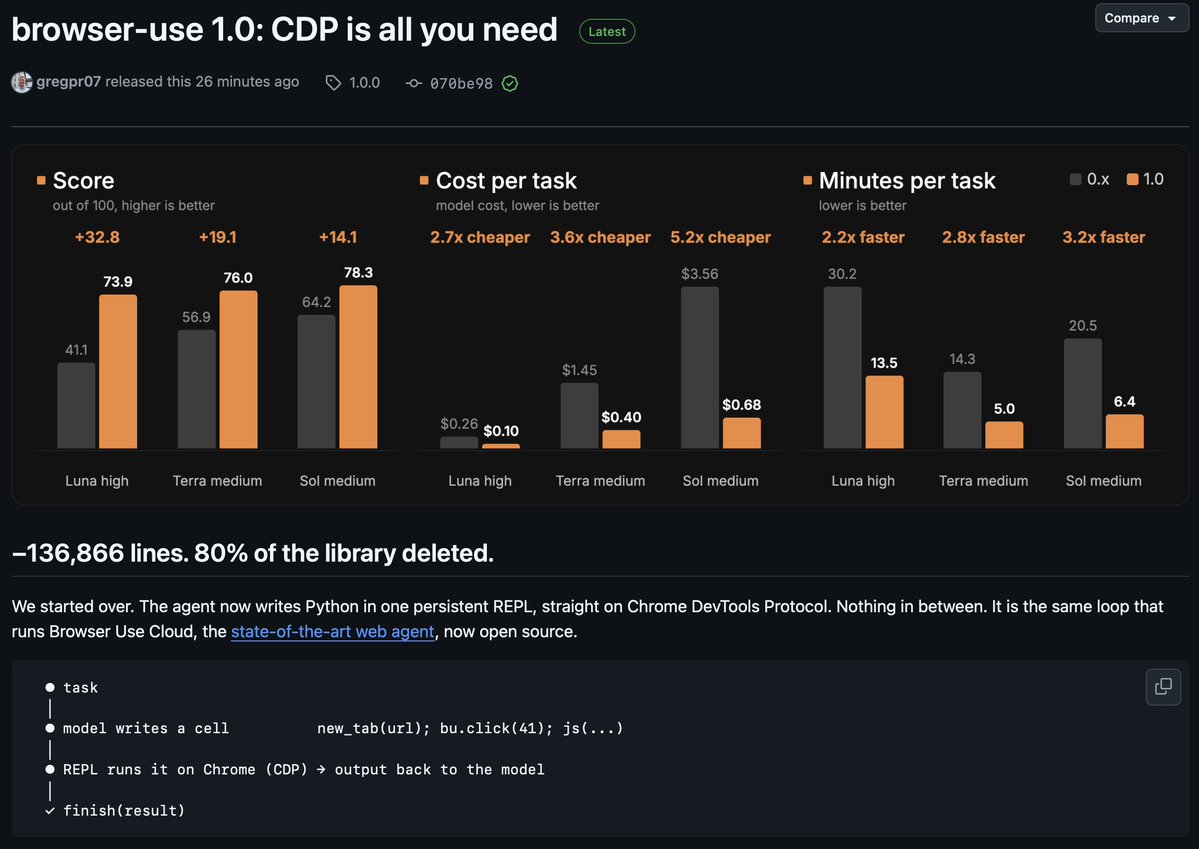
Introducing: Browser Use 1.0.0: CDP is all you need 👀
We deleted 90% of the old library. Predefined state and action space make it worse.
Now the agent just writes Python REPL on raw CDP. Simplicity wins.
> same models, up to 50% better
> 2-5x cheaper
> 2-3x faster
> SOTA web agent
From now on we ship fast. Please pin with ==
Introducing Soniox STT v6, the world’s first speech recognition model that knows what your voice agent is saying and automatically filters out the agent’s own voice.
Two connected innovations make this possible:
→ Agent text input gives recognition context from both sides of the conversation, improving its understanding of user responses.
→ Agent voice echo cancellation filters out the agent’s playback while continuing to listen to the user, even when they interrupt.
The result: fewer false interruptions, fewer clarification loops, and more reliable conversations.
V6 also delivers significantly higher accuracy across 60+ languages for voice typing, meeting transcription, multilingual recognition, and real-time translation, with stronger speaker diarization, language identification, endpoint detection, and context customization.
One unified speech model. All 60+ languages. The full feature set, with languages freely mixed.
Available now for real-time streaming and asynchronous transcription.
Explore what’s new in Soniox STT v6:
https://t.co/q6k9NZmz8l
Here’s what’s new with Genie 4:
🔵 Photorealism: Built on Gemini Omni for lifelike detail across spaces and subjects
🔵 Advanced physics: Aerodynamics, collisions, and people who move naturally
🔵 Real-time controls: Prompt to change the scene, add elements, or interact with characters
🔵 Native audio: Ambient sound, music, background noise, and interactive dialogue
🔵 Gemini reasoning: Plans multi-step events to maintain coherence as scenes evolve
These capabilities are a step toward developing safe virtual environments to see how agents and robots navigate their surroundings.
We’re exploring early use cases with trusted testers first, before bringing the model to Google AI Ultra subscribers in Project Genie and early access partners in our API and @GoogleAIStudio soon.
Find out more → https://t.co/vWUFo3QpnC