Cut down your experimenting time and have more fun testing and optimizing your local box w/ LLama.cpp Server and Hermes Desktop!
@ggerganov@Teknium@NousResearch
https://t.co/8FhWevx3dr
If you're like me an are constantly trying to test and optimize your local box then you'll enjoy my llama-server Manager plugin for @NousResearch#Hermes Desktop.
This is tailored to my workflow but it can be refactored to suit your needs easily.
🪄 Here's what it does ✨
👇
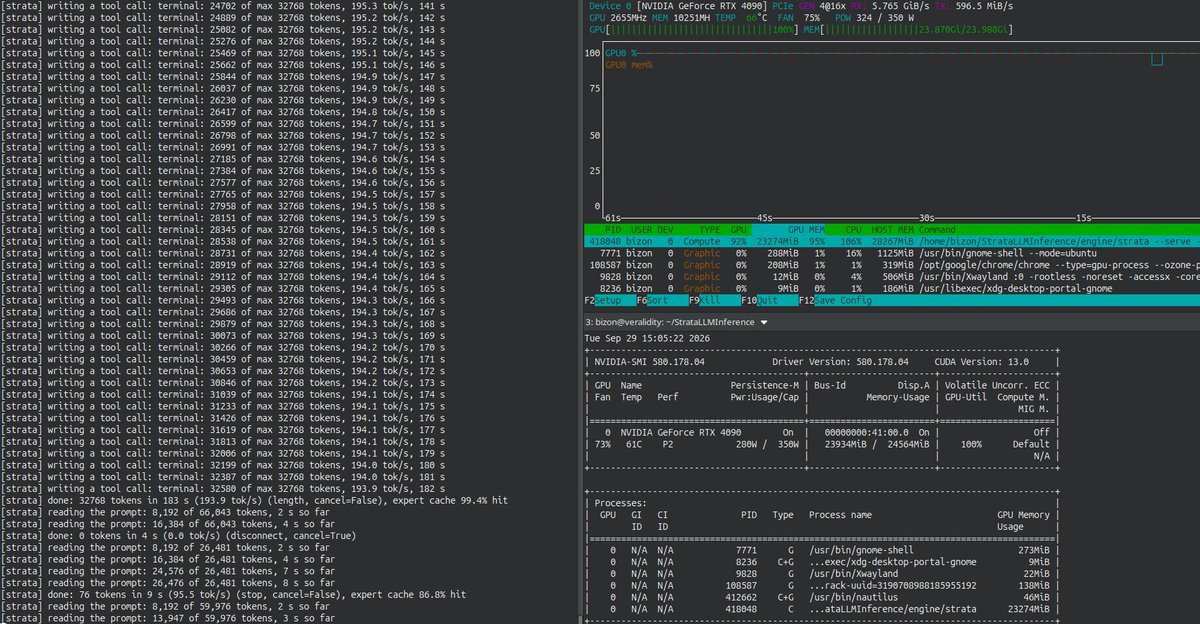
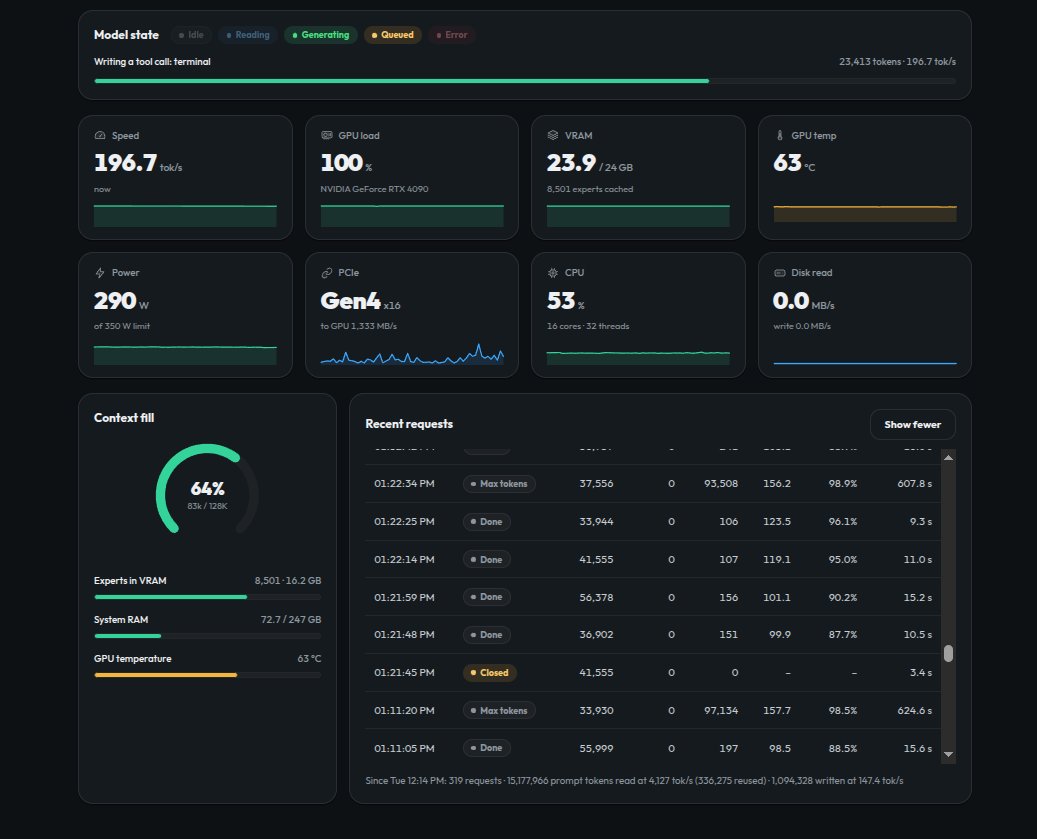
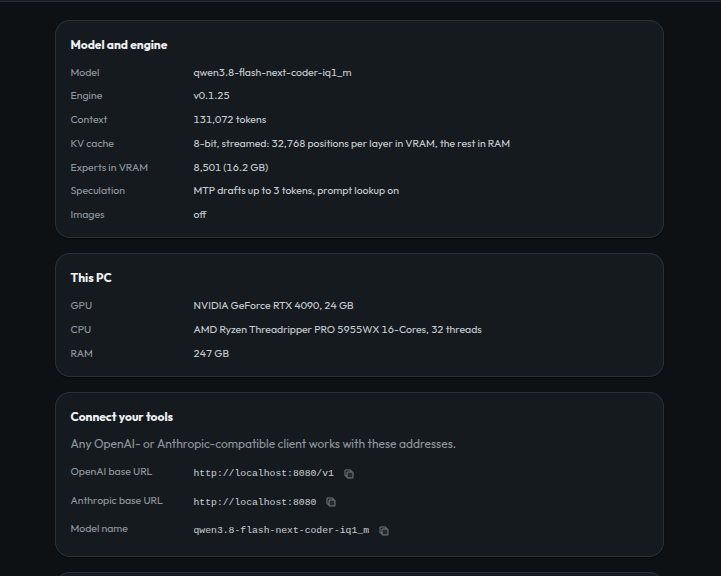
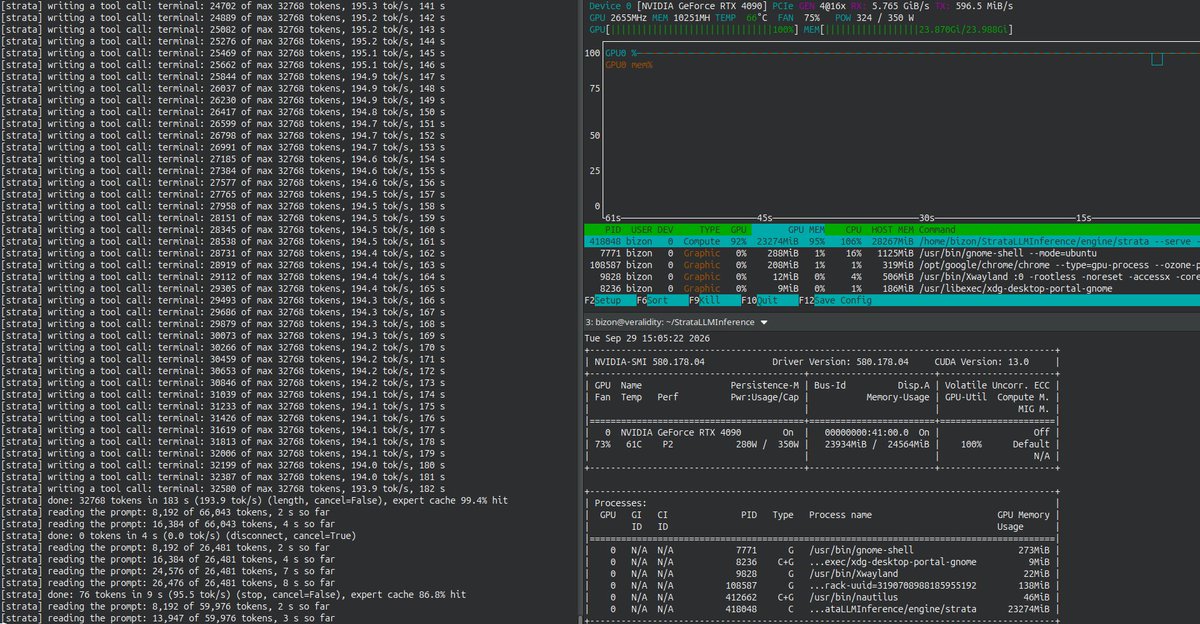
Damn this is awesome! I just hit 196 tok/s sustained on my RTX 4090 with Qwen3.8 Flash Next Coder, using a real-world coding task in my @NousResearch Hermes Agent Desktop
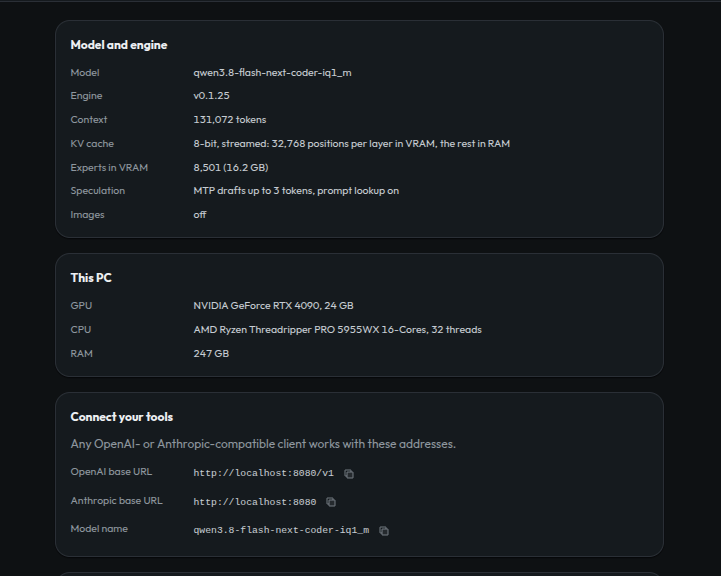
* 23.9GB VRAM packed with 8501 experts, KV Cache Q8, Threadripper 5955WX + 247GB RAM
Damn this is awesome! I just hit 196 tok/s sustained on my RTX 4090 with Qwen3.8 Flash Next Coder, using a real-world coding task in my @NousResearch Hermes Agent Desktop
* 23.9GB VRAM packed with 8501 experts, KV Cache Q8, Threadripper 5955WX + 247GB RAM
@HermesAgentTips Looks good! That will definitely come in handy!
I created something similar but for managing my local models and serving them with llama.cpp server. I might package it up and release it if there's enough interest.
If you're like me an are constantly trying to test and optimize your local box then you'll enjoy my llama-server Manager plugin for @NousResearch#Hermes Desktop.
This is tailored to my workflow but it can be refactored to suit your needs easily.
🪄 Here's what it does ✨
👇
If you're like me an are constantly trying to test and optimize your local box then you'll enjoy my llama-server Manager plugin for @NousResearch#Hermes Desktop.
This is tailored to my workflow but it can be refactored to suit your needs easily.
🪄 Here's what it does ✨
👇
We’re a digital commerce shop, but after hours our Founder & CTO is still pushing boundaries and building the tooling he actually uses.
Want to see the raw code, local AI setups, fine-tuning trials, and errors? Follow @boxweights 🔥
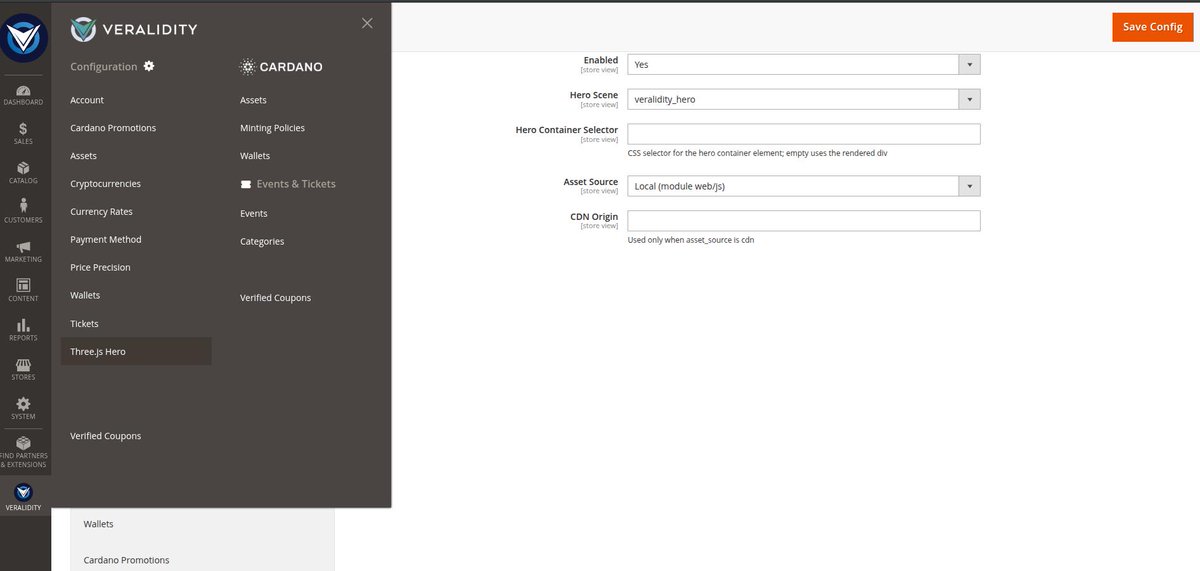
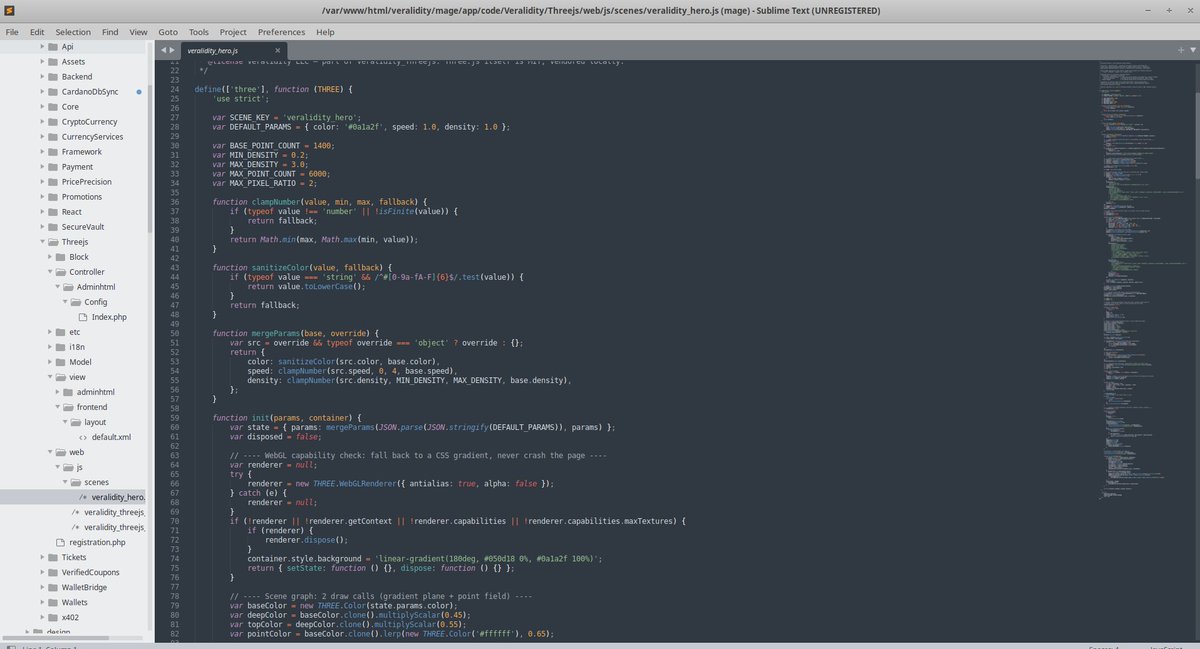
@ItsmeAjayKV I tested Qwen 3.8 Flash Coder and it was way faster than I thought.. Strata said it was the slowest model but it did not disappoint! I had it create an Adobe Commerce/Magento 2 ext that integrates @threejs as a widget for design elements in Hermes Desktop
https://t.co/uztTxXS5TP
Damn this is awesome! I just hit 196 tok/s sustained on my RTX 4090 with Qwen3.8 Flash Next Coder, using a real-world coding task in my @NousResearch Hermes Agent Desktop
* 23.9GB VRAM packed with 8501 experts, KV Cache Q8, Threadripper 5955WX + 247GB RAM
@HermesAgentTips Orchestration capabilities, fine-tuning which skills each profile loads, fallback models, etc. One feature that saves me a lot of time is one that I developed that I'm in the process of releasing is a #Hermes Desktop Plugin to manage your Llama.cpp Server
https://t.co/8FhWevx3dr
If you're like me an are constantly trying to test and optimize your local box then you'll enjoy my llama-server Manager plugin for @NousResearch#Hermes Desktop.
This is tailored to my workflow but it can be refactored to suit your needs easily.
🪄 Here's what it does ✨
👇
If you're like me an are constantly trying to test and optimize your local box then you'll enjoy my llama-server Manager plugin for @NousResearch#Hermes Desktop.
This is tailored to my workflow but it can be refactored to suit your needs easily.
🪄 Here's what it does ✨
👇
If you're like me an are constantly trying to test and optimize your local box then you'll enjoy my llama-server Manager plugin for @NousResearch#Hermes Desktop.
This is tailored to my workflow but it can be refactored to suit your needs easily.
🪄 Here's what it does ✨
👇
If you're like me an are constantly trying to test and optimize your local box then you'll enjoy my llama-server Manager plugin for @NousResearch#Hermes Desktop.
This is tailored to my workflow but it can be refactored to suit your needs easily.
🪄 Here's what it does ✨
👇
✅ Add, Edit, Delete Model Versions
✅ Star a Default Version for each Model
✅ Star a Default Model Version as your Main Model used
✅ Automatically Switch Models when Re/Starting without having to refresh Providers/Models manually
✅ Built-in monitoring, GPU, CPU, RAM, TOKs
👇
Damn this is awesome! I just hit 196 tok/s sustained on my RTX 4090 with Qwen3.8 Flash Next Coder, using a real-world coding task in my @NousResearch Hermes Agent Desktop
* 23.9GB VRAM packed with 8501 experts, KV Cache Q8, Threadripper 5955WX + 247GB RAM
@coldniko Damn this is awesome! I just hit 196 tok/s sustained on my RTX 4090 with Qwen3.8 Flash Next Coder IQ1_M using a real-world coding task in my @NousResearch Hermes Agent Desktop
* 23.9GB VRAM packed with 8501 experts, Threadripper 5955WX + 247GB RAM
Local inference is on fire!