Congrats @thinkymachines team on Inkling 2 Small!
A 594B model pretrained in just 68 hours with NVIDIA NVFP4 on GB300 NVL72 racks.
Read how the team made low-precision training work at this scale. 👇
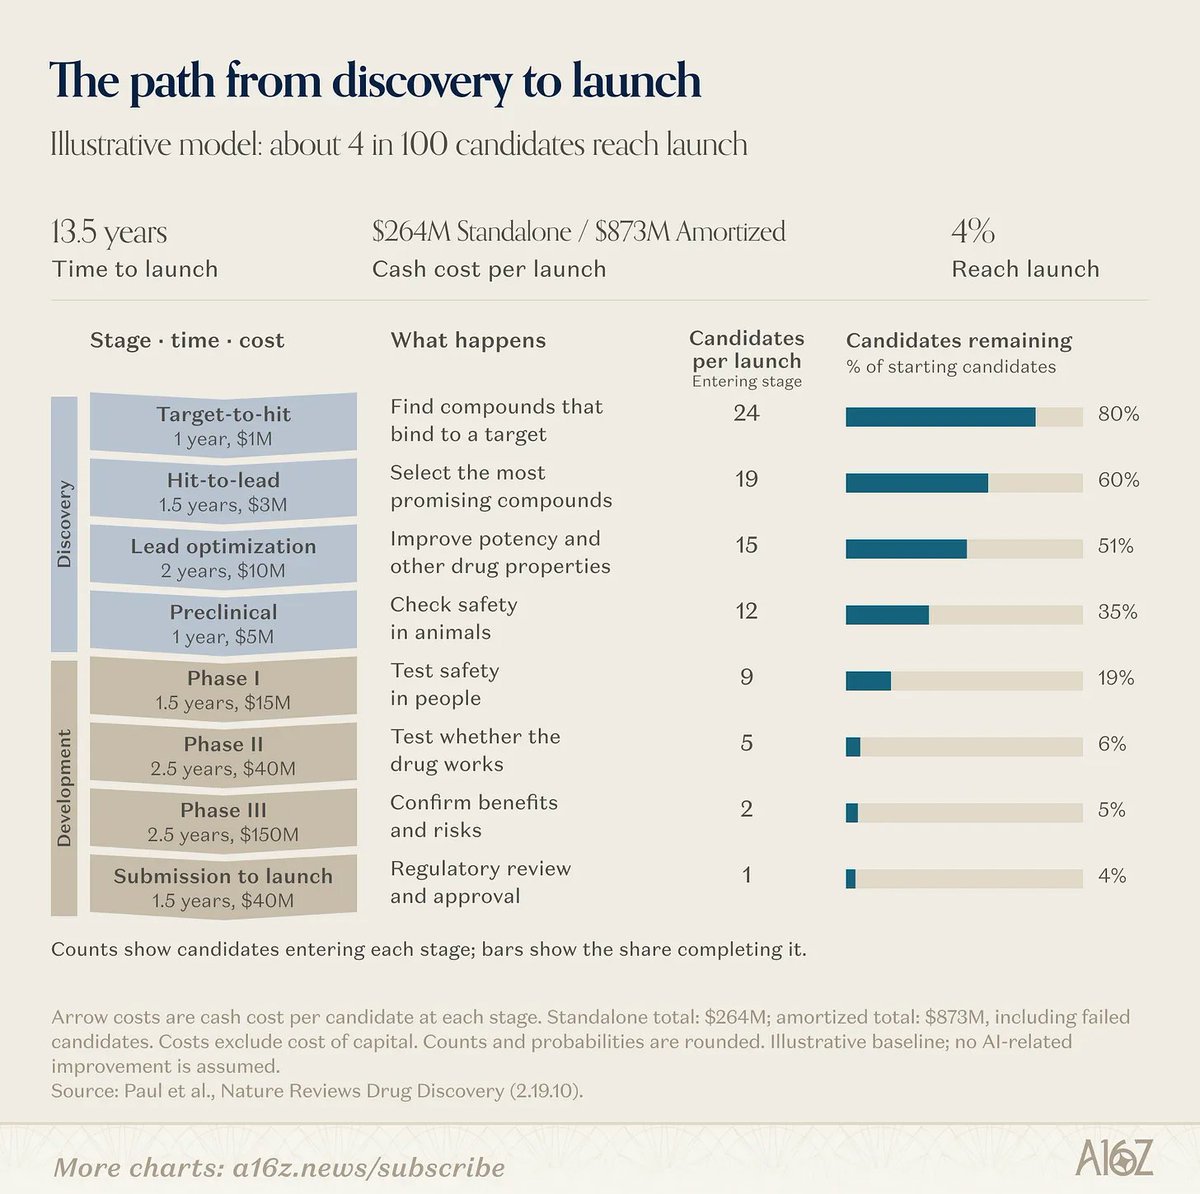
Developing a drug takes years, and most candidates never reach patients.
Amortizing the cost of failed drugs across stages, the present value cost of developing a drug is close to $2B. The process takes 13 years on average, with rising clinical trial costs putting further pressure on R&D productivity.
AI could improve those economics by increasing the probability of success and reducing development time, from identifying promising molecules to designing clinical trials and improving patient recruitment.
That may enable companies to pursue therapeutic targets and indications that might otherwise have been uneconomical.
Full piece on why AI will make pharma even bigger: https://t.co/A96FDSSk57
Thinking Machines Lab kept its promise and open-sourced Inkling 2 Small, a 594B-parameter model trained with 4-bit forward passes.
> now available for download on HuggingFace under an Apache 2.0 licens
> Training in 4-bit cut pretraining time 8% and RL time 20%, for about 2% efficiency loss.
> Running it takes at least 500GB of GPU memory in NVFP4 and at least 800GB in MXFP8, and MXFP8 gains “a very marginal 1–2 percentage points” over NVFP4 on evals.
> Because training kept the same numerics from pretraining through the final RL rollout, the released 4-bit checkpoint needed no separate calibration step.
> The lab first tried NVFP4 in both forward and backward passes, but that hurt compute efficiency too much, so only the forward pass stays in 4-bit.
@SanghamitraLIVE The hypocrisy is celebrating Durga Puja across India while opposing Biharis celebrating their festivals in Kolkata, yet welcoming Christmas and other celebrations.
@keyakahe True. The hypocrisy is celebrating Durga Puja across India while opposing Biharis celebrating their festivals in Kolkata, yet welcoming Christmas and other celebrations.
@SudhanidhiB@EasternRailway The hypocrisy is celebrating Durga Puja across India while opposing Biharis celebrating their festivals in Kolkata, yet welcoming Christmas and other celebrations.
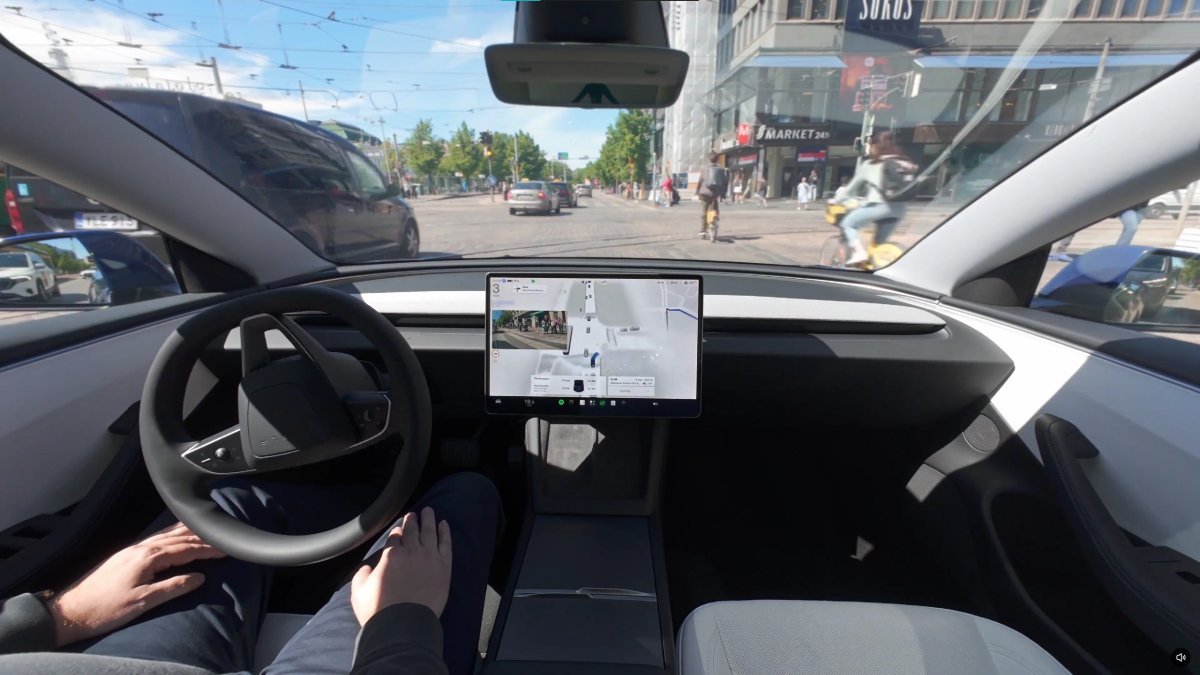
This is Tesla. Tesla has FSD. It drives me every day.
There are 50 Chinese EV companies. None of them have FSD or anything close.
This tells you everything you need to know about Chinese AI models. If Chinese AI capabilities were superior, they'd have developed their own FSD yrs ago.
Not a single Chinese company, from Xiaomi to BYD, has self-driving tech that's even half as good as Tesla.
Why is that ?
OCR models keep getting cheaper!
I wanted to see how much, and where the savings come from. An agent helped me run 8 open OCR models from the last 18 months on the same 850 pages, on one GPU on @huggingface Jobs.
- $0.51 to $0.095 per 1,000 pages. A straight line through the eight halves about every 10 months, but most of the drop is one new model: LightOnOCR-3-0.8B from @LightOnIO.
- How you run a model changes the cost too. GLM-OCR on 250 dense pages: $1.57 per 1,000 run the way I ran it in February, $0.40 today (many pages in flight, pages fitted to 2,048 px, newer @vllm_project, bigger GPU).
- Full-size scans did not help. For three models, they cost 1.3 to 4.2x more than 2,048 px, with no accuracy gain on book pages.
- On 282 checked book pages, every model gets its median page over 99% right. Two of the cheaper ones make about 1.5x the errors of the oldest.
- On dense two-column 1771 print, the oldest model was preferred over most of the newer ones. The newest about ties with it.
So still worth testing a few models on your own pages. Comparing all eight on 850 pages cost about $6 of GPU time.
Writing a full post on this!
By the time Fable 6 comes along, perhaps Anthropic will simply prompt it to build all of SaaS automatically and bundle it in one Claude subscription. They will be the new Microsoft.
Startups being created and run by AGIs is going to be the default going forward.
Self-hosted Claude Managed Agents is now in private beta.
You can host the agent harness, sandboxes, and session history, in your own cloud or on-premises, and choose where requests to Claude are sent.
If that Spy’s goal was to destabilize one of the most successful American companies, they achieved their goal. Ousting Jensen feels rushed and not right.
Do you know how many people are waiting in line for a doctor?
Do you know how long they have been there?
Do you know if anybody fell or is in need of assistance?
Inspired by the cafe project I created one for hospital waiting rooms. About twice a second @liquidai d1-2B looks at a camera frame and returns a box for every person in it.
It then answers three questions about each person in one batched pass: is this really a person, are they a patient or staff, and are they sitting, standing or lying down?
We can also detect if a person fell or is in need of assistance
It runs entirely on a laptop.