🚀 Introducing OpenVLHarness:
Turn any LLM into an evidence-based reasoner that thinks and codes in visual space.
📈 GPT-6 Astra gains +9.9 points on average over 22 datasets.
⚡ Beats Codex and other VL harnesses by 7.7–8.5 points, at ≤37% of their cost.
🧵 More details ↓
Apple and UCLA present OpenVLHarness
A training-free harness that gives multimodal LLMs a capability layer and persistent multimodal memory, boosting average scores by 9.7-12.6 points across 22 benchmarks.
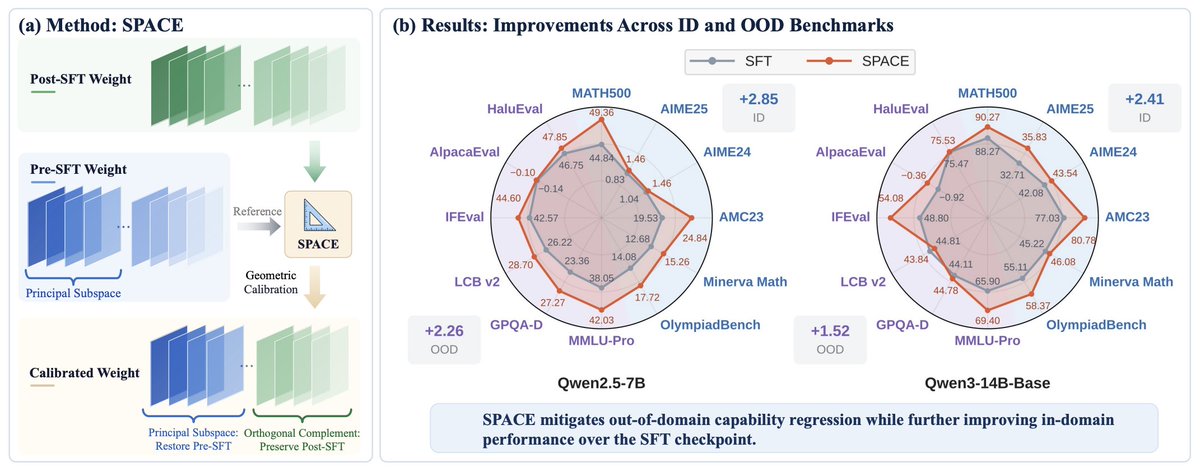
Fine-tuning can improve a target skill while weakening others. Can we improve a fine-tuned LLM by undoing part of its fine-tuning?
Introducing 🚀SPACE🚀: a post-hoc method that improves average performance both within and beyond the training domain.
No extra training. No data. Just the pre- and post-SFT checkpoints for calibration with one single step of code.
1/n
🚀 Introducing OpenVLHarness:
Turn any LLM into an evidence-based reasoner that thinks and codes in visual space.
📈 GPT-6 Astra gains +9.9 points on average over 22 datasets.
⚡ Beats Codex and other VL harnesses by 7.7–8.5 points, at ≤37% of their cost.
🧵 More details ↓
🚀 Want to try OpenVLHarness yourself?
We've released an interactive demo where you can bring your own MLLM and explore its tool-use trajectories.
📄 Paper: https://t.co/zYimlfKa0T
💻 Code: https://t.co/HPVuiMMiHX
🎬 Demo: https://t.co/VRgRJLc2T5
Huge thanks to @rohanpaul_ai for sharing our work!
We’re excited to share LEAP: a new agentic framework for formal theorem proving!
LEAP mimics a human mathematician's workflow by constructing proof graph via informal blueprints, then searching and backtracking using compiler feedback.
The results?
🏆 Solves 12/12 Putnam 2025 problems 📈 Raises Gemini-3.1-pro's performance from 10% to 70%
Read the paper: https://t.co/d5t0nAQNs5
I integrated our recent work, Spectral Progressive Diffusion a.k.a. SPEED (https://t.co/PrOvMOv9vt), with the open-source @ideogram_ai model released yesterday. Turns out our method works out of the box and speeds up inference by up to 1.6× while preserving the high image quality!
[1/4]
🌟 Excited to share Ctrl-R, accepted as an ICML 2026 Spotlight!
Specify a target reasoning structure, Ctrl-R can enforce it during rollout, and retain accurate importance-sampling weights for principled policy optimization.
paper: https://t.co/3OEldcjJld
🧵[1/5]
Excited to share what I worked on this summer!
PE-AV — a new multimodal encoder trained on ~100M audio–video-text pairs!
✔️ Unified Audio–Video–Text embeddings
✔️ SOTA across audio, video & AV benchmarks
📄 Paper: https://t.co/CkpEmxDAYO
💻 code: https://t.co/Jc6a7nQHl4
We’re open-sourcing Perception Encoder Audiovisual (PE-AV), the technical engine that helps drive SAM Audio’s state-of-the-art audio separation.
Built on our Perception Encoder model from earlier this year, PE-AV integrates audio with visual perception, achieving state-of-the-art results across a wide range of audio and video benchmarks. Its native multimodal support can assist people in everyday tasks, including sound detection and richer audio-visual scene understanding.
🔗 Read the paper: https://t.co/RLWJOgG2uz
🔗 Download the code: https://t.co/1L5ZqCZlxq
We released SAM Audio 🎧 and PE-AV (Perception Encoder AudioVisual) 👀👂.
PE-AV representation powers SAM Audio’s data ⚙️ and SAM Audio Judge 🧑⚖️.
📄Paper: https://t.co/hIATjcgPQX
💻 code: https://t.co/XtfnnPZAtF
🔗 SAM Audio: https://t.co/O8gUte4iX4
But it doesn’t stop there ⤵️
Very excited to share what I've been working on over the past few months!
Try out the zero-shot SAM3 Agent with your own choice of images, complex language prompts and MLLM backbone: https://t.co/nffKHdEQ1r
Here is one of my favorite examples:
Prompt: "The cows behind the car"
I'll be presenting our paper: Verbalized Representation Learning (VRL) on Tuesday 11-2 PM at #ICCV2025
Come see how models can automatically generalize compositionally to new knowledge — without labeled data or human effort!
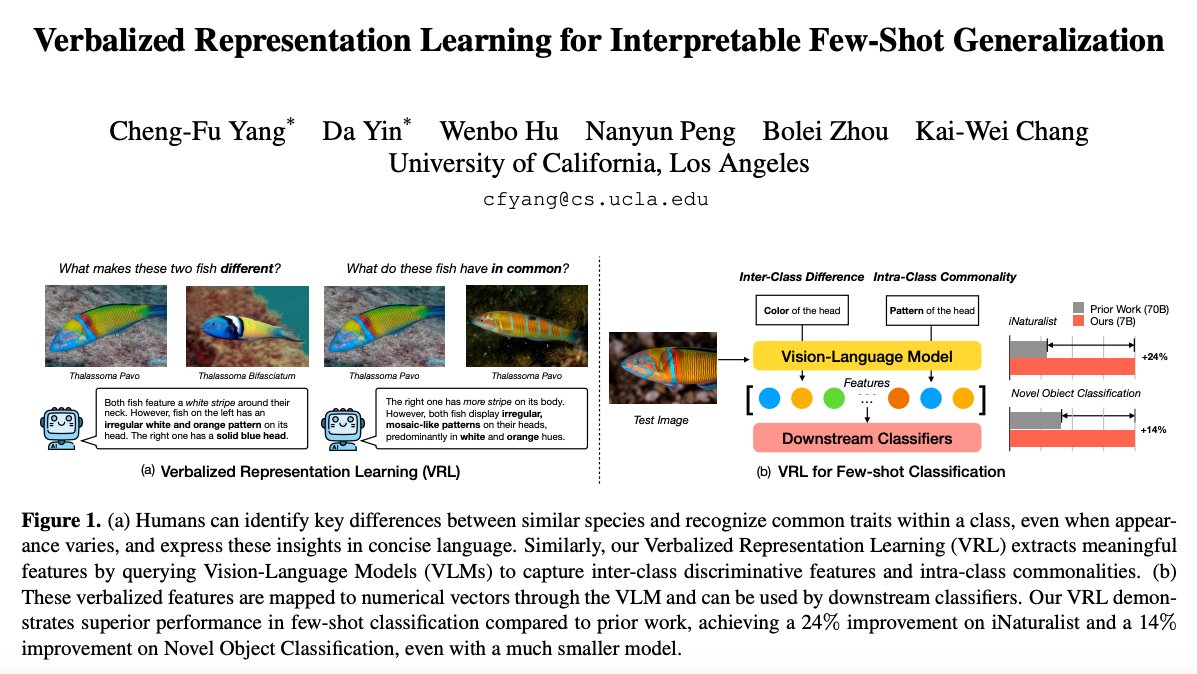
📣 New Paper: Verbalized Representation Learning (VRL)
VRL bridges prompt engineering and representation learning to enable automatic interpretable feature extraction — all without gradient descent!
🔥 +29% over SOTA
📊 95% less data
https://t.co/3LtGnWCxSk @uclanlp
(1/n)
📣 Our paper “Customize Multi-modal RAI Guardrails with Precedent-based Predictions” has been accepted to #COLM2025! 🎉
TL;DR:
- No hand-crafting detailed rubrics
- Model auto-discovers and evolves its own rubrics
- Plug and play - work with OSS and commercial model
(1/N)
📣 Our paper “Customize Multi-modal RAI Guardrails with Precedent-based Predictions” has been accepted to #COLM2025! 🎉
TL;DR:
- No hand-crafting detailed rubrics
- Model auto-discovers and evolves its own rubrics
- Plug and play - work with OSS and commercial model
(1/N)
Results show that our method
• Outperforms standard SFT and ICL across RAI categories
• Scales well as the number of data grow
• More robust to policy expansion
(4/N)