@DJSnM Not to mention that LLMs are trained on the internet which is full of crap, possibly even some random characters and such, and training still (incredibly) works.
@DJSnM Plus, I would add that practically all neural models nowadays are trained with stochastic gradient descent, where the gradient used for optimization has some intrinsic noise.
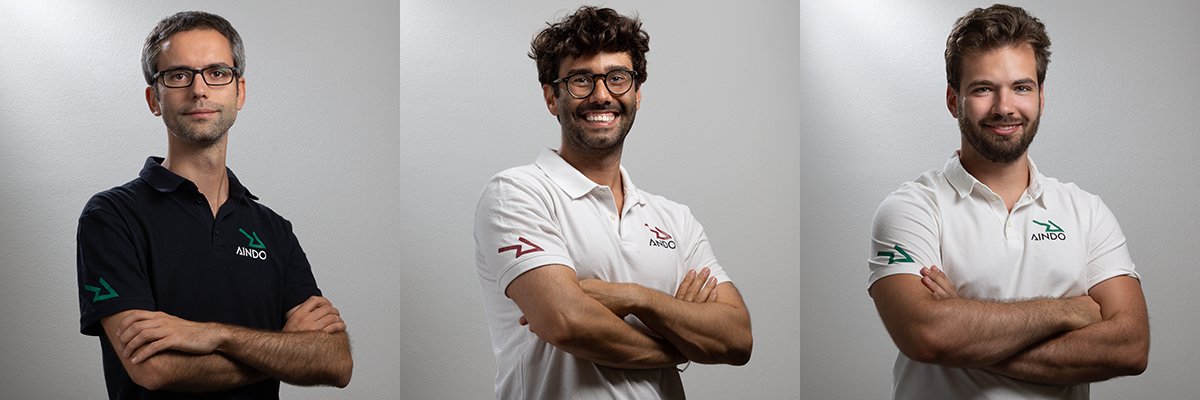
Congrats to Sebastiano Saccani, Daniele Panfilo and Borut Svara from @aindo_ai , the SISSA Startup based in @AreaSciencePark that has raised a €2.8M investment from Vertis SGR for its synthetic data technology https://t.co/6FJUEvOFEj
https://t.co/fOOwiP9r5q
They are loosely connected to what I’m working on these days but these three books are still very clearly the most enjoyable read I’ve had since I joined the field. What a pleasure it was to read them!
Want to know everything you can do with your tests in Python (repeating, randomizing, selecting, skipping, running only the tests for the files you locally changed and more)? @StasBekman just wrote a very comprehensive guide that we follow ourselves! https://t.co/UvaLozV6UU