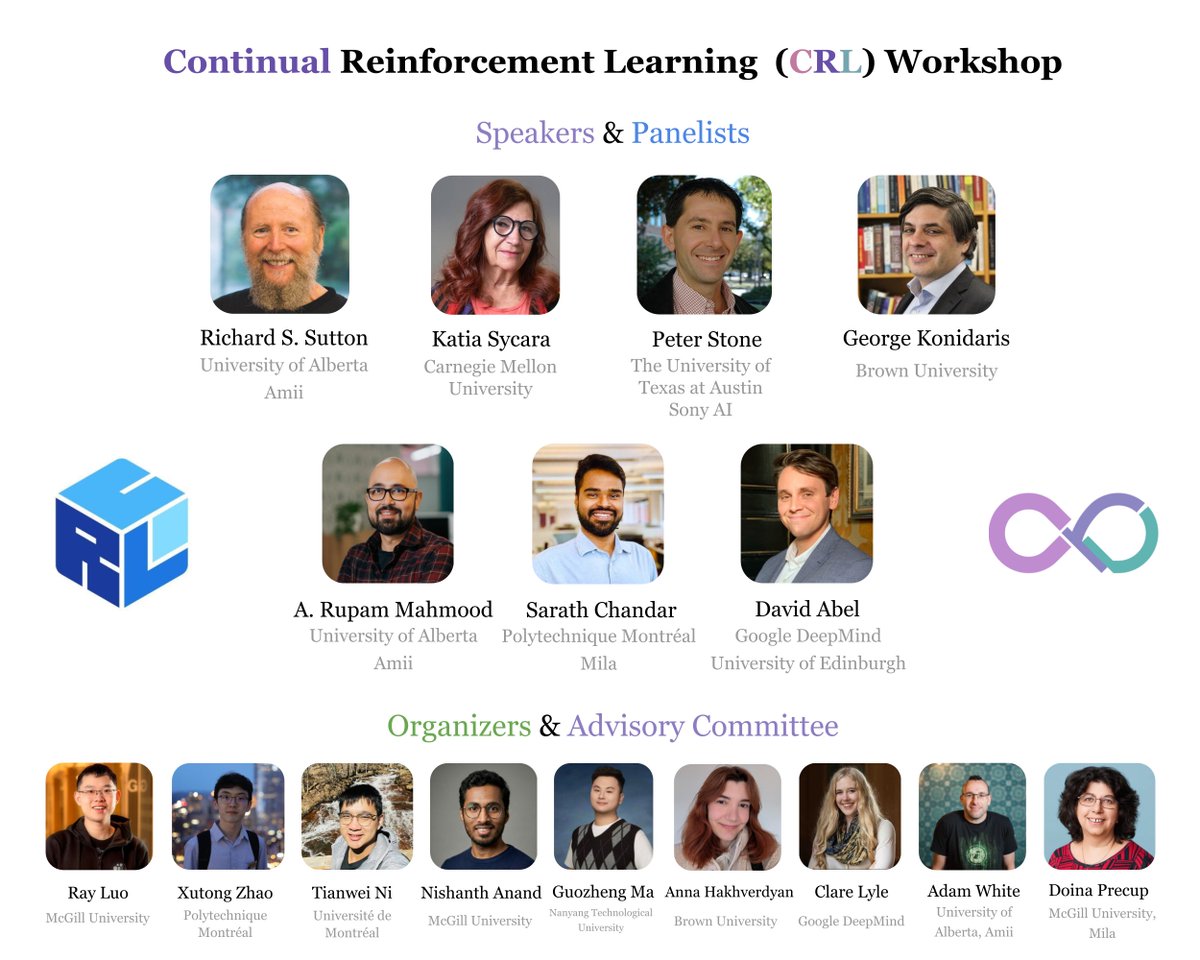
♾️ Continual RL Workshop comes to life tomorrow!
📍 B-2305, Université de Montréal
3200 Jean-Brillant, Montréal, Canada
🕘 9:00–17:30
Come learn. Continually, of course. ♾️
🔗 Program: https://t.co/bEdjswYTl4
🎥 Finally, we’ve collected all the recordings from the first edition of the Continual RL Workshop in a YouTube playlist and preserved some great memories from the event in our website gallery! 📸✨
▶️ Playlist: https://t.co/kLC52ImpN9
🖼️ Gallery: https://t.co/n9xqivV2un
🎥 Finally, we’ve collected all the recordings from the first edition of the Continual RL Workshop in a YouTube playlist and preserved some great memories from the event in our website gallery! 📸✨
▶️ Playlist: https://t.co/kLC52ImpN9
🖼️ Gallery: https://t.co/n9xqivV2un
Simple ideas often generalize best! Loss smoothing is one of those really simple ideas that works surprisingly well for adaptation under distribution shift. Really excited about this line of work!
The penultimate contributed talk in our workshop was given by Edan Meyer (@ejmejm1):
🎙️ Connectivity, Credit Assignment, and the Speed of Learning
🔗 https://t.co/xqtR2j5ITC
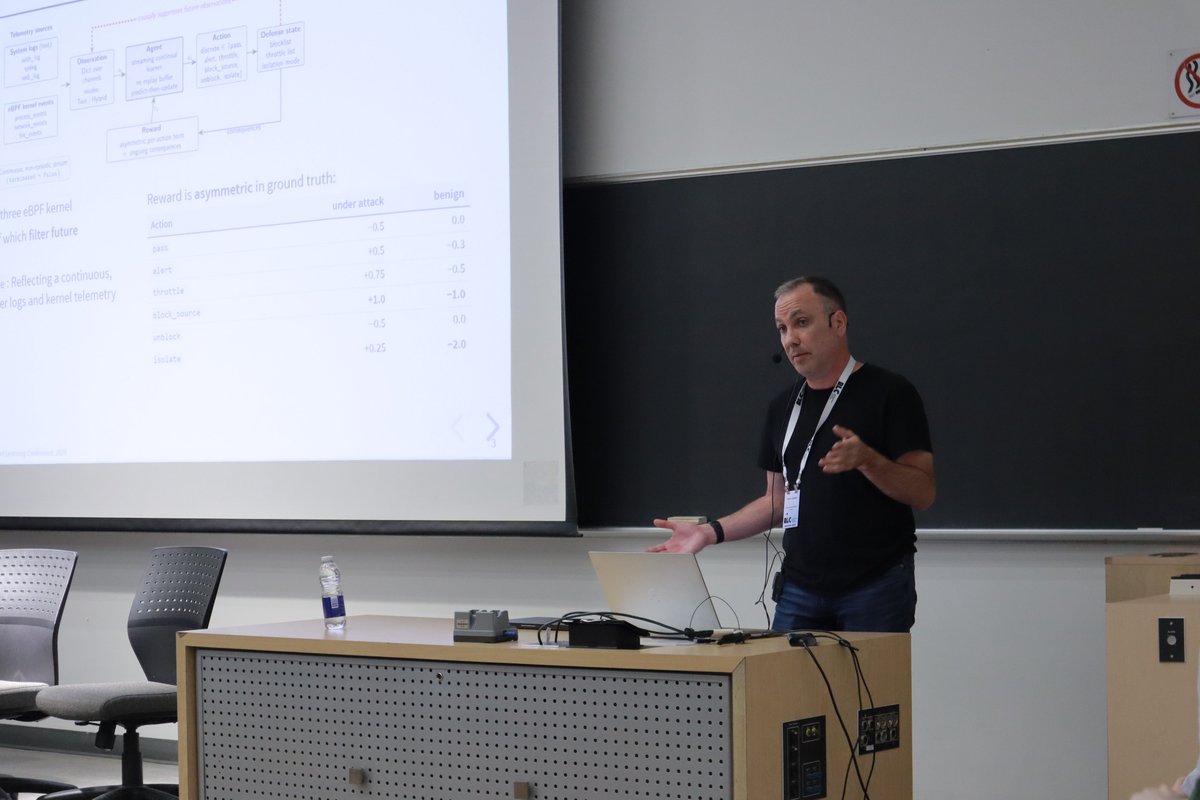
It was an honour to be invited to present our Security Gym environment at the @continual_learn workshop at the RLC conference. Have to admit it was a little intimidating to be sandwiched between @RichardSSutton and a panel of industry experts but it made for a packed room to hear my little talk.
Received some great feedback in the poster sessions that I can incorporate into the environment and paper. The reinforcement learning community is really great community that I'm looking forward to working with more.
The second oral talk of the afternoon session was given by Keith Lawson (@j_klawson):
🎙️ Security-Gym: Evaluating Temporally-Uniform Agents on High-Fidelity Linux Telemetry
🔗 https://t.co/4udqLdtfhJ
The second invited talk of the afternoon session was given by Peter Stone (@PeterStone_TX):
🎙️ Continual RL and Automatic Curriculum Learning
🎥 https://t.co/wf6hFgLdB5
Revisit our first invited talk of the afternoon session by David Abel (@dabelcs):
🎙️ Where is Learning?
🎥 https://t.co/owyQQxvxvC
✨ In this talk, David gave a simple general definition of an agent, and asked: where in such an agent does learning take place?
The third contributed talk in our workshop was given by Luc McCutcheon:
🎙️ Calibrated Partial Resets: Preventing Policy Collapse in Continual Reinforcement Learning
🔗 https://t.co/UZylxAZuK4
Our second contributed talk in our workshop was given by
@cogscikid@neilhshah15:
🎙️Task diversity produces systematic transfer but inhibits continual reinforcement learning
📷 https://t.co/PGdYosto1A
Katia Sycara gave our second invited talk:
🎙️ Long Horizon Reasoning via Neurosymbolic Learning
Due to technical issues, only the slides are available for this talk.
📄 Slides: https://t.co/IKQYFiSPih