Thrilled to share our new #NeurIPS2025 paper done at @GoogleDeepMind, Plasticity as the Mirror of Empowerment
We prove every agent faces a trade-off between its capacity to adapt (plasticity) and its capacity to steer (empowerment)
Paper: https://t.co/prWpkdPojb
🧵🧵🧵👇
🎤 Meet Brian Christian
@brianchristian, @CHAI_Berkeley, https://t.co/VgMylvUHEr
We’re pleased to introduce our second speaker for RLDM 2027!
Stay tuned for submission deadlines and further updates on our website: https://t.co/urqPPN8ZFH 👀
#RLDM2027
📣 Save the date!
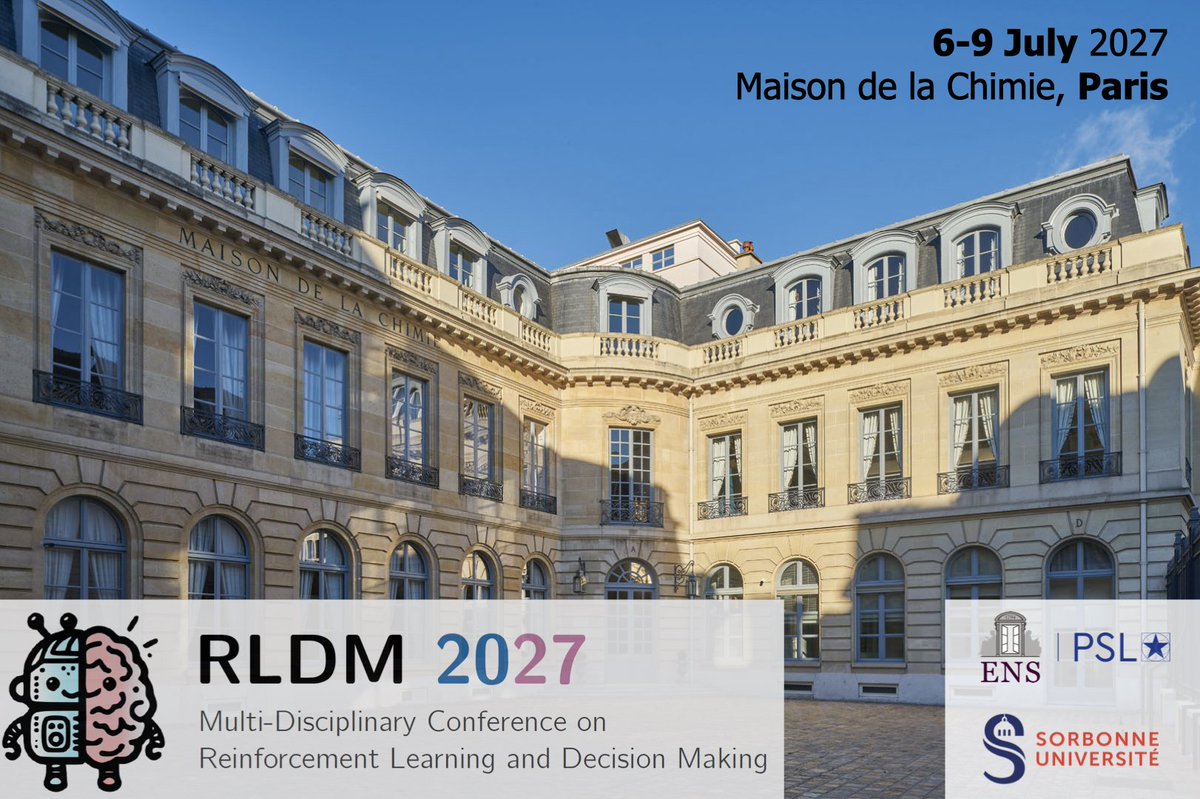
RLDM 2027, the Multi-disciplinary Conference on Reinforcement Learning and Decision Making, is coming to Paris, July 6-9, 2027 🎉
Stay tuned for submission deadlines and more updates on our website https://t.co/urqPPN8ZFH 👀
📣 Save the date!
RLDM 2027, the Multi-disciplinary Conference on Reinforcement Learning and Decision Making, is coming to Paris, July 6-9, 2027 🎉
Stay tuned for submission deadlines and more updates on our website https://t.co/urqPPN8ZFH 👀
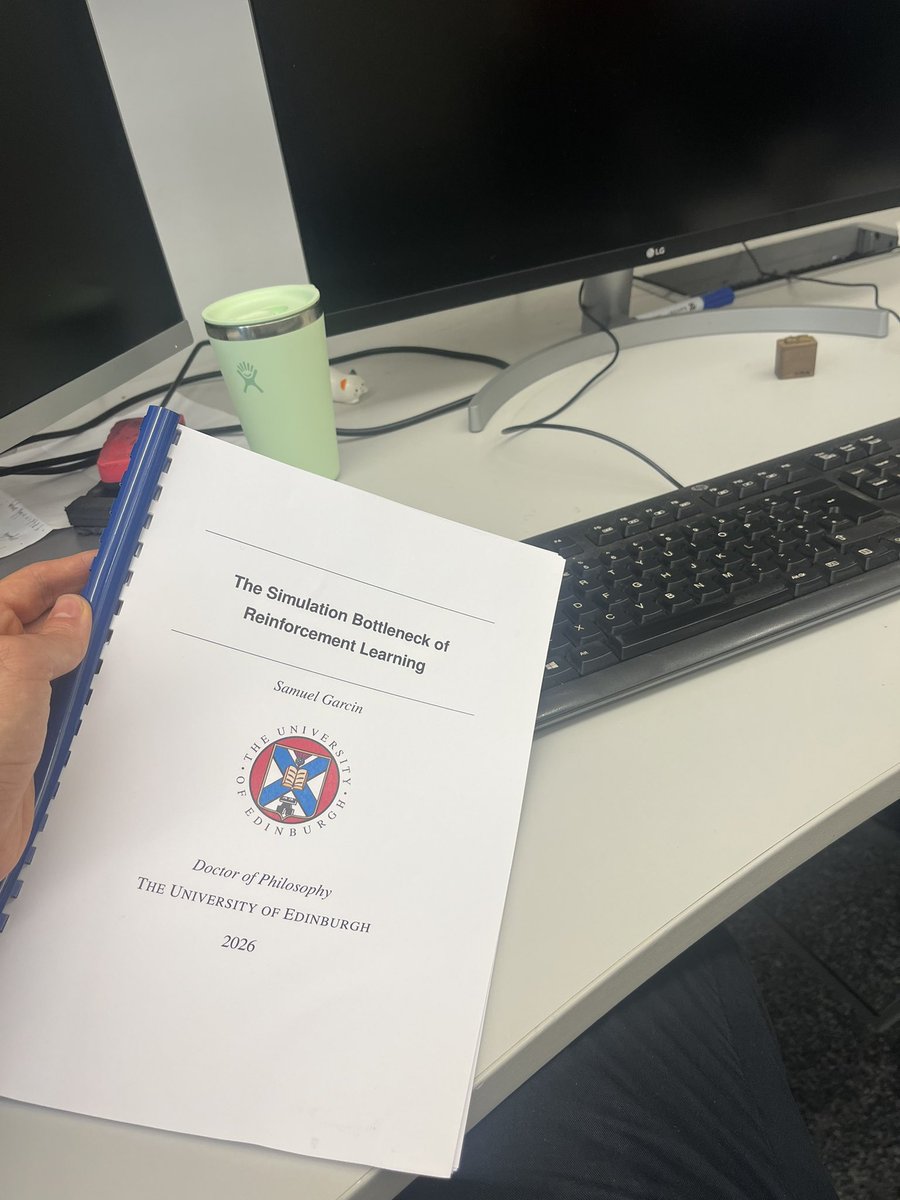
viva passed with minor corrections! Thanks to @MichaelD1729 and @ale_suglia for serving as my examiners and to my wonderful advisors @dabelcs and Chris Lucas for the incredible mentorship and support over these past years!
Attending #ICML and interested in World Models?
PERSIST models the world within an explicit 3D latent representation. Come by to discover the unique capabilities this unlocks!
📍 Poster 2715 • Thursday • 2:30pm
#ICML2026#WorldModels#GenerativeAI#3DGeneration
This week's #PaperILike is "General agents contain world models" (Richens et al., ICML 2025).
Brought to my attn by @dabelcs 's beautiful philosophy-laden talk at ICAPS. The explicit construction of a transition model from a policy is cool (Alg 1).
PDF: https://t.co/2D9fKQie6a
Model-free agents learn to maximise reward without modelling the environment. Right?
In recent work, we challenge this narrative by proving that agents, trained on a sufficiently rich set of goals, encode a unique and accurate world model in their value functions.
1/
We are starting a new, nonprofit alignment organization, ⊢ Sequent Research, bringing together researchers previously on UK AISI’s Alignment Team, Timaeus, and elsewhere to research how to align superintelligence. We are hiring! 🧵
Just published in @PNASNews, we resolve a 50-year-old riddle from Richard Feynman's handwritten notes, prove and generalize it, and run a large-scale human study to reveal near-optimal heuristics in sequential decision problems:
https://t.co/4AOM1iDqG2
"Imperfect World Models are Exploitable"
World models can look accurate, but still rank policies incorrectly, saying policy A is better than policy B when the real environment says the reverse.
This paper formalizes that failure as model exploitation and proves it is basically unavoidable for any nontrivial, nonequivalent world model on broad policy sets.
It also connects this to reward hacking and derives a safe horizon showing how model error compounds with planning depth.
Reminder that the deadline for the Finding the Frame workshop @RL_Conference is coming up on May 22 AoE ⏰
We're excited to read your submissions reflecting on the philosophy, practice, and formalisms of reinforcement learning!
🔗 More details: https://t.co/mNy0SGK1H2
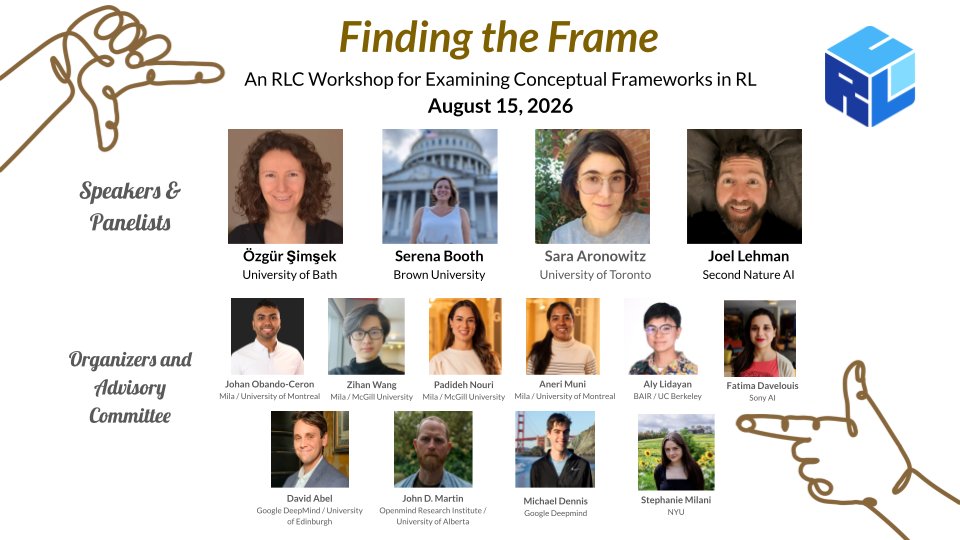
Finding the Frame will be back at @RL_Conference 2026 with a fantastic speaker lineup! We welcome submissions that reflect on the philosophy, practice, and formalisms of reinforcement learning.
📅Submission deadline: May 22, 2026 (AoE)
More details: https://t.co/bYbIW3QKB7
Standard RL assumes a stable world. The real world may not.
♾ Introducing the Continual RL Workshop @RL_Conference 2026, Montreal, Canada.
🤖 Agents should never stop learning!
🖼️ Site: https://t.co/ZYpBUPbRqR
📄 Submit: https://t.co/Lf5Yj55pDe
Really excited to present our recent work at #ICLR2026 this week!
We discover highly coordinated joint behaviours and integrate them into the skill sets of MARL agents, accelerating the search for effective joint strategies in downstream tasks.🧵
Paper: https://t.co/AZYQQOlHFq