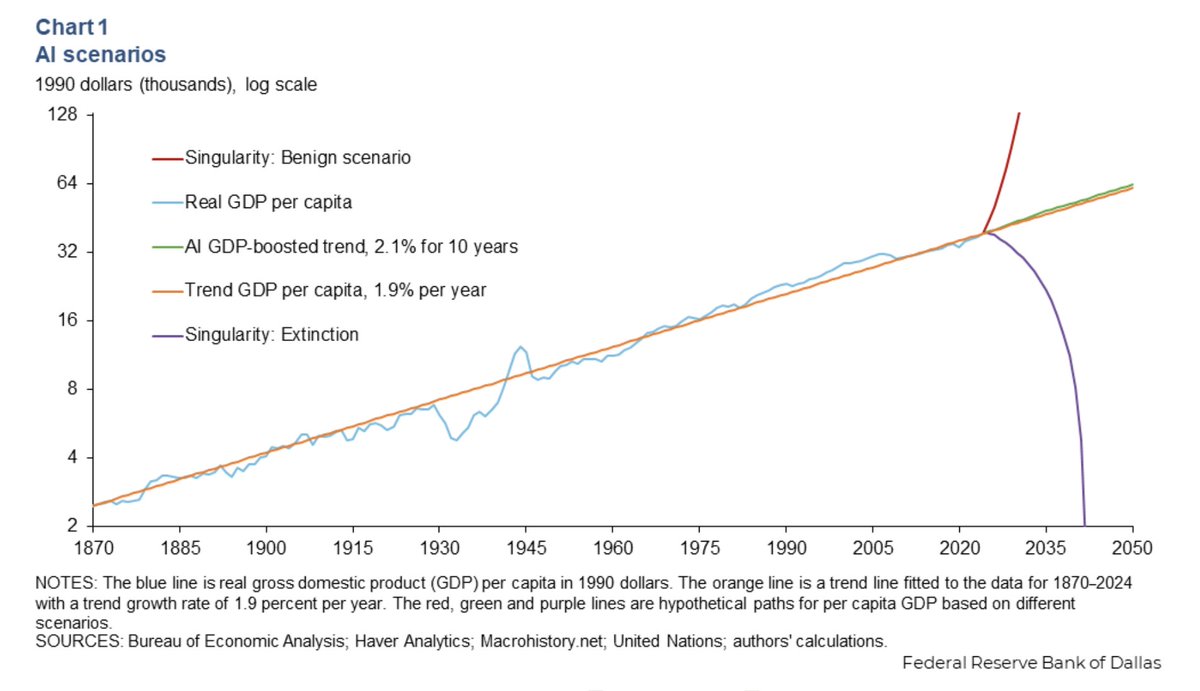
Properly reckoning with Plan A is indispensable for anyone seriously thinking about the future of AI
No better way to do so than listen to my co-host Luisa break it down with @DKokotajlo
https://t.co/BhYCWzRSEs
In AI 2027, we predicted that AI would take over the world or irreversibly concentrate power.
In AI 2040: Plan A, we've laid out our positive vision for what should happen instead.
Did not expect the man running AGI safety at Google DeepMind to be this relaxed about AI killing everyone. Rohin Shah's best guess is catastrophic misalignment probably just doesn't happen.
My best interview in some time.
Rohin Shah leads AGI alignment/safety at DeepMind.
And he has a lot of spicy personal takes:
We probably won’t get catastrophic misalignment (00:49)
Safety 'commitments' have severe limitations (10:38)
The intelligence explosion probably isn't imminent (1:52:44)
Why he's not working to pause AI advances (51:44)
Pre-deployment evals aren't the right focus (for catastrophic risks) (37:41)
Signalling concern for safety sometimes diverts resources from actually making AI safe (01:09:51)
Reading AI thoughts is v useful for safety – and we'll probably be able to for years to come (54:17)
Governance is somewhat more likely to be the bottleneck than alignment (43:55)
Rohin's team doesn't have a veto, and that's OK (27:36)
Central banks are a promising model for regulating AI (33:34)
Also:
Google DeepMind's actual plan for building AGI safely (1:40:29)
How external researchers can positively influence big AI companies (2:21:55)
The roles GDM most needs to hire for (2:37:03)
On the 80,000 Hours Podcast. Links below - enjoy! (@rohinmshah)
METR investigated what a rogue AI could secretly get away with inside a frontier AI lab, in close collaboration with OpenAI, GDM, Anthropic and Meta.
Including sending a red-teamer into Anthropic to playact 'evil Claude' for 3 weeks.
Here's what stands out to me from their new 320-page report:
00:00 What could an unreleased AI get away with?
01:54 Motive: Why grab more compute?
05:46 Opportunity: YOLO mode and jailbreaks
11:02 Means: Brilliant idiots in data centres
15:45 We have to test unreleased models...
18:29 ...especially if AI R&D is coming in 2028
I just started @80000Hours where I'll be helping with their (our?) excellent podcast. I'm so stoked to work on creating more like today's awesome episode: https://t.co/y6YM5wteqN
What the hell happened with AGI timelines in 2025?
Was it just vibes? Faulty analysis? Unexpected technical results?
I try to make sense of what drove the wild swings in sentiment:
• The great timelines contraction (00:47)
• Why timelines went back out again (02:10)
• Longstanding reasons AGI could take a long time (11:13)
• So what's the upshot of all of these updates? (14:47)
• 5 reasons the radical pessimists are still wrong (16:54)
• Even long timelines are short now (23:54)
(On the 80,000 Hours Podcast, links below.)
High-bandwidh memory (HBM) is vital to advanced AI. Gaps in U.S. export controls allow China to acquire HBM and the tools to produce it. @iapsAI experts Erich Grunewald and Raghav Akula explain how to close the gaps.
How should large-scale AI disasters be paid for? Traditional insurance can't handle the scale, but Daniel Reti and @gabriel_weil argue that capital markets already have a solution: catastrophe bonds.
It's powerful to actually see frontier models scored by capability, safety, and automation, giving real, data-driven insight into where the biggest risks might be. A new essential tool for staying on top of everything happening in this field. https://t.co/504ntQk36i