From various reports OpenAI really did bolt a “Universal Verifier” onto the GPT-5 training loop.
And here's that paper, that OpenAI published earlier.
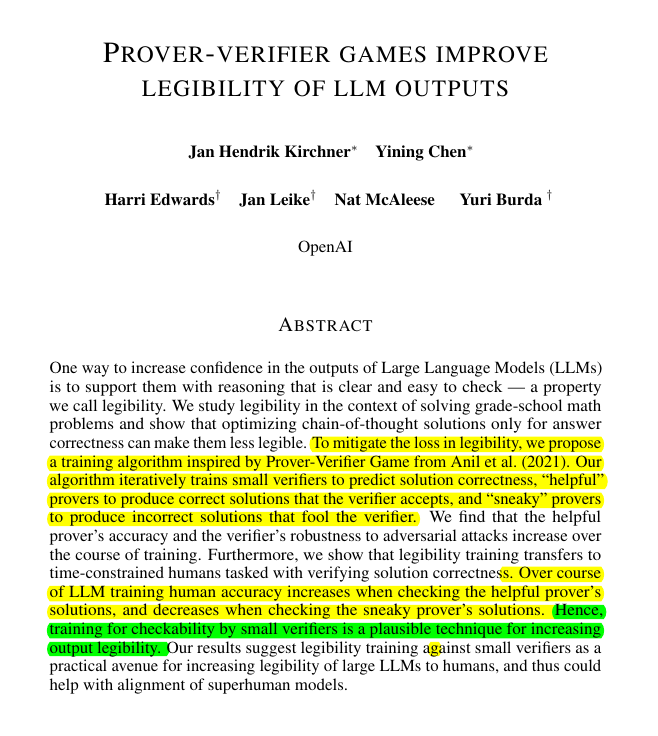
"Prover-Verifier Games Improve Legibility of LLM", showing a production-ready pipeline where a verifier model scores each reasoning chain and feeds that reward back into policy updates.
The paper is explicit that the verifier is small enough for large-scale rollout and is “designed for future GPT deployments”.
🔄 How the prover-verifier game works
Think of two personalities living in one model. The “helpful” persona solves a problem and tries to convince a lightweight verifier network that the answer is sound. The “sneaky” persona deliberately sneaks in wrong conclusions yet still aims to fool the same verifier. By alternating roles, the big model learns to write solutions that are harder to fake, while the small verifier sharpens its ability to flag errors.
---
An Aug-2024 Wired article explained how OpenAI swapped some human feedback with model-based critics when fine-tuning GPT-4 code helpers, noting the system “will be folded into RLHF for future mainline models”
GPT-5 is that next mainline model.
Another Superalignment paper from my time at OpenAI:
We train large models to write solutions such that smaller models can better check them. This makes them easier to check for humans, too.
https://t.co/caXSppyf5e
We trained advanced language models to generate text that weaker models can easily verify, and found it also made these texts easier for human evaluation.
This research could help AI systems be more verifiable and trustworthy in the real world. https://t.co/erOVzdynyk
1/ Excited to share our new paper: "Prover-Verifier Games Improve Legibility of LLM Outputs"! We explore how to make large language model (LLM) outputs easier to check and thereby more legible. 🧵
I’d like to thank my amazing collaborators @janhkirchner @burdayur @HarriLEdwards@__nmca__ and @janleike as well as the platform, human data, and comms team at @OpenAI for their support to make this work happen!
Excited to share our new work “Prover-Verifier Games improve legibility of language model outputs”! We trained strong language models to produce text that is more checkable by weak language models, and found that this also made it more legible to humans. https://t.co/jSIaurZboL
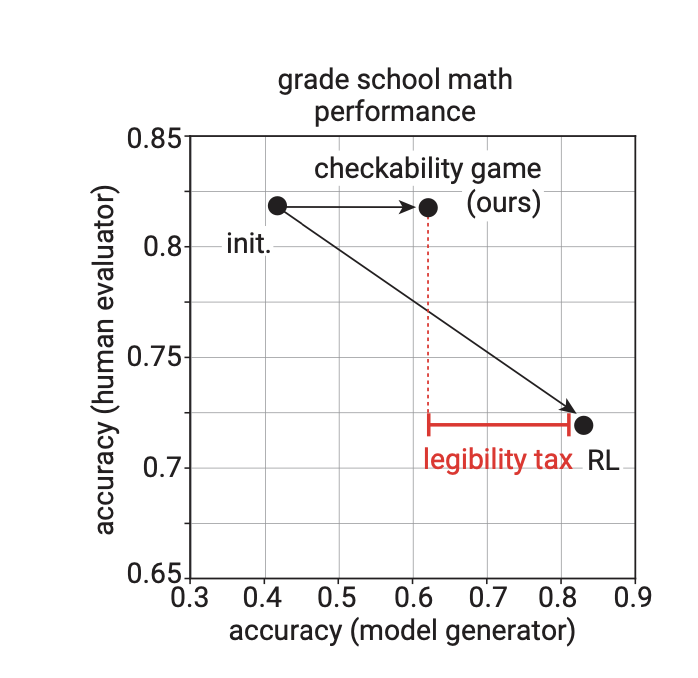
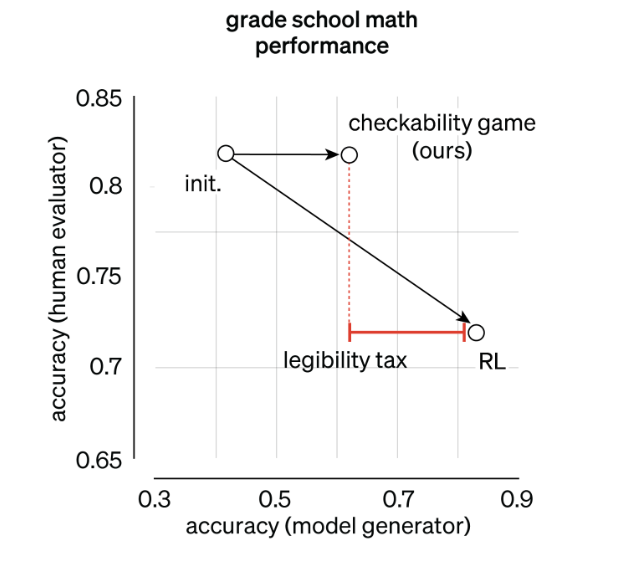
We found that optimizing for correctness on math problems leads to solutions that are less legible. Initialization pretrained on human-written math derivations is more legible, but has low accuracy. Our algorithm retains legibility, while partially recovering the accuracy.
Super excited about our new research direction for aligning smarter-than-human AI:
We finetune large models to generalize from weak supervision—using small models instead of humans as weak supervisors.
Check out our new paper:
https://t.co/8zxKf5LcAL
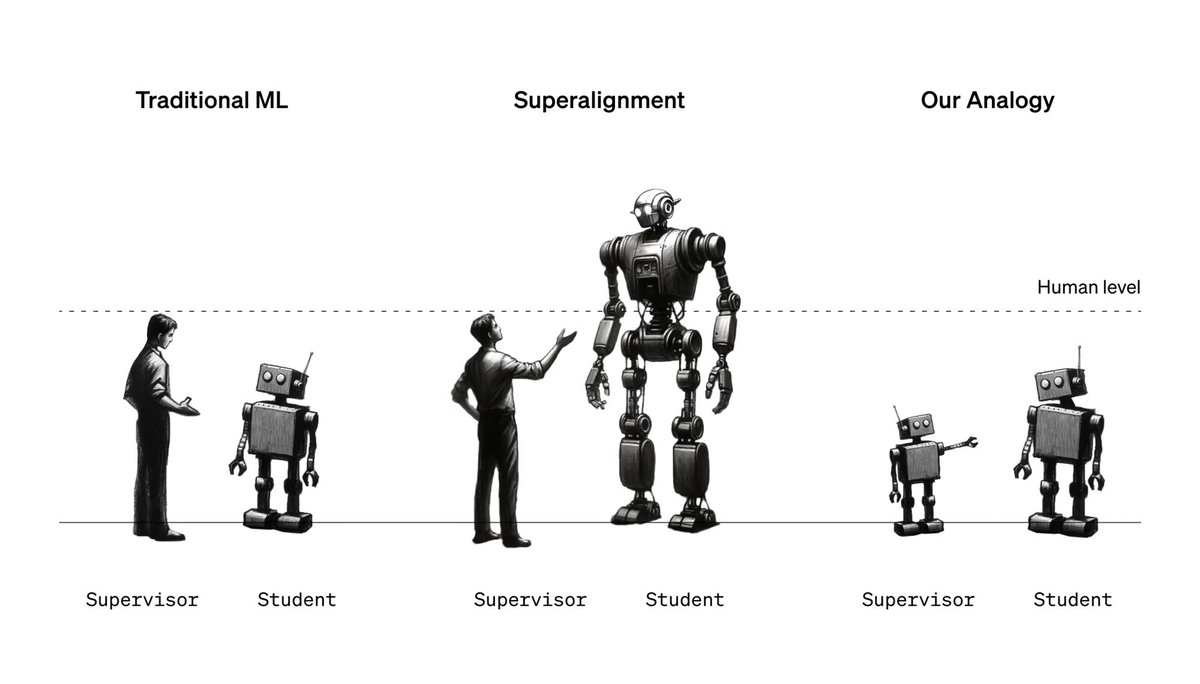
In the future, humans will need to supervise AI systems much smarter than them.
We study an analogy: small models supervising large models.
Read the Superalignment team's first paper showing progress on a new approach, weak-to-strong generalization: https://t.co/BiBpGdqtKj
Super excited about our new research direction for aligning smarter-than-human AI:
We finetune large models to generalize from weak supervision—using small models instead of humans as weak supervisors.
Check out our new paper:
https://t.co/8zxKf5LcAL
📢 Exciting new research: CaML is a causal meta-learning framework for personalized prediction of the effects of novel interventions. 🧪🔍 From personalized medicine to public policy and online marketing, CaML outperforms traditional methods by leveraging intervention's and individual's features. 🚀 #CausalMetaLearning #PersonalizedPrediction #InnovationInTheMaking
Great work by @h_nilforoshan@Michael_D_Moor@yusufroohani@cynnjjs Anja Surina n and Sara Oblak.
Many invariance-based approaches to domain generalization suffer from linear "environment complexity" (# environments needed to identify inv. features). In our #NeurIPS2022 paper, we show a *non end-to-end* feature matching algorithm can achieve logarithmic dependence!
@yiqinfu According to Blinkist, Sapiens claims that despite advancement in economics and health, human happiness has largely stayed constant throughout history. I wanted to ask what the evidence was!
RNNs and transformers with *infinite*-precision are universal approximators---but are they statistically learnable? We show that even finite-precision transformers can express any Turing machine, and they are learnable with polynomial samples. https://t.co/cXgvJRmpke
Past theory for domain generalization often suggests the number of training domains has to scale linearly in dimension. Any hope to work with a more realistic # of domains? We give an algorithm that needs log-in-dim # of domains on a toy data model https://t.co/zfWCXlhCcV. 1/6