@Blaz3Gam3r77@balubabear1312@Javi The only people I did answer to after this were the ones with an IQ below 10. Welcome to the group.
I just found out that having a normal and interesting discussion here is useless so :)
MiniMax M3.1 Flash weights are now public. 428B parameters total, 23B activated per token.
Agentic performance: A generational leap in agentic tasks, coding, and cybersecurity — 76.2 on BankerToolBench, 73.7% on DeepSWE v1.1, 61.7 on OSWorld V2, 29.6 on Agents' Last Exam, and 82.2 on CyberGym.
Efficient by design: MiniMax Sparse Attention and DSpark speculative decoding improve inference efficiency.
Hugging Face:
https://t.co/JDYA1zZh54
ModelScope:
https://t.co/DQcmOjTwhO
API: https://t.co/fHRdSV7BwZ
M Plan: https://t.co/LYnYZcsesu
MCode for desktop: https://t.co/SGmLTI3fFU
@Mashiro_0619 I usually get the highest cache hit on dsh so I use that for obvious reasons.
It’s also a good harness, just a bit of a pain in the ass to setup and set up if you wanna change a few things but I like it
@bradyodad44@Javi Your way of speaking shows the perfect example of a retarded person. Always amazed by the amount of low IQ a person can have. Impossible to express an opinion on this world nowadays
Running this on Colab on an L4 with strata. 30t/s on average, in the 20s for bigger projects. 200CU a month with colab pro and this set up gives about 130 hours a months of usage
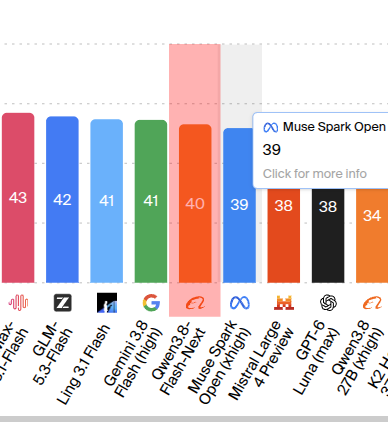
Qwen3.8-Flash-Next is such an underrated model.
It deserves way more attention.
It beats bigger Muse Spark Open (xhigh) on AA Intelligence Index, despite being dramatically smaller.
Muse Spark Open is a 816B total parameters, with 42B active parameters per token
Qwen3.8-Flash-Next on other hand is smaller, 125B + 51.B n-gram embeddings with 6B active per token.
And we all are running this on our devices with special thanks to @coldniko's Strata.
Imagine what the next Qwen generation could do. I cannot, we are so close to next release.
LFG !!
Mmh yeah but when you spread 10000 folds throughout a year, the material has long periods between cycles instead of a continuous one.
That allows the polymers and adhesive of the display to undergo stress relaxation and viscoelastic recovery so i think it would have much less impact over a year than with a continuous cycle.
Unbelievable! The iPhone Duo's display has been hiding a shocking secret!
Someone finally dared to peel off the matte film covering the iPhone Duo's display, and what they discovered was astonishing.
With the film removed, the screen underneath looks surprisingly uneven, with visible bumps, ripples, and even wrinkles!
Last month, we demonstrated high-rate alchemy: turning mercury into real, stable gold, beating CERN’s record by a factor of 10.
Last week, we enriched isotopes in the world’s most powerful plasma centrifuge, beating the Soviet record that stood for 40 years.
Now, we’re building a fusion reactor in San Francisco to achieve record power density.
🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 https://t.co/JGAik1kgk0
1/4
I’m sorry but… how is he supposed to make profit on them?
Like no one would buy it overpriced but just wait like a month and get their from apple anyway so 🤨
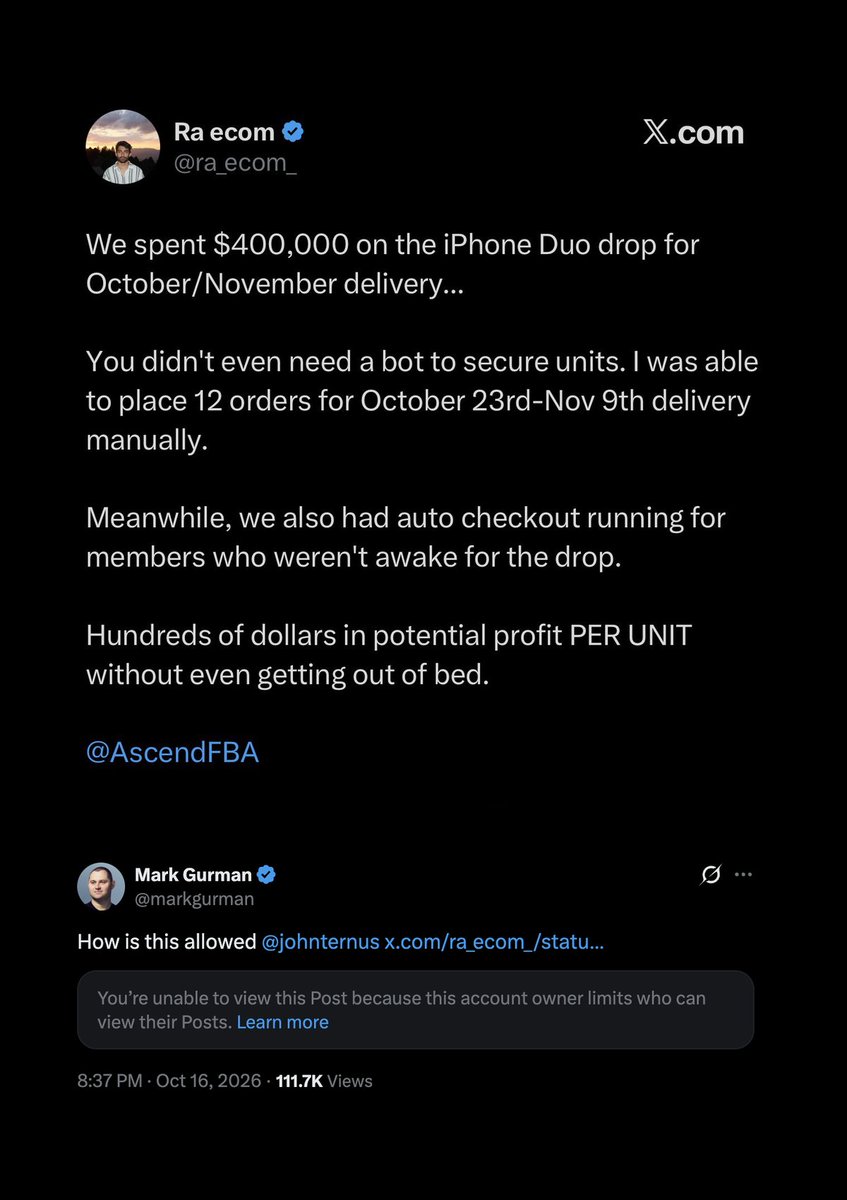
❗️ A scalper says they spent $400k on Apple's $2k iPhone Duo as preorders opened, touting "hundreds of dollars in potential profit PER UNIT".
Bloomberg's Mark Gurman tagged Apple CEO John Ternus, asking "How is this allowed"
The account has since gone private, screenshot: