I don’t think people appreciate what it took to ship grok 4.5/4.6 It took literal blood sweat and tears. I don’t think this rate of progress would be possible anywhere else without @elonmusk and @aman_madaan
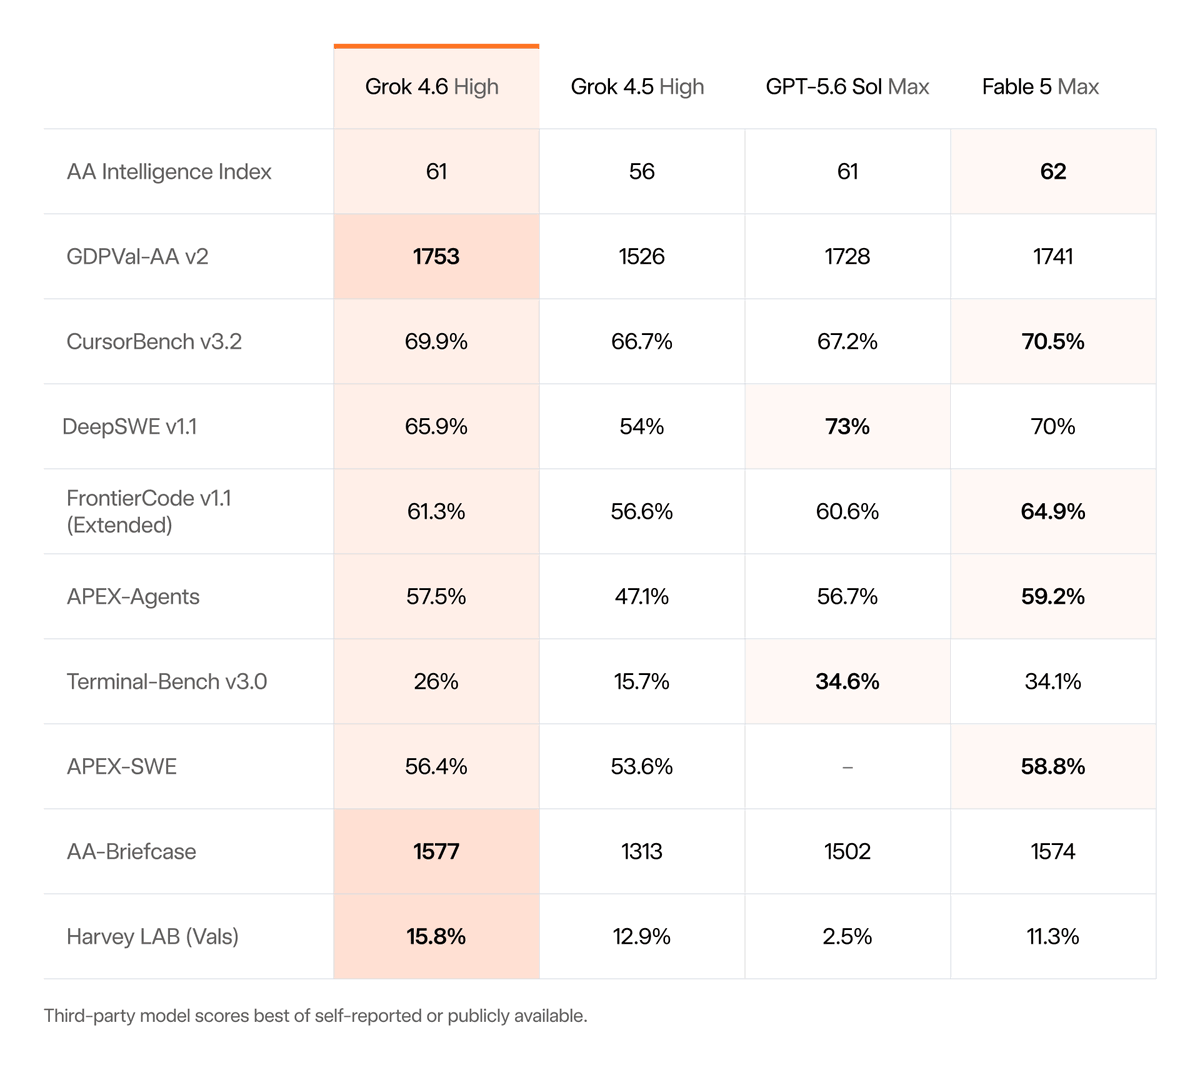
SpaceXAI's Grok 4.6 scores 61 on the Artificial Analysis Intelligence Index, joining the frontier in line with GPT-5.6 Sol, with standout agentic performance at lower cost
Grok 4.6 gains 5 points over Grok 4.5 on the Intelligence Index just over one month after its release, or +23 points compared to Grok 4.3. This brings SpaceXAI back to the intelligence frontier alongside OpenAI, behind only Anthropic.
Key takeaways:
➤ Grok 4.6 joins the frontier of the Artificial Analysis Intelligence Index: It scores 61, in line with GPT-5.6 Sol (max), behind Claude Opus 5 (max, 63) and Claude Fable 5 (max with fallback, 62), and just ahead of Kimi K3
➤ Strong agentic performance: Grok 4.6 achieves a GDPval-AA v2 Elo of 1753, behind only Claude Opus 5 and with overlapping confidence intervals with Claude Fable 5 and Qwen3.8 Max. It scores 50.7% on 𝜏³-Banking, among the top two scores alongside Qwen3.8 Max (51.3%), and 88.4% on Terminal-Bench v2.1, in line with the leading models
➤ Frontier-level intelligence at lower cost: Headline pricing is unchanged from Grok 4.5 at $2/$6 per 1M input/output tokens, 60%+ below Claude Opus 5 ($5/$25) and GPT-5.6 Sol ($5/$30). It cost $0.84 per task, the same as Kimi K3 with slightly higher intelligence, placing it on the Intelligence vs. Cost per Task Pareto frontier
➤ Grok 4.6 sits at Fable 5-tier on AA-Briefcase, our private benchmark of long-horizon agentic knowledge work tasks, with an Elo of 1577 - behind the Claude Opus 5 family. It is notably turn-efficient, completing tasks in ~53 turns and ~0.5B input tokens on average vs. ~103 turns and ~2.0B input tokens for Claude Opus 5 (max)
Other model details:
➤ Context window of 500k tokens (unchanged from Grok 4.5)
➤ Pricing of $2/$6 per 1M tokens of input/output; cache hits discounted to $0.5 per 1M tokens, an increase over Grok 4.5’s $0.3 per 1M tokens for cache hits
Congratulations to @SpaceXAI and @elonmusk on the release!
People keep asking me: what's different about optimization in RL?
Seemingly nothing — the pre-training stack just works (Adam, even SGD 👀 @saagnikkk).
Bringing some answers from my last work (sorry for the delay — been cooking 🚀).
We introduce ISO: Isospectral Optimization: an RLVR-native optimization stack.
Built on one simple observation, spectral inheritance: RLVR can reuse the base model's spectrum and acquire new behavior purely through the singular frames.
🧩 Offline: ISO-Merger — consolidates RL experts into one model with no data, no rollouts, no OPD. Checkpoints only.
⚙️ Online: ISO-Optimizer — a drop-in wrapper on AdamW / Muon that matches AdamW's accuracy with ~2.7× fewer steps on Qwen3-8B-Base.
📄 https://t.co/ty1FrAveA5
🌐 https://t.co/xzXf6V8ukO
🧵👇
Excited to help bring Grok 4.5 to life 🚀 Fast, capable, and a huge leap for us.
Over the past few months, our small team pushed RL scaling to the next level and reached top-tier agentic coding performance.
This one was all-in for me: driving core algorithmic changes across RL stability and intelligence per token, while spending many long days and nights in the bigrun loop with my amazing xAI colleagues.
Many doubted us, but the incredible people at @SpaceXAI made it happen.
More to come 😎
My favorite thing about this model is how light/fast it feels for the level of capability. We focused on extracting as much intelligence-per-latency as we could.
Many more bigruns to run and RL recipes to scale.
Grok 4.5 is out! 🚀
I spent the past few months as part of the Coding RL Bigrun and RL Science team, pushing RL scaling to help deliver Grok 4.5.
Proud to have contributed to this model, working on core RL algorithm changes and executing bigruns at true frontier scale with the team.
Huge shoutout to everyone at @SpaceXAI who helped make this happen!