Grok 4.5 is out! 🚀
I spent the past few months as part of the Coding RL Bigrun and RL Science team, pushing RL scaling to help deliver Grok 4.5.
Proud to have contributed to this model, working on core RL algorithm changes and executing bigruns at true frontier scale with the team.
Huge shoutout to everyone at @SpaceXAI who helped make this happen!
SpaceXAI’s Grok 4.5 scores 54 to place fourth on the Artificial Analysis Intelligence Index following only Fable 5, GPT-5.5, and Opus 4.8. It scores on par with GPT-5.5 in Codex on the Artificial Analysis Coding Agent Index in the Grok Build harness, at much lower cost
Grok 4.5 improves 16 points over Grok 4.3 on the Intelligence Index, bringing SpaceXAI to the intelligence frontier behind only OpenAI and Anthropic, and outperforming all open weights models and notably Google’s Gemini models. Key standout areas of performance are agentic knowledge work and coding.
Grok 4.5 in Grok Build scores 76 on the Artificial Analysis Coding Agent Index, on par with GPT-5.5 (xhigh) in Codex and just below Fable 5 (max) in Claude Code, and at a small fraction of the token usage and price.
Congratulations to @SpaceXAI, @cursor_ai, and @elonmusk on the impressive release!
Key Takeaways:
➤ Grok 4.5 performs very strongly on agentic tasks. Grok 4.5 ranks #4 on GDPval-AA v2 with an Elo of 1543, between Claude Opus 4.8 (1600) and GLM-5.2 (1513). It achieves the top score on 𝜏³-Banking of 33%, above 31% from GPT-5.5 (xhigh), and sits on the cost vs performance Pareto frontier across all three agentic evaluations in the Intelligence Index
➤ Grok 4.5 is one of the most cost efficient models to run for near-frontier intelligence. It costs $0.31 per task on the Artificial Analysis Intelligence Index and $2.59 per task on the Artificial Analysis Coding Agent Index within Grok Build
➤ Low cost for Grok 4.5 is driven by both low pricing and token efficiency. Grok 4.5 has a headline price over 60% lower than Claude Opus 4.8 and GPT-5.5, and used ~14k output tokens per Intelligence Index Task - over 60% lower than Opus 4.8. On the Coding Agent Index, Grok 4.5 stands out on the Pareto frontier of Coding Agent Index score vs. Total Tokens, using only 1.9M tokens for the Coding Agent Index while scoring 76
➤ As a coding agent, Grok 4.5 in Grok Build is on par with GPT-5.5 and offers efficiency benefits: In our Artificial Intelligence Coding Agent Index that consists of DeepSWE, Terminal-Bench v2, and SWE-Atlas QnA, Grok 4.5 in Grok Build ranks third, on par with GPT-5.5 (Codex) and below Fable 5 (Claude Code). It is also very efficient in achieving this result: Grok 4.5 in Grok Build cost $2.49 per task while Fable 5 in Claude Code cost $11.80 and GPT-5.5 in Codex $5.07. This is driven by relatively low token pricing and the model using far fewer tokens than comparable models (1.9M average tokens used per task), significantly less than Fable 5 in Claude Code (7.2M) and GPT-5.5 in Codex (6.2M)
Other model details:
➤ Context window of 500k tokens - a reduction from Grok 4.3’s 1M token context, but retaining configurable reasoning and vision input
➤ Pricing of $2/$6 per 1M tokens of input/output; cache hits are discounted by 75% to $0.5 per 1M tokens, and costs still double with long (>200k token) inputs
➤ As Elon Musk has disclosed, Grok 4.5 is 3x larger than its predecessor at 1.5T parameters
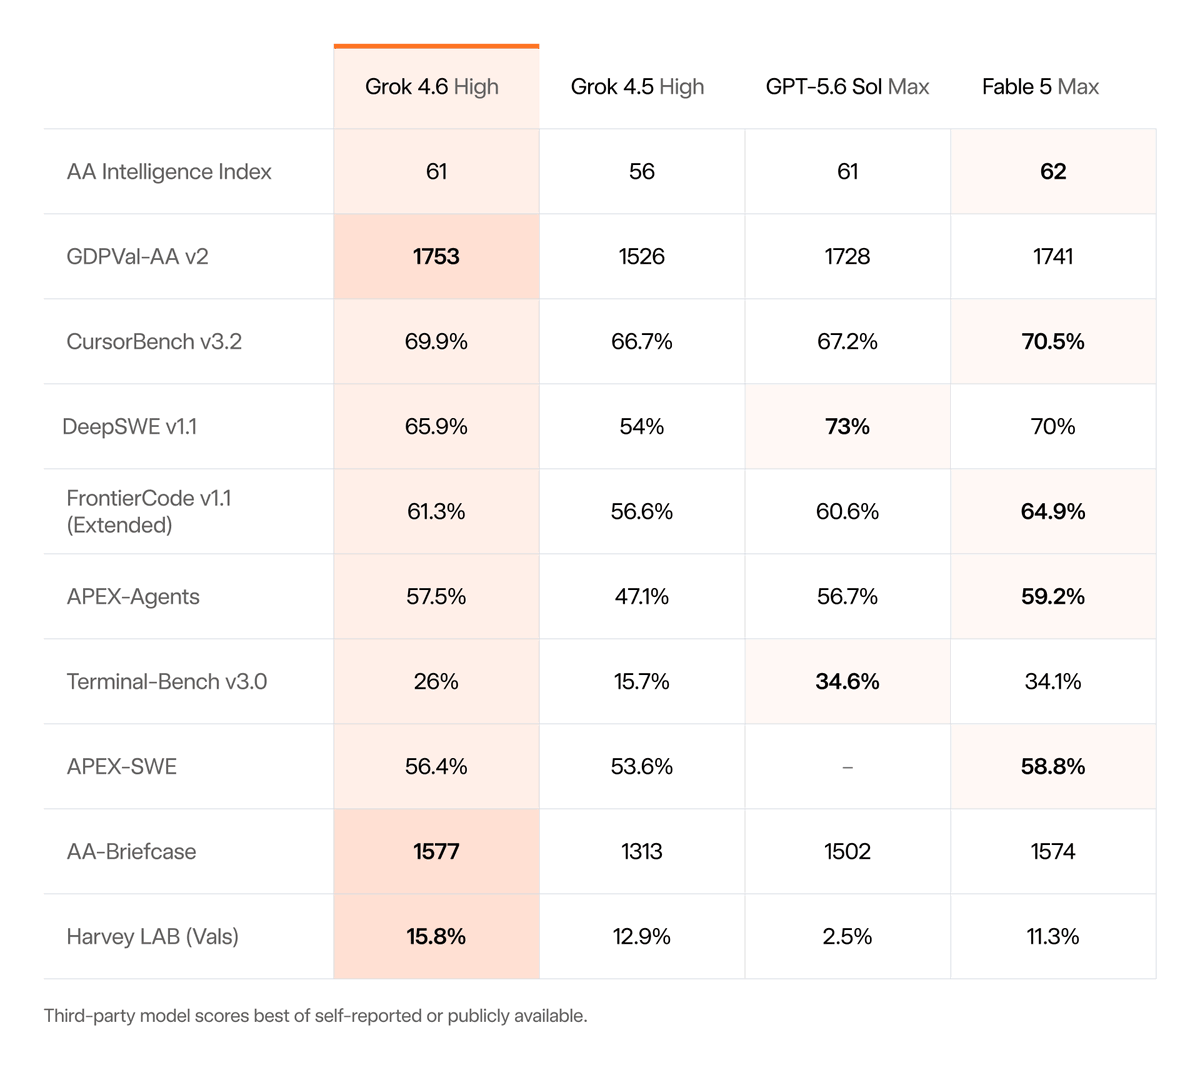
Enjoy Grok 4.6!
Building on our previous model, Grok 4.5, we refined the recipe with everything we learned and pushed it even further. Huge shoutout to everyone @SpaceXAI who helped make this happen!
People keep asking me: what's different about optimization in RL?
Seemingly nothing — the pre-training stack just works (Adam, even SGD 👀 @saagnikkk).
Bringing some answers from my last work (sorry for the delay — been cooking 🚀).
We introduce ISO: Isospectral Optimization: an RLVR-native optimization stack.
Built on one simple observation, spectral inheritance: RLVR can reuse the base model's spectrum and acquire new behavior purely through the singular frames.
🧩 Offline: ISO-Merger — consolidates RL experts into one model with no data, no rollouts, no OPD. Checkpoints only.
⚙️ Online: ISO-Optimizer — a drop-in wrapper on AdamW / Muon that matches AdamW's accuracy with ~2.7× fewer steps on Qwen3-8B-Base.
📄 https://t.co/ty1FrAveA5
🌐 https://t.co/xzXf6V8ukO
🧵👇
Try out Grok 4.5!
Grok 4.5 feels both highly intelligent and token-efficient: frontier-level coding, stronger long-horizon reasoning, and more reliable agentic behavior without feeling slow.
It’s been amazing to work on scaling coding RL and see it translate into real model improvements with the @SpaceXAI team.
Excited to help bring Grok 4.5 to life 🚀 Fast, capable, and a huge leap for us.
Over the past few months, our small team pushed RL scaling to the next level and reached top-tier agentic coding performance.
This one was all-in for me: driving core algorithmic changes across RL stability and intelligence per token, while spending many long days and nights in the bigrun loop with my amazing xAI colleagues.
Many doubted us, but the incredible people at @SpaceXAI made it happen.
More to come 😎
My favorite thing about this model is how light/fast it feels for the level of capability. We focused on extracting as much intelligence-per-latency as we could.
Many more bigruns to run and RL recipes to scale.
Excited to deliver Grok 4.5, with which we pushed RL scaling to the next level and achieve top-tier agentic coding performance.
The past few months have been intense for me — driving fundamental algorithmic changes on both RL stability and capability, iterating days and nights on RL infra, and executing bigruns at true frontier scale. Even a few months ago, I would not have believed this was possible with such a small team under such difficult situation. Shoutout to all colleagues at xAI! 🫡