Two important changes to timeline recommendations:
- New AI/SI ranking model that predicts probable time spent much better
- Retrieval model trained to surface posts people read all the way through
User active seconds is growing exponentially and hitting all-time highs almost every day:
we’re hiring a founding model designer to shape how Inkling behaves and feels.
bring a writer’s precision, a designer’s judgment, and the technical rigor to translate your ideas into data and evals.
please DM your best work or apply below.
https://t.co/EKIcKaztzX
We built high-throughput materials labs in Menlo Park to create a loop between experiments and models. The labs generate fresh data, the models learn from it, and then help us decide what to try next.
Using only 1,300 H200s, plus months of our experimental data, we mid-trained and RL’d an open-source model to surpass GPT-6 Astra on our analysis benchmark. We call it Neon.
This is real footage from our lab. We’re focusing first on hard problems in materials science, including superconductors, magnets, and semiconductor materials.
Read our blog posts below.
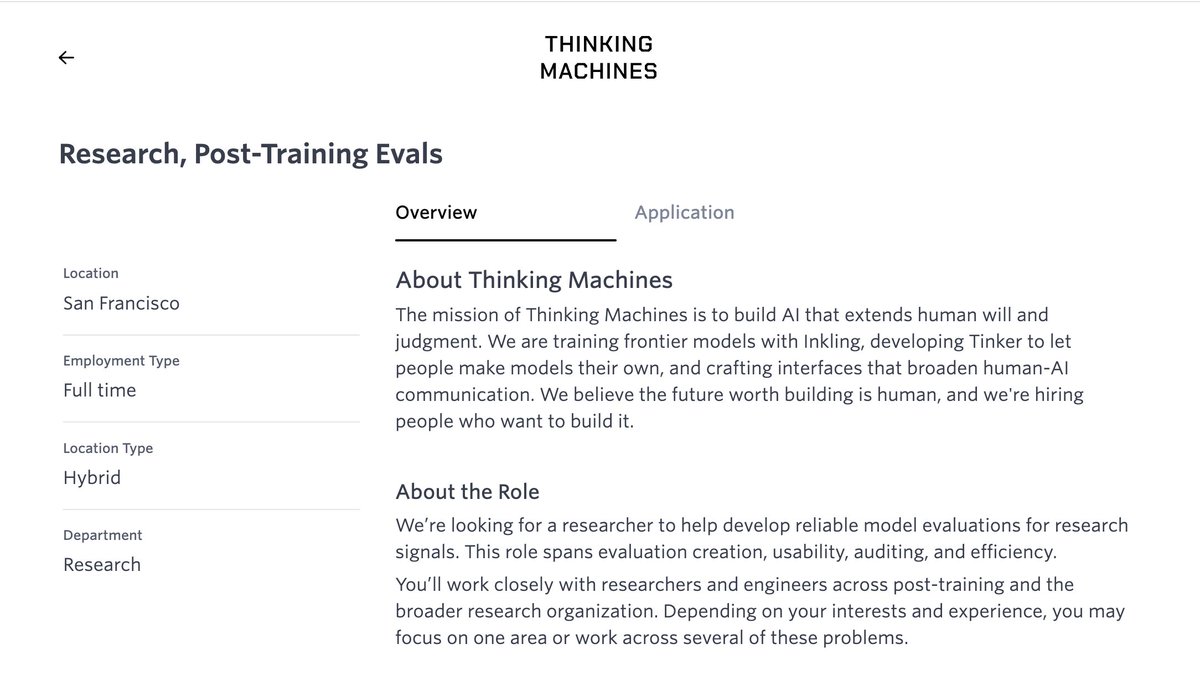
We’re growing our evaluation team at @thinkymachines. We care a lot about whether models are actually useful and whether our measurements are good enough to serve as the y-axis for scaling research.
We’ll work across a wide range of problems and support several workstreams, including building signal-bearing internal evals for predictive scaling, turning real user feedbacks and product workflows into evals that close usability gaps, auditing graders and harnesses, and developing new benchmarks for customizability.
If you want to work on this, apply here: https://t.co/bSkeUcdwYm
I'm in Hyderabad next week, and I'd love to meet people outside my usual clique and bring them together.
Who are the best people in these areas that you know based out of Hyderabad: deep tech, AI product, AI research, GPU whisperers?
https://t.co/dijinLuZFc
Inkling Small from @thinkymachines on ARC-AGI (Verified):
- ARC-AGI-2: 40.1%, $0.23/task
- ARC-AGI-1: 84%, $0.11/task
Inkling Small is the highest-scoring open-weight model evaluated by ARC Prize on both ARC-AGI-1 and ARC-AGI-2, setting a new cost-performance frontier.
As promised, Inkling-small is here! It is slowly becoming my fav model to use because its fast, takes less compute 😂 and sometimes even better capabilities than Inkling. Its probably one of the most capable models of its size in the market.
Today, we are releasing Inkling-Small.
Inkling-Small achieves comparable performance to Inkling at a quarter of its size. It features 276B total parameters, 12B active. We are making the full weights available.
https://t.co/BtYNcpkDRA
Fine-tune it on Tinker today, or chat with it in text, image, and audio on Tinker Playground.
Whereas I felt like it took a village to release inkling, inkling-small felt much more routine 😆 We just took the pipeline used for Inkling, passed in a smaller model, and voila - new model! Inkling small benefited quite a bit vs Inkling from some minor improvements, but there's still so much more left in the tank...
Some of the most interesting & urgent problems in AI safety live at the open-weights frontier. Solving them will take an ecosystem-level effort. Glad we're supporting this alliance.
A model drop by Thinky 🚨🚨
Have been doing some early testing on the model for the past couple of days. Here are some of my findings
1. The reasoning is sharp and concise! Always love to see models that dont ramble
2. Tool calling is beautifulllllll, Its consistent, clean, very well designed for streaming , multi-tool call per step, etc.!
3. Holds up impressively on agentic tasks. In my testing, I was particularly impressed with its ability to run long-horizon tasks with solid error recovery.
4. Most importantly, it was built from the ground up for post-training and customization and this is a real unlock for teams building on open source!! This will be greatly beneficial for continual learning workflows at @trajectorylabs!
Amazing step for American OSS models, really excited to keep "tinkering" with it lol
Feeling proud to have worked on making Inkling good at Agentic file generation. This is our first milestone with more to come :)
And thank you to everyone at @ArtificialAnlys for helping test Inkling!
Thinking Machines has released Inkling, the new leading U.S. open weights model, debuting at 41 on the Artificial Analysis Intelligence Index
@thinkymachines has previously released research previews of models and this is their first production language model release. The model is 975B total parameters, has 41B active parameters, and accepts text, image, and audio input modalities. The model is accessible via Thinking Machines’ Tinker platform API (256K context window) and weights are available on HuggingFace (1M context window).
Key results:
➤ Inkling debuts at 41 on the Artificial Analysis Intelligence Index, making it the leading open weights release from a U.S. lab. Inkling scores 3 points higher on the Intelligence Index (41) than the previous leading U.S. open weights model, Nemotron 3 Ultra (38), and also beats Gemma 4 31B (29) and gpt-oss-120b (24)
➤ Inkling stands out on agentic performance. It scores higher than both Kimi K2.6 and DeepSeek v4 Flash on both GDPval-AA v2 and 𝜏³-Banking: Inkling scores an Elo of 1238 on GDPval-AA v2, higher than Kimi K2.6 (1190) and DeepSeek v4 Flash max (1189) and scores 24% on 𝜏³-Banking, higher than Kimi K2.6 (21%) and just above DeepSeek v4 Flash max (23%)
➤ Inkling is token efficient compared to open weights leaders. Inkling averages 25K output tokens per Intelligence Index task compared to 43K, 38K and 37K by GLM-5.2 (max), Kimi K2.6 and DeepSeek v4 Pro (max) respectively
➤ Inkling natively supports image and audio multimodal inputs, a key differentiator among open weights models. Inkling accepts text, image, and audio input modalities. Images and videos are encoded via a hierarchical patch encoder and audio via discrete token encoding, with all modalities projected into a shared hidden space and processed jointly by the decoder
Additional model details:
➤ Size: 975B (41B active) parameters
➤ Input modalities: Text, image, and audio (text output)
➤ Context window: 256K tokens on Tinker, open weights model supports 1M
➤ Pricing per 1M tokens (64K context window): $1.87 input / $0.374 cached / $4.68 output
➤ Pricing per 1M tokens (256K context window): $3.74 input / $0.748 cached / $9.36 output