Our Muse Glimmer technical report is out!
Your AI agent, on your own machine. It's open, built for consumer hardware, and with #ExecuTorch it runs fast on your Mac or NVIDIA GPU.
Grateful for the opportunity to be a core contributor on this amazing team at @AIatMeta.
Today we published a technical report on Muse Glimmer, our 30B open-weight model built for agentic tasks on consumer hardware.
It runs at practical speeds on a Mac or PC with a single consumer GPU at 4-bit precision, and leads comparably-sized open models on tool use and multi-step planning.
Read about the model architecture, distillation recipe, quantization and more: https://t.co/H7n9qeDhxn
ExecuTorch on Arm Cortex-M! 🔥 Compiling ahead of time lets you fine-tune memory down to the last byte, which matters a lot on microcontrollers. Big thanks to Arm for a fantastic collaboration!
Arm Cortex-M microcontrollers power everyday devices from wearables to industrial sensors and home appliances. Deploying a PyTorch model to these edge devices no longer requires leaving the PyTorch ecosystem.
Through the ExecuTorch Cortex-M backend, quantized models lower directly to Arm's CMSIS-NN kernels. Because target hardware parameters are known at compile time, operator selection, weight layout, and memory planning are resolved ahead of time, allowing the core runtime to fit in under 20 KiB of flash.
Learn more about this technical milestone, developed in collaboration with @Arm, here: https://t.co/VssOUwpo7w
Local AI agents are hitting an inflection point, and we're pushing the boundaries with #ExecuTorch at Meta! Join our talk at the PyTorch Conference 2026 to see the exciting things we're building for the open ecosystem.
Build AI on the edge with ExecuTorch at a two-day @Meta + @Arm hackathon at San Francisco State University.
Students, developers, and AI enthusiasts can get hands-on experience building AI applications with ExecuTorch on Arm-powered devices, with technical talks, demos, workshops, and mentorship.
Participants will also have the chance to collaborate with fellow builders, showcase their projects to judges from Arm and Meta, and compete for prizes and recognition.
🔗 Learn more and register: https://t.co/pOQ3B5vMWm
@redp314 Try ExecuTorch - https://t.co/CGWQQTCIOk We have worked on some DFlash features as well for Muse Glimmer 30B (gguf quantized).
We are still developing some of the serving features, appreciate any feedback you have.
Today @AIatMeta introduced Muse Glimmer, an open-weight, 30-billion-parameter model distilled from Meta’s Muse Spark for on-device agentic workflows. Alongside, ExecuTorch is adding end-to-end support for running Muse Glimmer on @NVIDIA GPUs and Macs with @Apple silicon.
Why ExecuTorch? ExecuTorch offers a smarter, native approach:
⚡ Build in PyTorch: Implement your model and decoding strategies right in PyTorch as you normally would
⚡ Seamless Export: Export directly to ExecuTorch when you're ready for deployment
⚡ Automated Optimization: The framework automatically handles backend-specific lowering (Triton on CUDA, MLX-native, or Metal on Apple silicon) and uses ahead-of-time compilation to optimize the full execution path end-to-end
Learn more: https://t.co/ABzlzreEJz
5/ weights on hugging face now. running this week through ollama, LM Studio, vllm, sglang, together, fireworks, and openrouter, with llama.cpp, MLX, and executorch.
evaluated under meta's advanced AI scaling framework and cleared for open-weight release.
1/ big announcement today: we will be releasing an open weight version of muse spark 1.2 soon.
we also are releasing muse glimmer, a 30B agentic model with open weights under apache 2.0. muse glimmer can run on 24GB of VRAM without losing agentic reliability. 🧵
Today we're also opening the weights for Muse Glimmer, a great 30B parameter dense model that can run locally. Soon we'll also release the weights for Muse Spark 1.2, our latest foundation model. Meta is a strong supporter of open source and I'm proud of these releases. Congrats to @alexandr_wang and the MSL team for all your great work on these models.
Introducing Muse Glimmer, an open-weight 30B-parameter model optimized for local, always-on agent workflows.
Muse Glimmer delivers strong performance on key agentic use cases and benchmarks compared with leading models in its size category, and is designed to run entirely on consumer hardware like a Mac or PCs with performant GPUs.
In keeping with our long tradition of sharing fundamental AI research, we’re releasing model weights under a permissive Apache 2.0 license.
🧵👇
We’re advancing on-device AI with ExecuTorch, now deployed across devices including Meta Quest 3, Ray-Ban Meta, Oakley Meta Vanguard and Meta Ray-Ban Display.
By eliminating conversion steps and supporting pre-deployment validation in PyTorch, ExecuTorch accelerates the path from research to production, ensuring consistent, efficient AI across a diverse hardware ecosystem.
Read the full technical deep dive: https://t.co/CFqCVSj9b8
Announcing React Native ExecuTorch v0.4.0! 🎉
What’s new:
🧠 More LLMs – Integrate a wide range of LLMs into your React Native app
🔧 Tool calling capabilities – Enable LLMs to dynamically interact with APIs & tools
🔍 Text Embedding Models – Transform text into vectors for semantic tasks
🗣️ Multilingual Speech to Text – Get accurate transcription in multiple languages
🖼️ Image Segmentation – Generate precise masks for objects in images
🌐 Multilingual OCR – Extract text from images in multiple languages
Excited to introduce low-bit operators for Arm CPUs in TorchAO! Seamlessly works across all PyTorch surfaces including eager, torch.compile, AOTI, and ExecuTorch. Check out the details here: https://t.co/vDd6kLBwx4
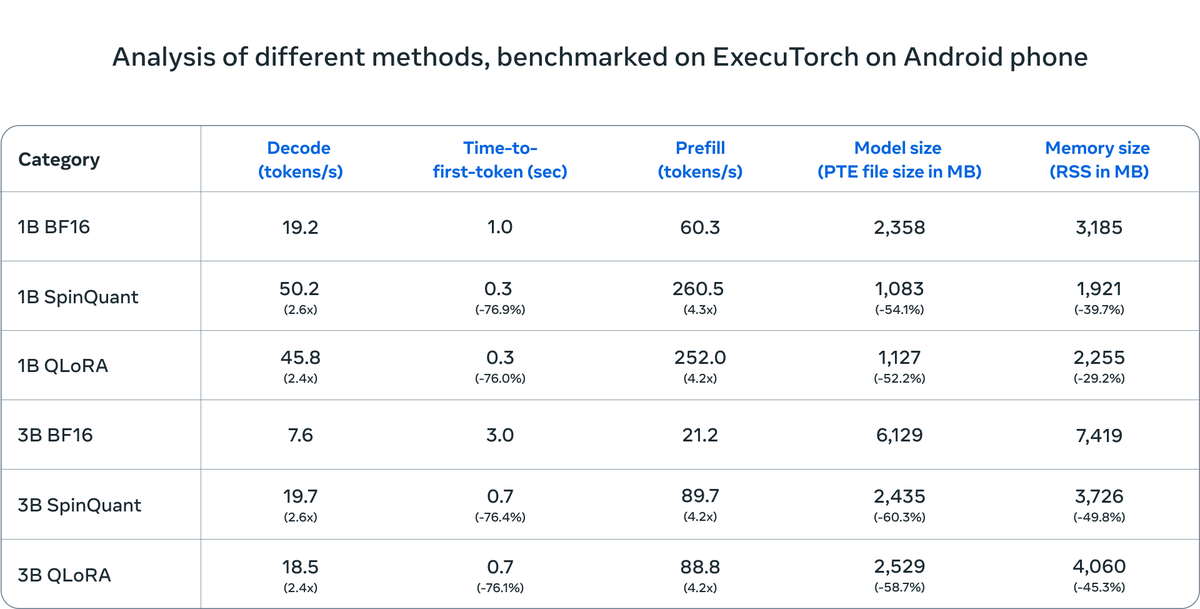
Thanks to close work with @arm, @mediatek and @qualcomm, these new models are ready to deploy on even more mobile CPUs.
We are also currently collaborating with partners to utilize NPUs for these quantized models for even greater performance.
Gian and Pareena will talk about @arm’s KleidiAI and other investments across server/edge and how native integration with #ExecuTorch enables performant execution of AI workloads, including Llama models on Arm-based hardware, https://t.co/yO9ikttAKc & https://t.co/nI4bdgkn8x (6/7)
@adamcohenhillel@BilginCatay We are actively pursuing Mali GPUs (or Android GPUs in general) through an ExecuTorch Vulkan Delegate.
Not RKNPUs yet. Curious, is rknn-toolkit would be a preferred way to leverage these?