I'm working on a project using Claude Opus right now, and I feel like it's gotten worse—it's just bug after bug; fixing one issue only reveals another. 🤬🤬🤬
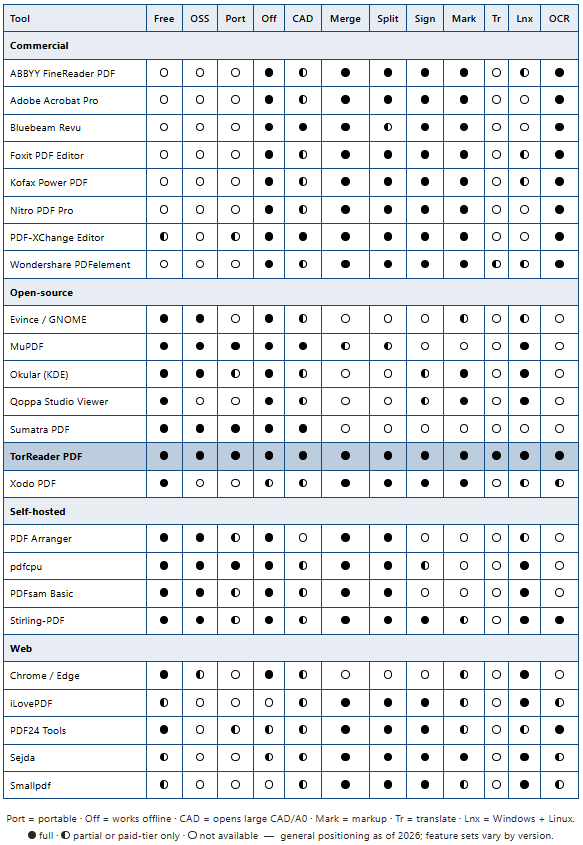
I just discovered Toreader PDF, open-source.
🚀 Open 200MB PDFs in 1–2s.
📑 Merge PDFs without losing bookmarks, split/extract/insert pages
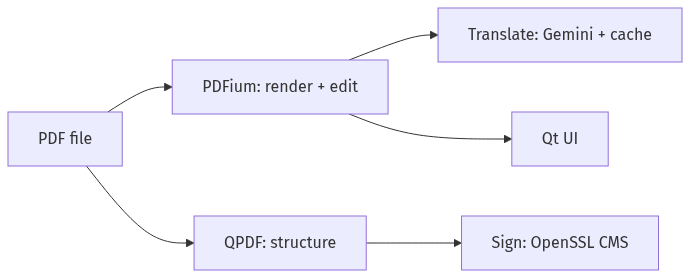
🌍 Translate PDF
✍️ Sign PDFs
💾 Safe editing
Look at https://t.co/ip1HG8wHBS
#PDFreader#opensource#MIT
I'm following ToreaderPDF and this version 2.2.4... the app is still fast and smooth, but this version zooms in so clearly you can see details down to 0.1mm, micro-text, it has OCR search, handwriting recognition, and highlighting. Is it really free?
#PDFreader#opensource#MIT
I'm a bit skeptical about this Toreader PDF repository. It can open a 950MB, 300-page PDF drawing file in just 10 seconds, and it still loads normally even at page 200 or page 50. It only uses 600MB of RAM. This 2.2.3 version is completely different from the previous garbage.
I just discovered Toreader PDF, open-source.
🚀 Open 200MB PDFs in 1–2s.
📑 Merge PDFs without losing bookmarks, split/extract/insert pages
🌍 Translate PDF
✍️ Sign PDFs
💾 Safe editing
Look at https://t.co/ip1HG8wHBS
#PDFreader#opensource#MIT
@49agents I reported the error, Claude Code scanned my codebase for errors, dispatched OpenCode Deepseek v4 Flash to fix the code, but the quota was still used up too quickly.
I just discovered Toreader PDF, open-source.
🚀 Open 200MB PDFs in 1–2s.
📑 Merge PDFs without losing bookmarks, split/extract/insert pages
🌍 Translate PDF
✍️ Sign PDFs
💾 Safe editing
Look at https://t.co/ip1HG8wHBS
#PDFreader#opensource#MIT
🌐 How to code from a browser and never lose a job?
- Editor: code-server, VS Code in the browser
- Reach it: Cloudflare Tunnel + Access, no ports
- Durable shells: tmux, detach and reattach
- Close the tab, the build keeps running
The wiring ↓
#RemoteDev#DevTools#AI#LLMs
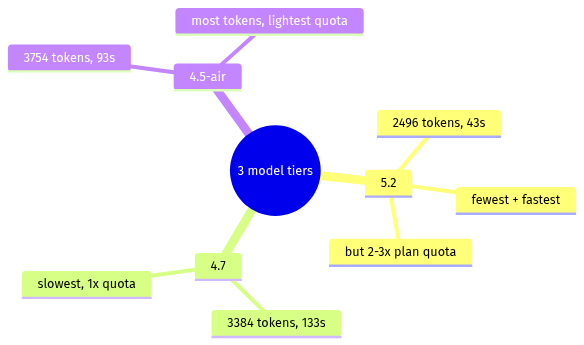
💳 API tokens or a flat coding plan, which is cheaper?
- API: pay per token, drains per call
- Plan: flat fee, billed by request quota
- Trap: a heavy model burns 2-3x quota
- Promo windows pull it back to 1x
- Off-plan model = $0 wallet stall
Pick by how you code ↓
#AI#LLM
💳 API tokens or a flat coding plan, which is cheaper?
- API: pay per token, drains per call
- Plan: flat fee, billed by request quota
- Trap: a heavy model burns 2-3x quota
- Promo windows pull it back to 1x
- Off-plan model = $0 wallet stall
Pick by how you code ↓
#AI#LLM
🔌 How to run Codex CLI on a non-OpenAI model?
- Codex dropped chat API, Responses only now
- Your provider speaks only chat completions
- Bridge: LiteLLM proxy, port 4037
- Prefix zai/ not openai/ to translate
- Hook: drop tool type custom or 400
The wiring ↓
#AI#DevTools
🔌 How to run Codex CLI on a non-OpenAI model?
- Codex dropped chat API, Responses only now
- Your provider speaks only chat completions
- Bridge: LiteLLM proxy, port 4037
- Prefix zai/ not openai/ to translate
- Hook: drop tool type custom or 400
The wiring ↓
#AI#DevTools
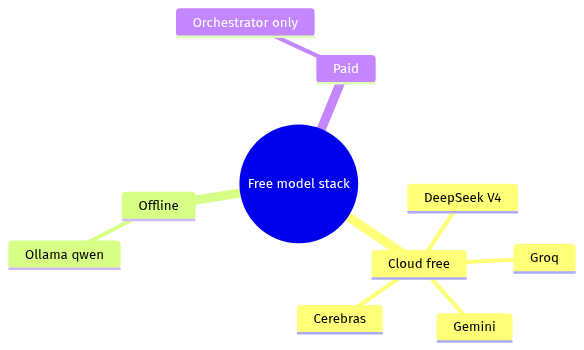
🆓 How to build an all-free LLM inference stack?
- Main coder: DeepSeek V4
- Research: Gemini, 1500 req/day free
- Fast inference: Groq, Cerebras, NVIDIA
- Offline fallback: Ollama (qwen)
- Pay for one thing: the orchestrator brain
The stack ↓
#AI#LLM
🍓 How to self-host an API on a Raspberry Pi?
- App: FastAPI or Node, kept alive by PM2
- Expose it with a Cloudflare Tunnel
- No port-forward, DNS + TLS free at the edge
- Works behind CGNAT, survives reboots
The wiring ↓
#SelfHosted#RaspberryPi
🆓 How to build an all-free LLM inference stack?
- Main coder: DeepSeek V4
- Research: Gemini, 1500 req/day free
- Fast inference: Groq, Cerebras, NVIDIA
- Offline fallback: Ollama (qwen)
- Pay for one thing: the orchestrator brain
The stack ↓
#AI#LLM
✍️ How to digitally sign a PDF from code (PAdES)?
- Add a sig dict: adbe.pkcs7.detached
- Reserve a /ByteRange over the whole file
- Hash everything except the signature hole
- Sign it with OpenSSL CMS, then self-verify
The byte dance ↓
#PDF#Crypto
🆓 How to build an all-free LLM inference stack?
- Main coder: DeepSeek V4
- Research: Gemini, 1500 req/day free
- Fast inference: Groq, Cerebras, NVIDIA
- Offline fallback: Ollama (qwen)
- Pay for one thing: the orchestrator brain
The stack ↓
#AI#LLM
🆓 How to build an all-free LLM inference stack?
- Main coder: DeepSeek V4
- Research: Gemini, 1500 req/day free
- Fast inference: Groq, Cerebras, NVIDIA
- Offline fallback: Ollama (qwen)
- Pay for one thing: the orchestrator brain
The stack ↓
#AI#LLM
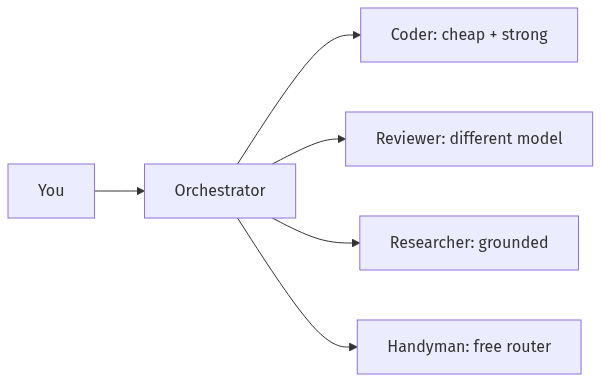
🧠 How to run a full dev team solo with AI?
- You drive: an orchestrator model
- Coder: a cheap, strong model
- Reviewer: a DIFFERENT model, catches more
- Researcher: a search-grounded model
- Handyman: a free router for tiny edits
Steal the wiring ↓
#AI#BuildInPublic