The Dolphin Inference API is now live
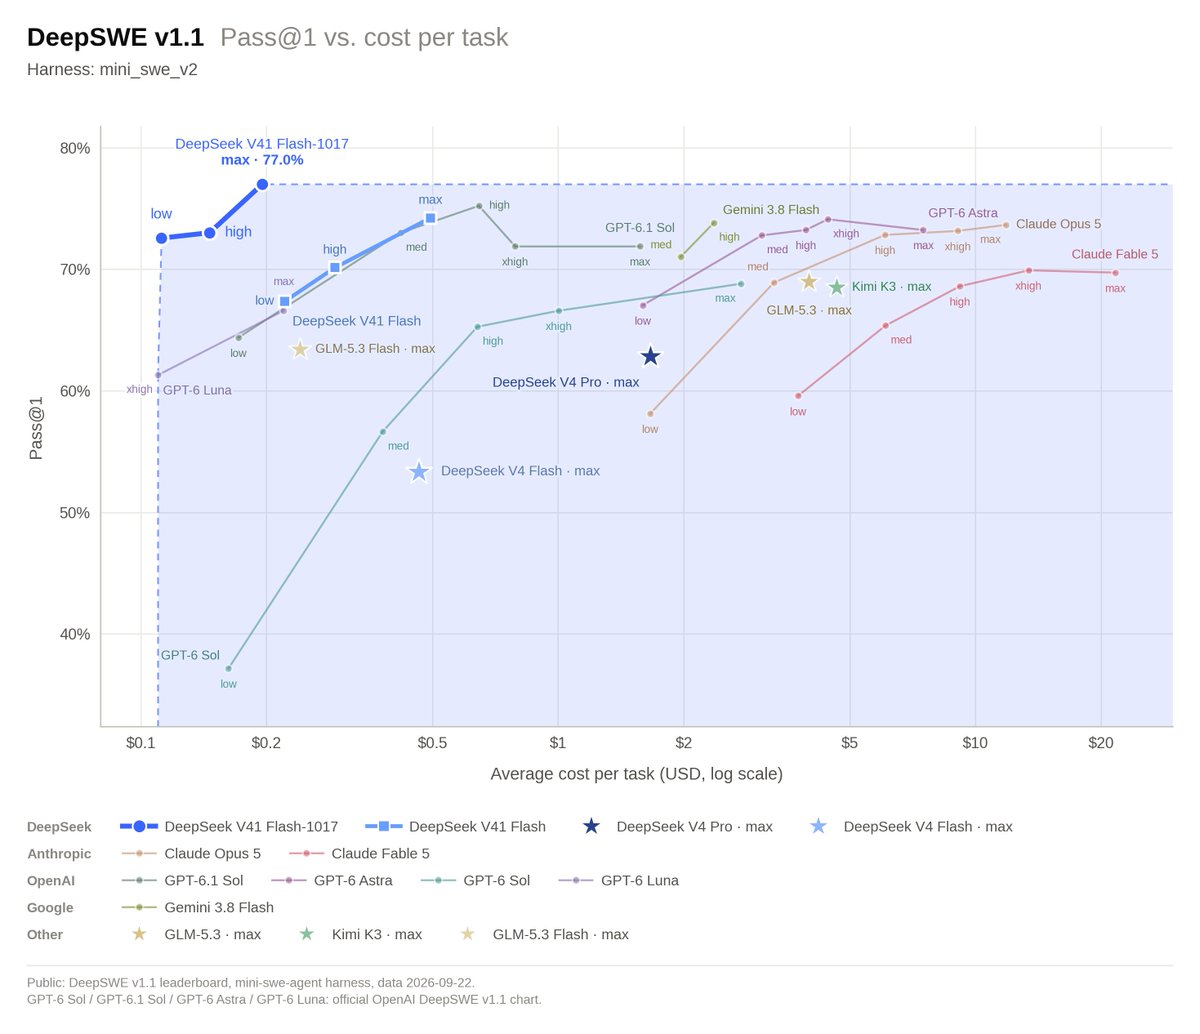
Powered by DeepSeek V4.1 Flash, it delivers Opus 5-class coding & agentic performance at 97% lower cost than frontier models
$30 free credits for the first 1,000 signups
Start building with the cheapest API on the market → https://t.co/izrWuq0l9H
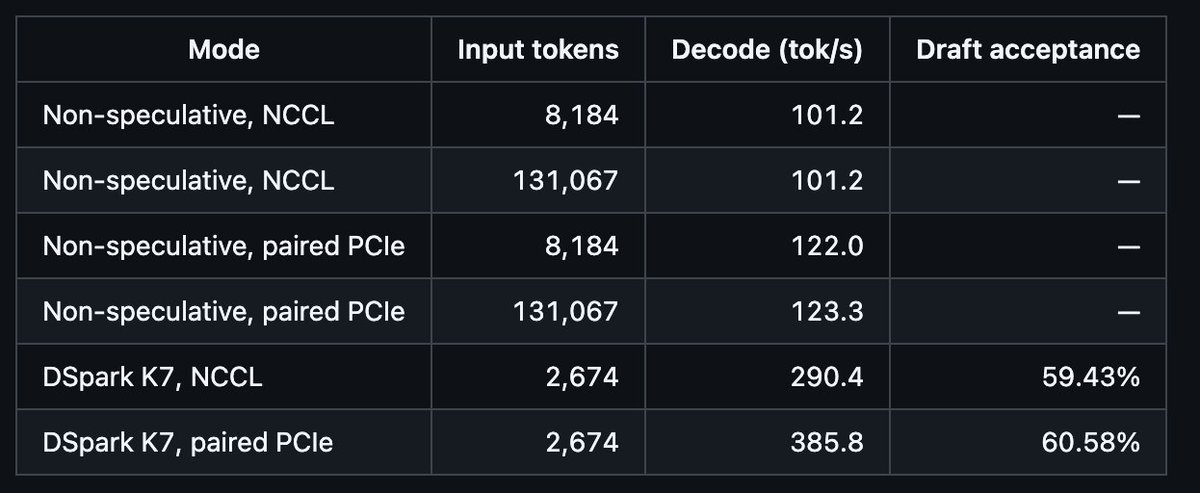
It's a much bigger jump than previously thought after some more tweaks. 21% increase without spec decode, 32% with spec.
These numbers are averages after running 10 requests (sequentially) in 3 separate servers to minimize any variance.
Hi @gakonst
We run inference on distributed GPUs that run our software
Small machines run Gemma 26B
Larger machines run DeepSeek Flash
Nvidia only right now but will be supporting AMD + Apple soon
dm for API key access + will share info about how we verify nodes are running the correct model
550 GPUs online right now
We pay contributors between 30-60% of the cloud rental price (they benefit from no uptime commitment, we load balance between all nodes running a model so they can join & leave the pool anytime)
Stats here
https://t.co/woCr4eyttL
New all-reduce kernels that optimize for small-message latency across PCIe-connected GPUs. 12% end-to-end decode speedup for DeepSeek-V4.1 Flash on 4x RTX 6000 Pro Server GPUs.
https://t.co/95qVvAISWW
Introducing SERV Hackathon 02 track partners:
@dphnAI@GoKiteAI@reppo
From inference and agentic payments to AI data markets, add SERV to your AI stack and build more reliable agents at lower cost.
Hackathon info drops next week.
Build with SERV: https://t.co/QCLNPi1207
Email signup coming soon, so no wallet needed after that
We use telegram auth as a more private version of sybil attack prevention compared to phone numbers, as it is hard to get multiple accounts & we don’t get any information about you with this
To prevent people mass claiming coupons
DeepSeek-V4.1-Flash-1017 is now live on the Dolphin API
$10 in free API credits for the next 5,000 signups
Lowest pricing on the market at $0.01 / $0.07 per million tokens
https://t.co/Vc80bqhjoJ
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
@megastuffs Adding email signup + stablecoin payments during the week
& the rest of that was already planned, just working through things based on priority
This filled very fast so dropping another key
API10 - $10 free credit for the next 5000 signups
https://t.co/izrWuq0l9H
Cheapest DeepSeek inference on the market
$0.01 / $0.07 with a 97%+ cache hit rate
The Dolphin Inference API is now live
Powered by DeepSeek V4.1 Flash, it delivers Opus 5-class coding & agentic performance at 97% lower cost than frontier models
$30 free credits for the first 1,000 signups
Start building with the cheapest API on the market → https://t.co/izrWuq0l9H
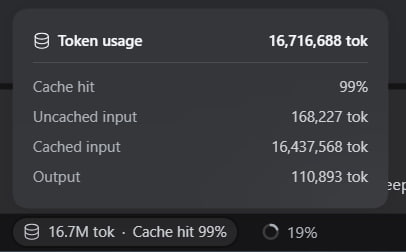
Running @dphnAI API on my local machine using DeepSeek harness. 99% Cache hit, 0.2$ cost to use 16M tokens. 😍
base:0xed664536023d8e4b1640c394777d34abaff1df8f
Great example of inference capital markets
Today most of us consume inference via subsidized monthly plans, but these won’t last forever and many builders can only use API inference
That’s where markets like @dphnAI come in, congrats on this going live!
@Greg_GL_87 No rate limits unless nodes are saturated
There is a 10 minute queue & after that requests drop
Already have a very high capacity but will be adding more machines as we scale in usage
The Dolphin Inference API is now live
Powered by DeepSeek V4.1 Flash, it delivers Opus 5-class coding & agentic performance at 97% lower cost than frontier models
$30 free credits for the first 1,000 signups
Start building with the cheapest API on the market → https://t.co/izrWuq0l9H
GM AI V2 at @token2049 was a banger 🔥
@DineroDom0 sits down with @GatheringGwei from @dphnAI to talk about cheaper AI inference, their distributed GPU network, and Flipper(their multi-agent engineering harness)
👀Watch till the end for a limited-time code to claim $50 in free inference credits
More models soon to be added to the API, including but not limited to ->
• Minimax H3 (video generation)
• Gemma 4 26B
• Qwen 3.8 Flash
• Qwen Image 2.1 Turbo
• Qwen 3 TTS
+
On top of the $30 in free credits, anyone who signs up will be receiving early access to try our coding harness Flipper (more info on this in the linked post below)
https://t.co/v2ne46Ofvo
Flipper is our multi-agent engineering harness
The larger model plans & directs the execution of your project while frequently handing off well-defined tasks to cheaper workers running a smaller “economical” model
This typically results in over 60% cost savings compared to using Astra directly with a minimal difference in output quality
Notice the different types of subagents working in this timelapse
Our inference network processed over 8T tokens across 1.6k unique workers since inception
During that period of time we were able to:
• improve our anti-cheat systems
• scale up to thousands of workers & GPUs across the globe
• work with and around slow workers while still giving them the chance to contribute
• cut worker setup down to a few simple steps
• make routing much more stable in capacity recovery states
Benchmarking of our multi-node DeepSeek V4.1 Flash pool shows a consistent 96-98% average cache hit rate on agentic usage
The high frequency of cache hits results in the fastest & most cost effective API experience for prefill heavy usage that is typical with agent / harness workloads
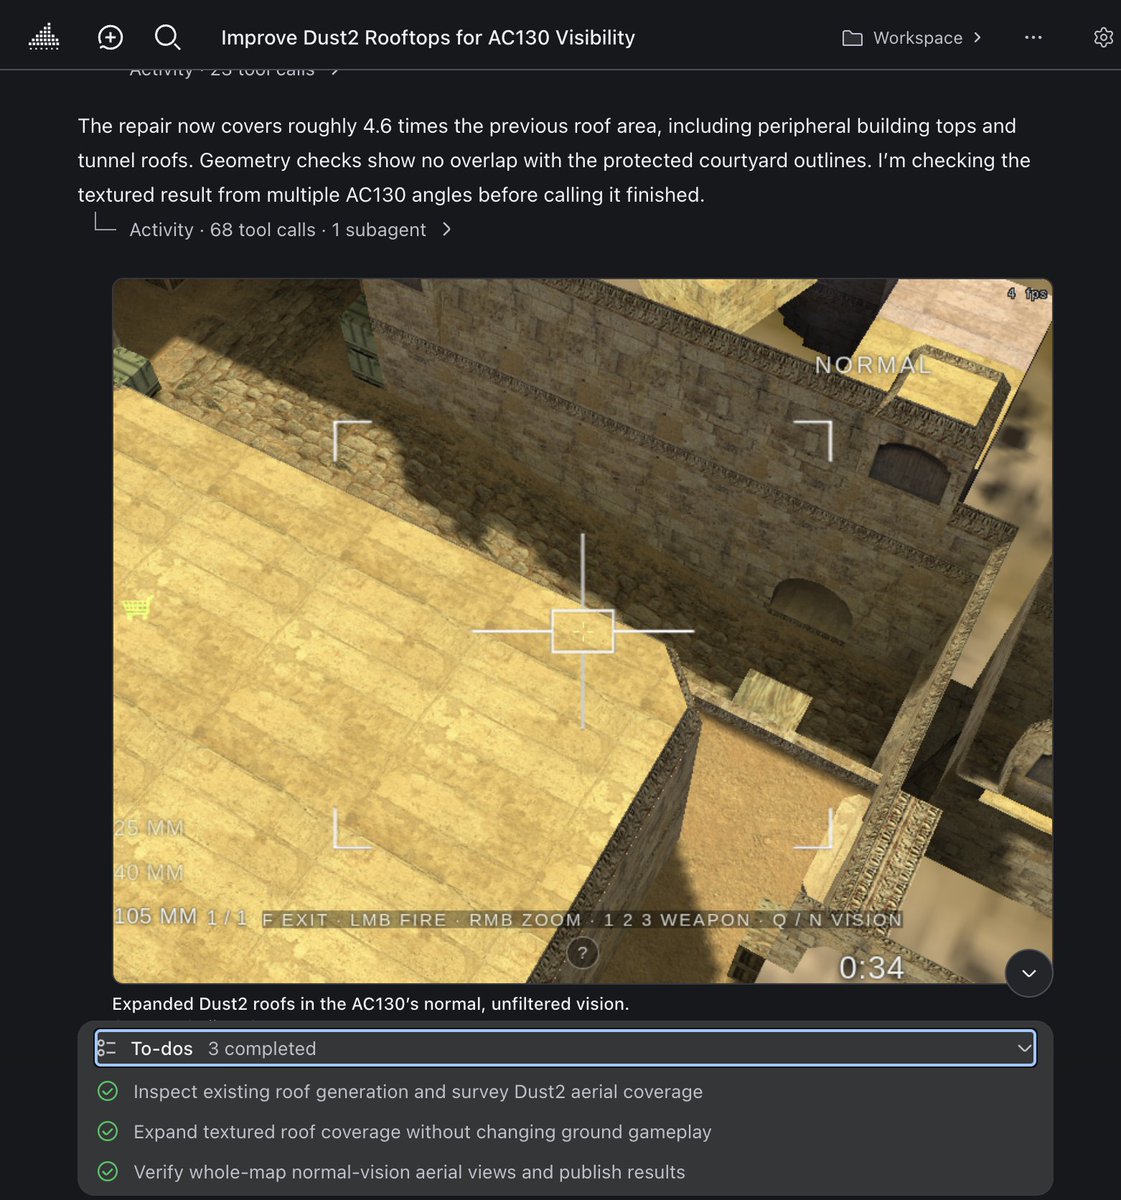
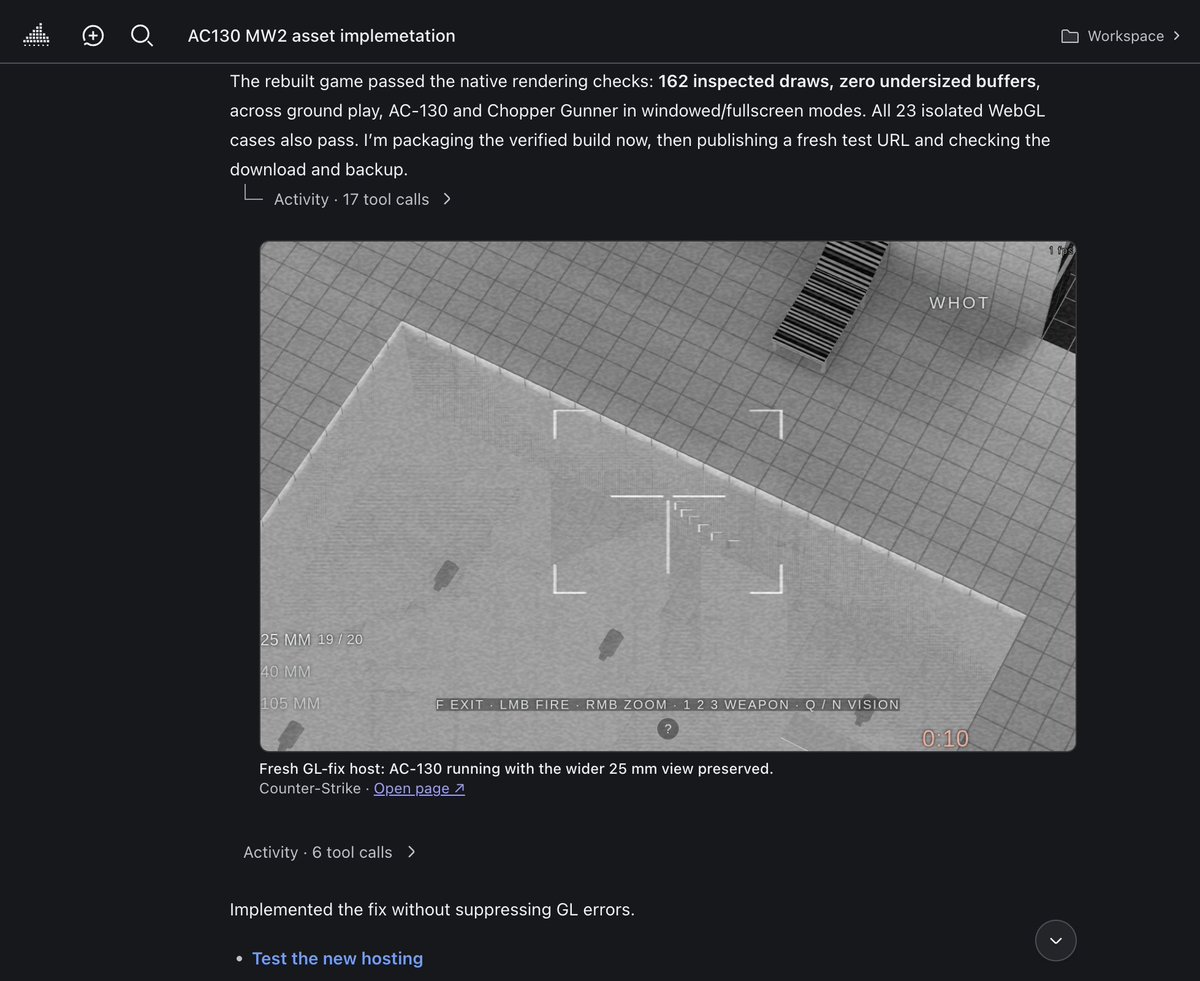
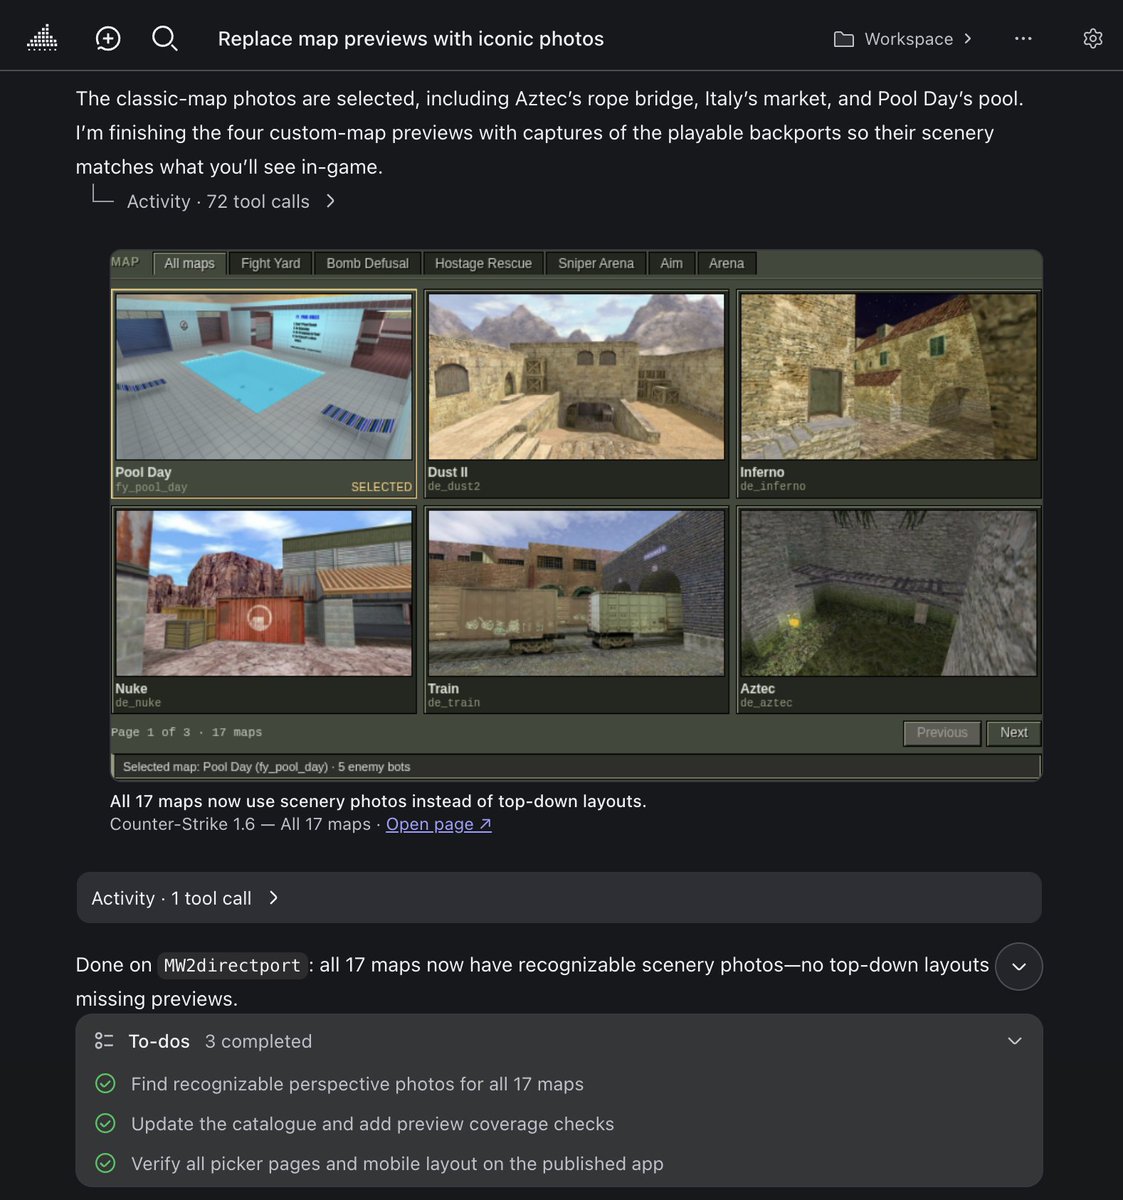
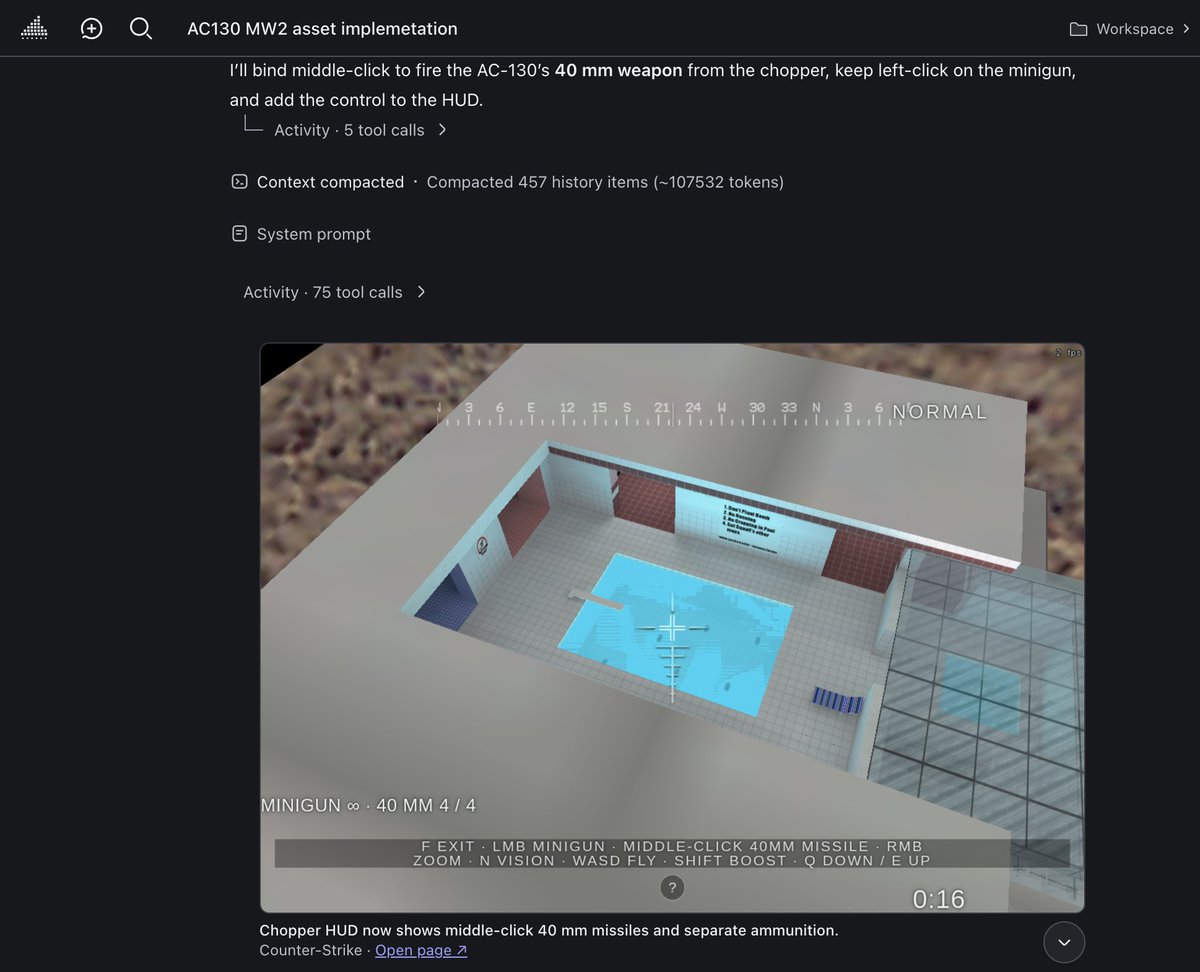
CS 1.6 x MW2 mash-up is live at https://t.co/FXyD8h6k9v
All game files are downloaded locally & run inside your browser with no internet connection required
This build benchmarked at >32% higher FPS than Xash3D thanks to heavy optimization that was designed by Astra (high) & implemented by a mix of Astra & DeepSeek subagents
Google Chrome is recommended for full screen mode as this bypasses hotkeys like Ctrl+W from closing the window
CS 1.6 × MW2 mash-up running entirely locally in Google Chrome
Built with 4.43B tokens of Astra & DeepSeek V4.1 Flash
Our harness Flipper routed all low-medium complexity tasks (64% of the total work) to DeepSeek - which cut the estimated API bill by >60% vs direct Astra usage
Flipper is currently in a closed beta with >20 people & will be open to the public soon
We are offering generous amounts of DeepSeek API credits & hosted Flipper sandbox instances for beta testers who have something interesting they want to build
If you are interested in testing, please reach out via DM with your experience & what you plan to build