HOLY CRAP, a new super tiny 1.6B param voice model just dropped that seems to.. outperform 11labs!? 😵💫
From Nari-labs, Dia is an Apache 2.0 voice model, that can generate laughs, sniffs and emotions, copy an existing voice and is effectively real time on larger GPUs:
📣 📣 📣 We just announced something awesome!
"#Gradle joins the #Scala Center advisory board"
https://t.co/dwltXGX64L
We continue to work towards the goal of making #Develocity the multi-build system platform of choice for developer productivity and observability.
The Scala Center is using Develocity for free to accelerate and troubleshoot #Scala3, #Scala2, with more projects to come! @scala_lang
The browser based parquet viewer https://t.co/crTTxwBceA is pretty sweet -- let's you explore the file format, including schema and layout, and data with SQL. Natch it is based on @ApacheDataFusio
Some engineering principles I live by:
✓ Make it work, make it right, make it fast
✓ Progressive disclosure of complexity
✓ Minimize the number of concepts & modes
✓ Most 'flukes' aren't… your tech just sucks
✓ Feedback must be given to users instantly
✓ Maximize user exposure hours
✓ Demo your software frequently to fresh eyes
✓ Sweat every word of product copy you render
✓ You're never done working on performance
✓ You're never done. Software ages like milk, not wine
✓ Visualizing traces of time is the best way to optimize it
✓ Ship frequently and strive to build in public
✓ Errors must have globally unique codes & hyperlinks
✓ Red is not enough to signal "error" (8% of men have red-green color blindness)
Did Open Science just beat @OpenAI? 🤯@kyutai_labs just released Moshi, a real-time native multimodal foundation model that can listen and speak, similar to what OpenAI demoed GPT-4o in May. 👀
Moshi:
> Expresses and understands emotions, e.g. speak with “french access”
> Listens and generates Audio/Speech
> Thinks as it speaks (textual thoughts)
> Supports 2 streams of audio to listen and speak at the same time
> Used Joint pre-training on mix of text and audio
> Used synthetic data text data from Helium a 7B LLM (Kyutai created)
> Is fine-tuned on 100k “oral-style” synthetic (conversations) converted with TTS
> Learned its voice from synthetic data generated by a separate TTS model
> Achieves a end-to-end latency of 200ms
> has a smaller variant that runs on a MacBook or consumer-size GPU. 🤯
> Uses watermarking to detect AI-generated audio (WIP)
> Will be released open source!!!
Demo: Coming later today (watch on @kyutai_labs )
Code: will be released
Models: will be released
Paper: will be released
okay so how about this
@duckdb's statistical functions have enough coverage that you can basically recreate facebook prophet in SQL
time series forecasting in SQL, here we come
Pixar doesn't use GPUs (much).
Their render farm compute is mostly CPUs with a ton of cores + memory, using AVX-512 and SSE 4.2 optimizations when appropriate to optimize render time.
Why?
GPU render compute doesn't speed things up as much as you might expect. Yes, in certain instances, you can get a 3-4x benefit, however you have to fit all the polys in GPU memory. Paging back out to system RAM brings you back down to CPU speeds.
Scenes can often contain > 150,000,000 polys. Only very recently have gpu memory sizes gotten big enough to be "worth it" over CPU rendering, and even then, it's often less flexible/tolerant of mixing older architectures in the cluster.
one of the more awesome things you can do with @duckdb
query geospatial data straight from github
this is from the excellent Natural Earth Data, and contains the boundaries for all countries in the world
How to identify ugly mass tourism places before you visit them?
In Europe, they usually have certain retail stores (e.g. Spar) or bars (Irish pubs).
But one thing defines them very precisely - quantity of Euronet ATMs.
These yellow/blue🟨🟦 ATMs are designed to scam tourists.
There are 312 of them in Mallorca🇪🇸
I downloaded all from Google Maps and made a heat map.
Knowing Mallorca well, seems to be accurate. Will try on more places.
Fun project made with @felt and @apify 🗺️⚙️
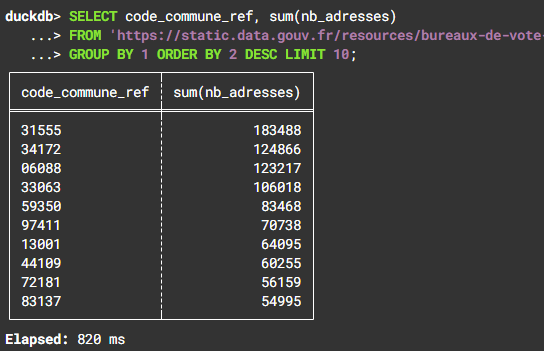
@InseeFr commence à diffuser au format Parquet !
Avec https://t.co/Z9ahRPdVsv, requête en direct sur le fichier de 470 mo des adresses géocodées des électeurs par bureau de vote (https://t.co/SPxzVIo8BC).
Toulouse en tête pour le nb d'adresses, résultat en 1 s, chapeau @duckdb 🙌
Future of AI assistants
A “jailbroken” Google Nest Mini running custom LLM’s & voice models by Justin Alvey
This demo is insane, a matter of time before these are shipped like this as standard.
Link in next tweet
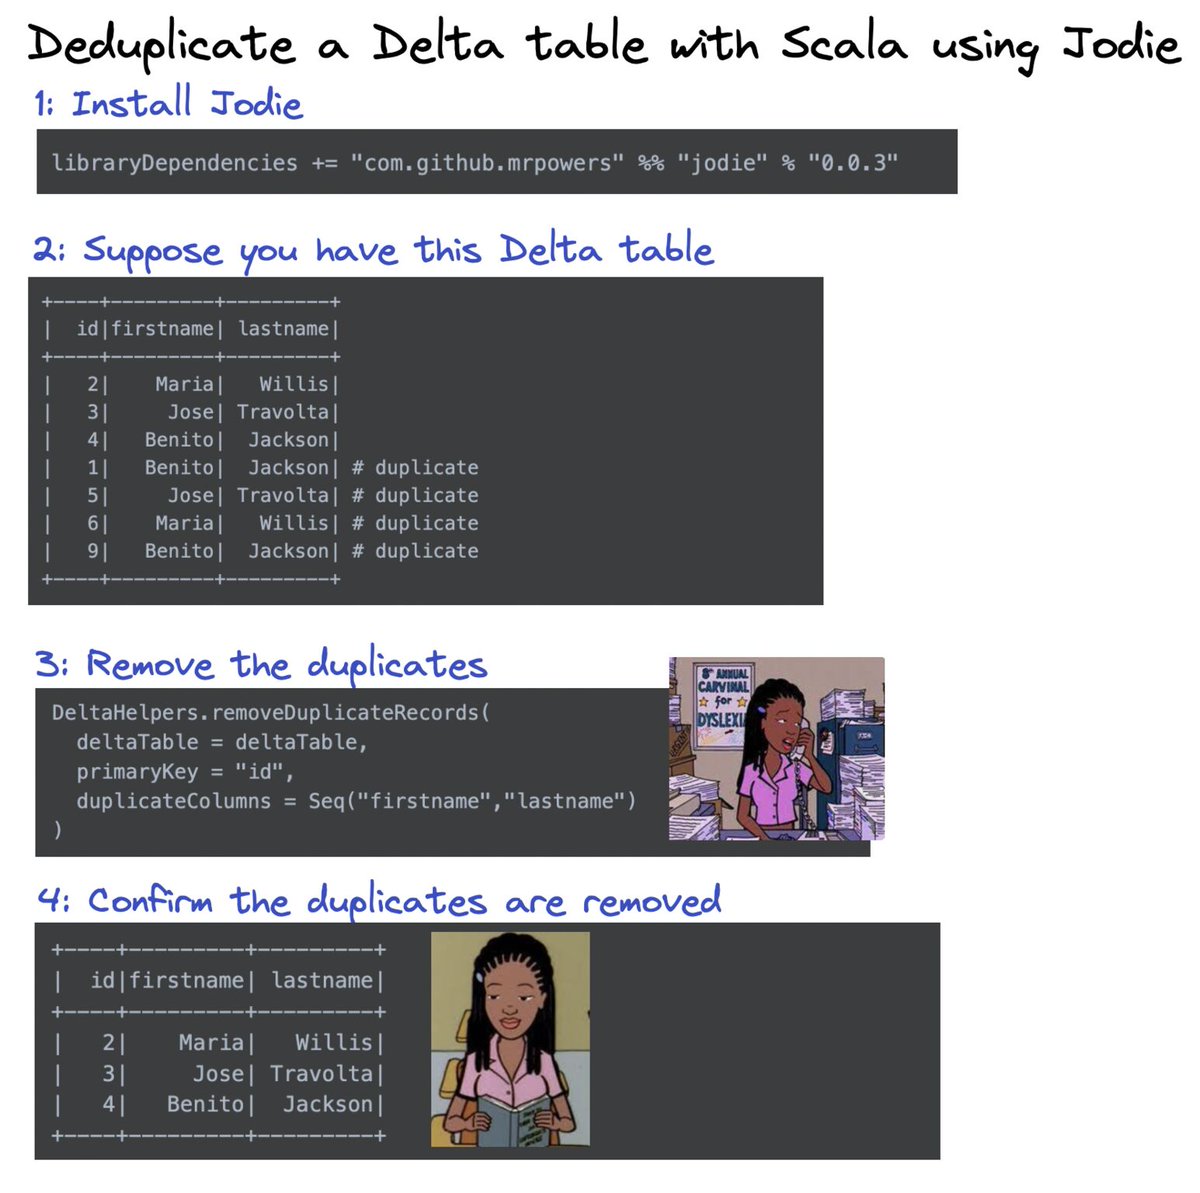
The Jodie library makes it easy to deduplicate a #deltalake table with #scala. It's implemented with MERGE under the hood, so the execution is efficient. Jodie on GitHub ➡️ https://t.co/Wwb345gqG1
Thanks for building this function, Brayan Jules Jacques!
cc @neapowers#oss