Most of us don't have access to multi-million dollar NVIDIA gpu sleds (if you do, hit me up).
But I wanted to learn how they work, so i build a 3d guide!
Unified GPU / CPU systems like this are what's powering all these mega-ai DCs. Incredible what educational tools you can build with llms.
Codex tip: once GPT-6.1 Sol is your main model, stop running Astra on every turn
put Astra on call as an architect agent
GPT-6.1 Sol keeps writing the code
Astra only gets spawned at three points:
→ before a plan: is this the right approach?
→ when the same error comes back: am I digging in the wrong place?
→ before "done": what did I miss?
Astra reviews. Sol ships
Jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the big models only see the ones that split
- the full tree
> GPT-6.1 Sol on high runs the main session
> explorer reads the code on Luna
> worker edits and runs tests on Sol
> researcher pulls the docs on Luna
> all three on medium
> Astra on call as the architect
> auto_review checks every approval
paste the tree and this prompt into Codex ↓
"Rebuild my Codex setup around this tree:
1. Check ~/.codex/agents and .codex/agents for agents that already fit explorer, worker and researcher.
> Draft new TOML files only for missing roles
> explorer and researcher on gpt-6-luna, worker on gpt-6.1-sol, all with model_reasoning_effort medium
> Add an architect agent on gpt-6-astra, model_reasoning_effort high, whose only job is reviewing plans, repeated errors and finished work
> Skip any that pin a different model and list them
2. In ~/.codex/config.toml set model to gpt-6.1-sol, model_reasoning_effort to high and approvals_reviewer to auto_review
3. Find anything that would override this (active profiles, flags in my shell aliases, agents.default_subagent_model). Report it, change nothing
4. Add one rule to AGENTS.md: spawn the architect before a large plan, when an error repeats, and before calling a long task done
Show me every change as a diff first. No edits until I say go."
↳ https://t.co/eyMF8gZKLE
As a Backend Engineer in the AI era, you must build these projects.
1.) High-Concurrency HTTP Server
Build: Go or Rust server handling 10k+ concurrent connections with graceful shutdown and backpressure.
Why: Concurrency architecture is the one thing AI cannot design for you.
2.) Multi-Tenant Hybrid Search Database
Build: Postgres with Row-Level Security + pgvector + BM25 hybrid ranking across isolated tenants.
Why: Structured data and semantic embeddings now share one query engine.
3.) Event-Sourced Order Pipeline
Build: Kafka or NATS pipeline with immutable events, dead-letter queues, exactly-once semantics.
Why: AI workloads are slow and async. The main thread must never block.
4.) Durable Onboarding Workflow
Build: 3-day Temporal workflow with checkpoints, retries and human approval steps.
Why: Background jobs are for emails. Durable execution is for multi-step agents.
5.) AI Gateway with Semantic Cache
Build: Proxy that caches similar prompts via embeddings, enforces token budgets and fails over to a cheaper model on 503s.
Why: The gateway protects your margins and your uptime from flaky, expensive LLM APIs.
6.) PII-Redacting Auth Middleware
Build: OAuth2/OIDC provider plus middleware that masks PII before logging and restricts AI agents to read-only DB roles.
Why: When agents can write to your database, a prompt injection is a data breach.
7.) Real-Time Streaming Dashboard
Build: SSE/WebSocket dashboard streaming LLM tokens and database updates simultaneously with backpressure.
Why: Time-To-First-Token and perceived latency are the new UX standards.
8.) Correlated Tracing Pipeline
Build: OpenTelemetry + Langfuse pipeline linking each HTTP request to the exact LLM prompt and DB query it triggered.
Why: You cannot debug a hallucination without replaying the exact context the model saw.
9.) Ephemeral Environment Provisioner
Build: Terraform or Pulumi scripts spinning up a complete isolated staging environment for every pull request.
Why: Manual deployments are a liability. Infrastructure must be version-controlled and reproducible.
10.) Queue-Based Autoscaler
Build: KEDA autoscaler spinning nodes up on Kafka queue depth and down when empty with spot-instance fallback.
Why: Backend engineers now own the cloud bill. Idle resources burn runway.
11.) Globally Distributed Rate Limiter
Build: Redis-backed distributed rate limiter that survives network partitions gracefully.
Why: Architecture must degrade gracefully not cascade into total outage.
12.) Chaos Engineering Suite
Build: Fault-injection harness (latency, replica kills, partitions) with SLO burn dashboards.
Why: Resiliency is proven under failure not in diagrams.
13.) Webhook Reconciliation Engine
Build: Idempotent event processor with exponential backoff, dead-letter queues and replay tooling.
Why: Real integrations fail constantly. Reconciliation is what makes them trustworthy.
14.) Cost-per-Request FinOps Dashboard
Build: Per-tenant, per-endpoint, per-LLM-call cost rollups with anomaly alerts.
Why: Visibility is control. You cannot optimize what you cannot attribute.
15.) Public Architecture Teardown
Build: 3 published deep-dives with system diagrams, ADRs and latency/cost benchmarks.
Why: Senior engineers are hired for their judgment not their syntax.
Systems that prove you can scale, secure & ship when agents touch your stack.
Most people watch tutorials. Builders ship systems.
Bookmark & Repost.
We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
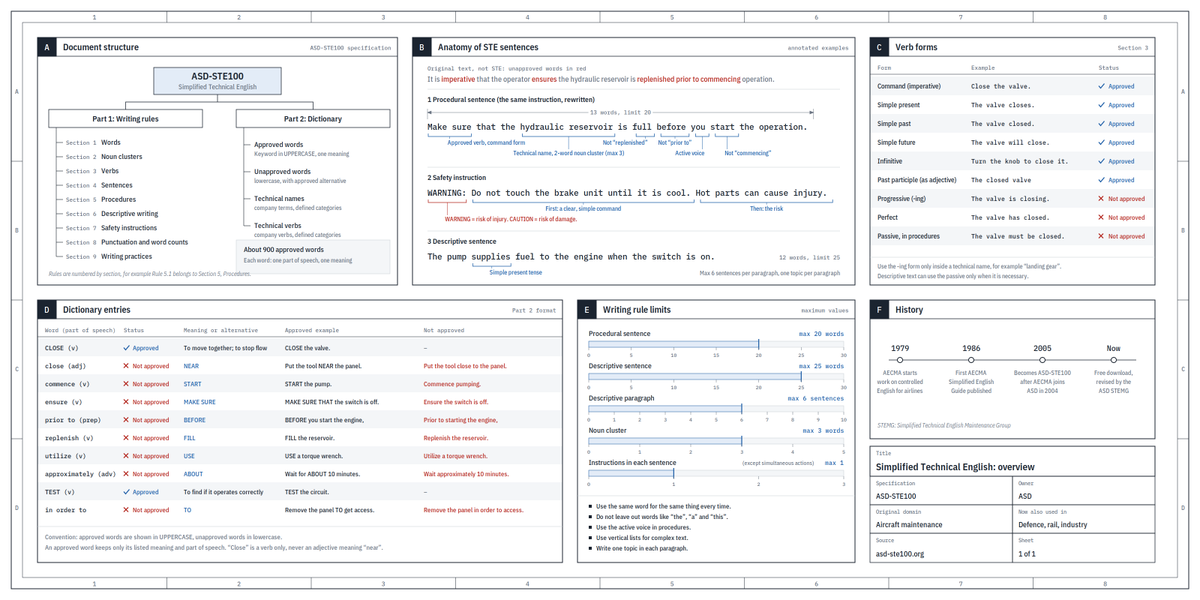
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.
California tech CEO Greg Lui was arrested in a raid at the headquarters of his company for allegedly smuggling more than $300 million in restricted AI chips into China. https://t.co/sB7dlN6PkX
On this day in 1942, Nazi Germany test fires the first V-2 rocket from the Peenemünde test facility. Reaching altitudes of 52 miles, the missiles are the first man-made projectiles to leave Earth's atmosphere and reach space.
Rick Ross’ attorney asked for his release to be expedited due to his celebrity status, only for Judge Mindy Glazer to tell Rick Ross, “I have no idea who you are.”
(Via @fox_sheldon)
@satnam6502 The unspoken rule is leetcode gives an indication if you will work until midnight and at weekends etc.
It’s just a polite way to filter out developers with families and active life outside the work etc.
@RabbiJeffx Yes. Starting in 2023, X partnered with Israeli firm AU10TIX for Premium ID verification. Users submitted government IDs and selfies, which were sent to AU10TIX for biometric matching and held up to 30 days.