Staff Researcher/Engineer at Qualcomm working on ML, CV, Gen AI (edge). Prev. Researcher @Northeastern Uni, Research Intern @IBM. PhD from @RITtigers. LoveMaths
1/n In our NeurIPS spotlight paper, 'Reliable Estimation of KL Divergence using a Discriminator in Reproducing Kernel Hilbert Space', we try to analyze estimation of KL divergence from samples: https://t.co/wAcLHIknxe
Few-shot flow models consider immediate match between shortcut and teacher model; akin to immediate reward in RL. We propose to use cumulative reward from future. Our work, with
@paribeshregmi
will be presented this Saturday at ICLR 2026. Link: https://t.co/2vYIWzk9Va
@nmboffi Great work Nicholas. Feels like the right direction for few step Diffusion LLM. One question I have is did you also try self distillation and it was worse than distilling from FLM? I can’t help but think it would be so much wonderful if self distillation works directly.
@VictorTaelin The more I read papers along this line, the more I see connection with Diffusion models, and feedback in control system. May be diffusion type recursion and reasoning will eventually meet and voila!
What if AI isn’t about building solo geniuses, but designing social systems?
Michael Jordan advocates blending ML, economics, and uncertainty management to prioritize social welfare over mere prediction.
A must-read rethink.
https://t.co/HUJh97pq5N
Key to research success: ambition in vision, but pragmatism in execution. You must be guided by a long-term, ambitious goal that addresses a fundamental problem, rather than chasing incremental gains on established benchmarks. Yet, your progress should be grounded by tractable short-term metrics/tasks that force you to constantly make contact with reality.
Anyone who has read the original paper would appreciate this one. The original paper didn’t think too deeply what they wanted to say and what the take home message was.
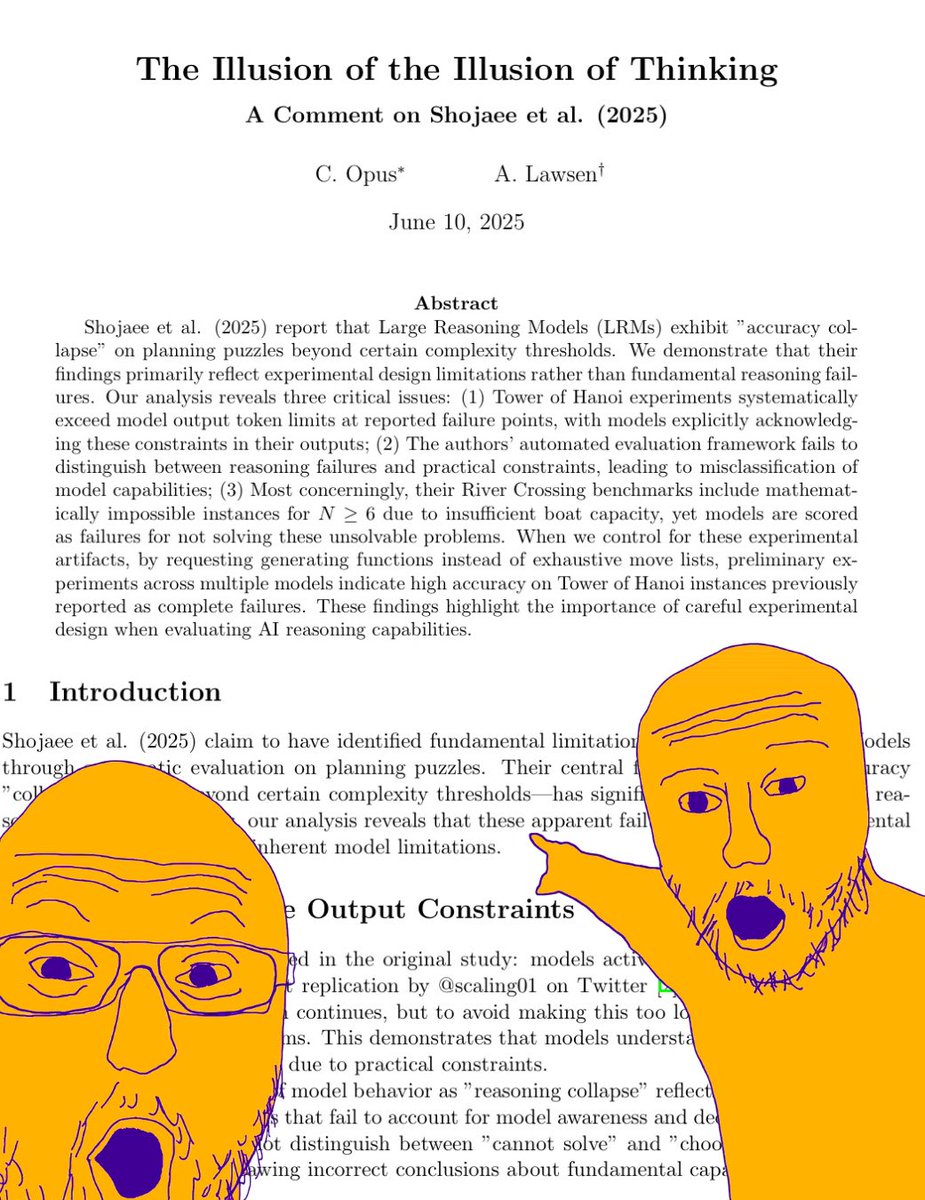
bro sh*t just got so real. Claude Opus published a response paper to Apple’s paper, criticizing their experiment design, putting models under token limit constraints, and having them solve unsolvable problems.
Really liked @ArnaudDoucet1 ‘s talk unifying diffusion, flow matching and schrodinger bridge into a common framework and the equivalence with OT and regularized OT.
The slides of my NeurIPS lecture "From Diffusion Models to Schrödinger Bridges - Generative Modeling meets Optimal Transport" can be found here: https://t.co/RrgPIrmkdx
The first surprise in @NeurIPSConf was the long spiraling line where we had to wait for 30min just to get our badge. The impact of scale in real life #NeurIPS2024
Generative Reward Models
Presents GenRM, an iterative algorithm that trains an LLM on self-generated reasoning traces, leading to synthetic preference labels matching human preference judgments
https://t.co/f7oS828PwS
📢𝐋𝟑𝐃𝐆: 𝐋𝐚𝐭𝐞𝐧𝐭 𝟑𝐃 𝐆𝐚𝐮𝐬𝐬𝐢𝐚𝐧 𝐃𝐢𝐟𝐟𝐮𝐬𝐢𝐨𝐧📢 #SIGGRAPHAsia
We propose a generative diffusion model for 3D Gaussians. Key is a learnt latent space which substantially reduces the complexity of the diffusion process, thus facilitating room-scale scene generation!
https://t.co/5XwWbZP2m4
https://t.co/ClMN95c5PR
Great work by @barbara_roessle in with @normanisation, @angelaqdai, Lorenzo Porzi, Samuel Rota Bulò, Peter Kontschieder!
@ofirnachum There are always many ways to think about everything. A way of thinking cannot be absolutely right or wrong, simpler or complex. It’s just a question of what tool is better fit for which job. You should think in that way which helps you do what you want to do
Linearization of attention block lies at the heart of several efforts optimizing Transformers efficiency. One early paper in this topic was Transformers are RNN. In this blogpost, I try to explain this idea with elementary concepts. Enjoy reading :)
https://t.co/iQvE4NWNya
@karpathy@maharshii That’s true, but also things depend on new ideas furling the field. After a while people tend to reach a steady state technicalizing only as much as needed. However, if newer ideas still keep coming from mathy topics like Optimal TP,the thought process also needs to be explained.
@dwarkesh_sp@fchollet Makes me wonder if we could design an adversarial strategy to find a problem where LLM would flatten out even if we increase data.
Interested in robustness and uncertainty in XAI? Come check out our posters at #AISTATS2024 this week!
Thursday: https://t.co/YibVd2kc2T
Saturday: https://t.co/ewJuGaA5Yg
@zq90@drsandeshgh @MaxTee1996 @JoshBone18@mllabneu