⚫️ Raises $25 million
⚫️ Spends $12 million on the domain
⚫️ Launches a site that looks like this
Dude is either a genius, or the worst steward of money I’ve ever seen.
OpenAI had a significant lead from summer 2022 through spring 2024 when Google and Anthropic caught up to GPT-4. 7ish quarters of dominance as a result of being the first to aggressively bet on the traditional scaling “law” for pre-training.
Being first to reasoning with o1 only led to a few months of advantage.
Deepseek, Google and xAI are at rough parity with OpenAI today. xAI arguably in the lead. Google and xAI will likely decisively surpass o3 soon as their base models are better. So urgent need for GPT-5 as the basis for a putative “o5”reasoning model.
Sam noted that OpenAI would have a narrower lead going forward and Satya essentially stated that a unique period where they had a tremendous lead in model capability was ending.
IMO, this is why Satya is opting out of funding $160b of pretraining for OpenAI per @theinformation. Instead he will make money by providing inference to OpenAI.
Google and Xai both have unique, valuable sources of data that will increasingly differentiate them from Deepseek, OpenAI and Anthropic. As does Meta if they catch up from a model capability perspective.
I have paraphrased @ericvishria many times and noted that frontier models without access to unique, valuable data are the fastest depreciating assets in history. Distillation only amplifies this.
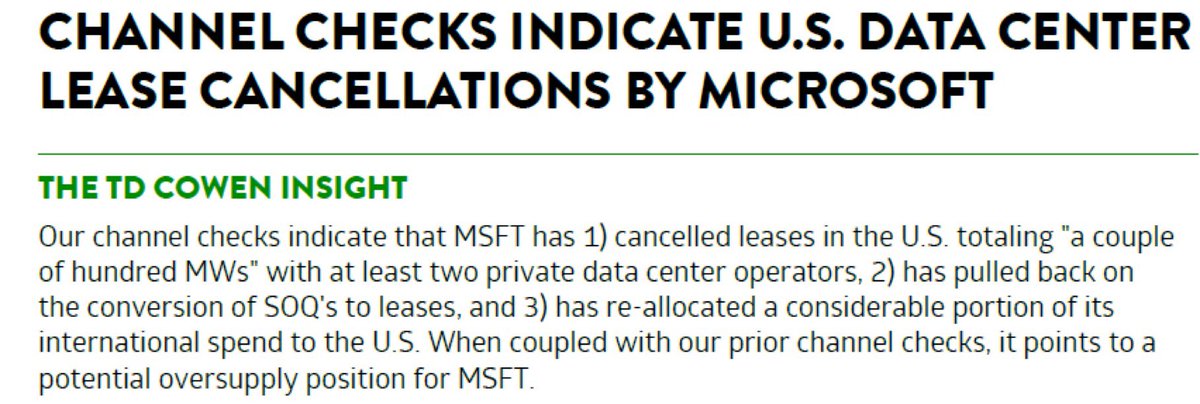
It seems like Satya shares this belief; hence opting out of the $160b of pre-training, the rumored datacenter cancellations and his statement on a recent podcast that there is a datacenter overbuild coming and better to lease than buy. Might be a sound decision for Microsoft from an economic perspective and at some point Microsoft might even use an open-source model to power CoPilot.
There may not be any ROI on future frontier models that do not have access to unique, valuable data like YouTube, X, TeslaVision, Instagram and Facebook. Zuckerberg’s strategy also seems much more sensible from this angle. Unique data might end up being the only basis for differentiation and ROI on pre-training multi-trillion or quadrillion parameter models.
If this is correct, only 2-3 companies will be pre-training frontier models and we will only need a few giant datacenters for the coherent clusters that are needed for pre-training. The rest of AI compute would be smaller datacenters that are geospatially optimized for low latency and/or cost-effective inference. Cost effective inference = cheaper, lower quality power (less premium for Nuclear), less of an imperative for liquid cooling in ST, etc. A very different world from one where 6-10 companies are pre-training frontier models.
Note that reasoning models are extremely compute intensive. Test-time compute means that compute is literally intelligence. So in this scenario there might be even more compute required than in the “pre-training” centric compute scenario that was the base case for the market throughout 2023-2024. But it would be a very different kind of compute as noted above. Instead of a 50/50 split between pre-training and inference it would be 5/95. Lots of Hondas, very few Ferraris. Infrastructure excellence would be paramount.
And all of this without even considering the implications of on-device inference and/or full quantization - the Deepseek R1 paper was not the most important paper to be published by a Chinese lab in the last year. IYKYK.
The economic returns to superintelligence are definitionally unknowable. I hope they are high, but a 140 IQ model running on device with access to unique data about the world might be enough for most use cases. ASI isn’t needed to book travel, etc.
I’ve done my best to be dispassionate, but I do have my own biases, both personal and economic, when it comes to xAI and OpenAI. If OpenAI is still one of the leaders in 5 years, then likely a function of first-mover advantage, ChatGPT becoming a verb and scale being even more of an advantage for reasoning models in that users generate and verify(ish) reasoning traces.
As ever, time will tell.