Hot takes:
Pelayanan publik harusnya emang gak libur weekend. Hanya libur saat hari libur nasional + cuti bersama.
Melayani cuma saat weekdays mah beban buat ekonomi. Ada orang yang kerja feenya harian kalau cuti buat ngurus gini artinya pelayanan publik lagi ngerem ekonomi.
Ketika hampir semua pemimpin berharap jadi rock star. Marah sama sidak yang viral jadi branding. Ketika gebrak-gebrak meja dianggap keren. Pun ketika ada rame-rame pendukungnya yang saling debat. Akhirnya orang yang kalem dan tenang seperti Pramono Anung malah jadi outstanding
Bryan Johnson just announced he'll become Immortal by 2039.
‣ Biological age of 18 (he's 48)
‣ Spent $2M/year reversing aging
‣ Heart health better than 99% of 18-year-olds
4 protocols you can steal (for free) to reverse aging, boost energy, & look 10 years younger 👇🧵
Make the most of your weekend.
Don't sleep on this.
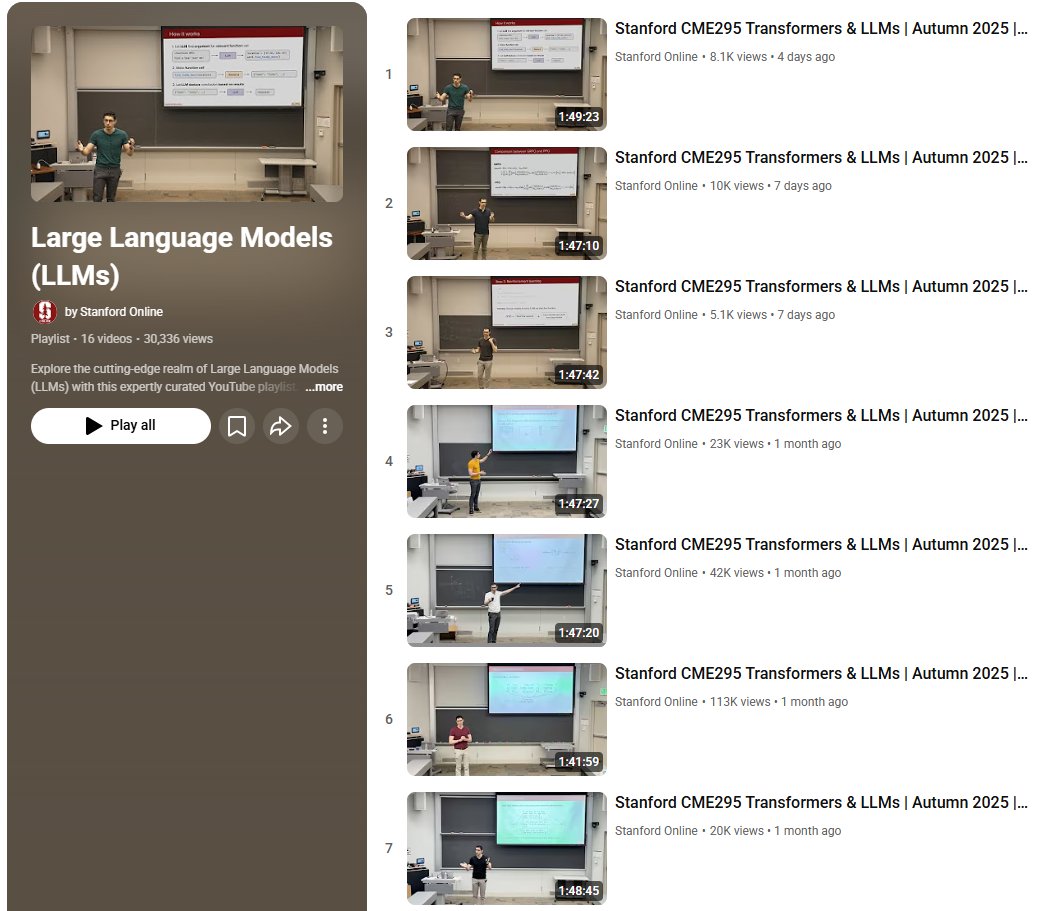
Stanford's Autumn 2025 Transformers & LLMs course. 7 lectures. Free.
While others scroll, you could understand how Flash Attention achieves 3x speedup, how LoRA cuts fine-tuning costs by 90%, and how MoE makes models efficient.
➕ What's covered:
➡️ Lecture 1: Transformer Fundamentals
→ Tokenization and word representation
→ Self-attention mechanism explained
→ Complete transformer architecture
→ Detailed implementation example
➡️ Lecture 2: Advanced Transformer Techniques
→ Position embeddings (RoPE, ALiBi, T5 bias)
→ Layer normalization and sparse attention
→ BERT deep dive and finetuning
→ Extensions of BERT
➡️ Lecture 3: LLMs & Inference Optimization
→ Mixture of Experts (MoE) explained
→ Decoding strategies (greedy, beam search, sampling)
→ Prompting and in-context learning
→ Chain-of-thought reasoning
→ Inference optimizations (KV cache, PagedAttention)
➡️ Lecture 4: LLM Training & Fine-tuning
→ Pretraining and scaling laws (Chinchilla law)
→ Training optimizations (ZeRO, model parallelism)
→ Flash Attention for 3x speedup
→ Quantization and mixed precision
→ Parameter-efficient finetuning (LoRA, QLoRA)
➡️ Lecture 5: LLM Tuning
→ Preference tuning
→ RLHF overview
→ Reward modeling
→ RL approaches (PPO and variants)
→ DPO
➡️ Lecture 6: LLM Reasoning
→ Reasoning models
→ RL for reasoning
→ GRPO
→ Scaling
➡️ Lecture 7: Agentic LLMs
→ Retrieval-augmented generation
→ Advanced RAG techniques
→ Function calling
→ Agents
→ ReAct framework
From Stanford Online:
Rigorous instruction. Latest techniques. Free access.
Perfect for:
→ ML engineers building with LLMs
→ AI engineers understanding transformers
→ Researchers working on language models
→ Anyone learning beyond API calls
This weekend: learn the techniques that separate good engineers from great ones.
(I will put the playlist in the comments.)
♻️ Repost to save someone $$$ and a lot of confusion.
✔️ Follow @techNmak for more AI/ML insights.