tbh give opus 5.5 or astra a simple “make this better” and it will fill in the promptgineering blanks for you
pair that with a specific + good harness - u can often get the same result (or better) had you included a very wordy prompt
*caveat, many lack access to good harnesses
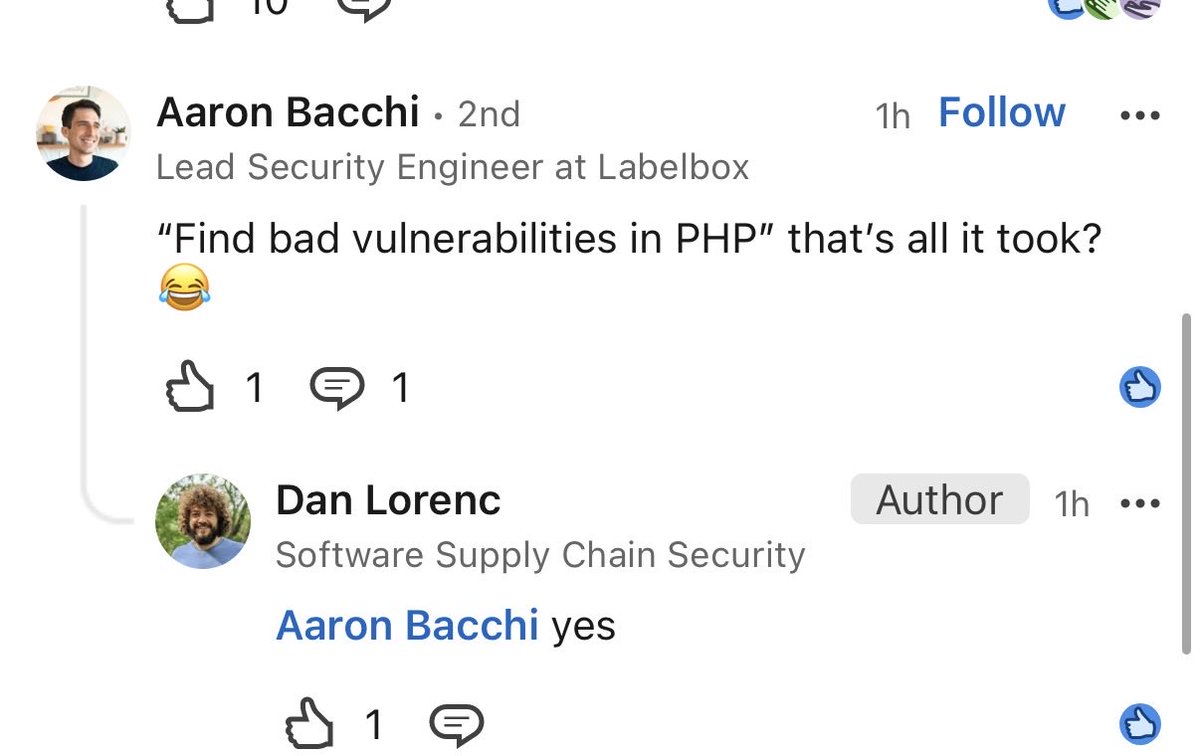
if every single open-source internet infrastructure team is not currently working with anthropic, openai, and/or the government to bolster cybersecurity, i’d be shocked.
php is only the beginning
terrifies me to think that we’re the simulated digital twin of someone’s brain, where our decisions are being used to train future ai models in a world where there’s no more original data
reminds me of the bit about training a fly’s brain to apply to jobs forever — and it would never know
anyways that’s enough doom-procrastinating for tonight
Should AI development stop, pause, or keep going?
I built Pace or Pause to map where prominent people stand, with the quotes, sources and caveats behind each position. Explore the map, then take the quiz to find your own stance.
https://t.co/5QnLIHT1rM
i wonder how many fundamental problems in neural network research could be solved with increased human in the loop pattern recognition.
bc it’s fascinating to me how quickly we leaned into the complicated quick fix versus the cleaner long term solution — in this case, reexamining patterns in neural grouping with a set of human eyes.
while AI succeeds at adding complication to solve problems, i think it’s uniquely human to break something down into its simplest parts + analyze from a new perspective, like @nickcammarata did
great great read
interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came away pessimistic, because neural networks appeared to fold into arbitrary tangled knots. years later, I started openai's first large-scale automated interpretability project, finding about 2% of neurons legible with the primitive tools we had
with modern agentic tools and a much closer look, the picture looks totally different. the vast majority in models up to trillions of parameters are legible, and their circuits beautiful. many famous examples of tangled neurons turned out to be misunderstood. The roadblocks I expected mostly aren't there. I now think ambitious interpretability will be solved by the time we need it most, and possibly quite soon, as automated scientists keep improving. it may be a bitter lesson for interpretability: the simple thing, at absurd scale, works
https://t.co/zHij5zwKGT
read my new substack on post-intelligence (a term im coining for a world after intelligence is commercialized // AGI)
thank you abundance for inspiring me to start writing again
https://t.co/oNQVOWiBo5