I'm happy to share that our book on Deep Learning with Transformers will be released on May 25th, 2022. I'm grateful for my co-authors (@theudaykamath and @klogram). I hope the book will be helpful to the AI community and hope to continue writing. https://t.co/VihIhh6A3r
Algorithms rarely constitute any kind of competitive advantage, that's why companies like Google, FB give them away for free. (TensorFlow, PyTorch)
The real advantage is clean, modeled data. Algorithms without data are useless. Data without algorithms still has value.
@HyperboIeva I always think about talks content in terms of entropy, if u understand everything, your knowledge gain isn’t much. Going to conferences with the mindset of getting exposed to new uncomfortable ideas then going home and reading up and coming with further ideas.
New state-of-the-art for language modeling. The new paper "Better Language Models and their Implications" from @OpenAI achieves SoTA performance on several benchmarks. Example progress with historical values below: https://t.co/zXeqMPXctS
I used BERT as a pretrained model to build a Wikipedia natural language search engine (https://t.co/4Ji1iszCyr). A @fastdotai classmate of mine just wrote a great intro on how to use pretrained BERT models for NLP tasks: https://t.co/tg3yuzSaVP , so thought I'd share.
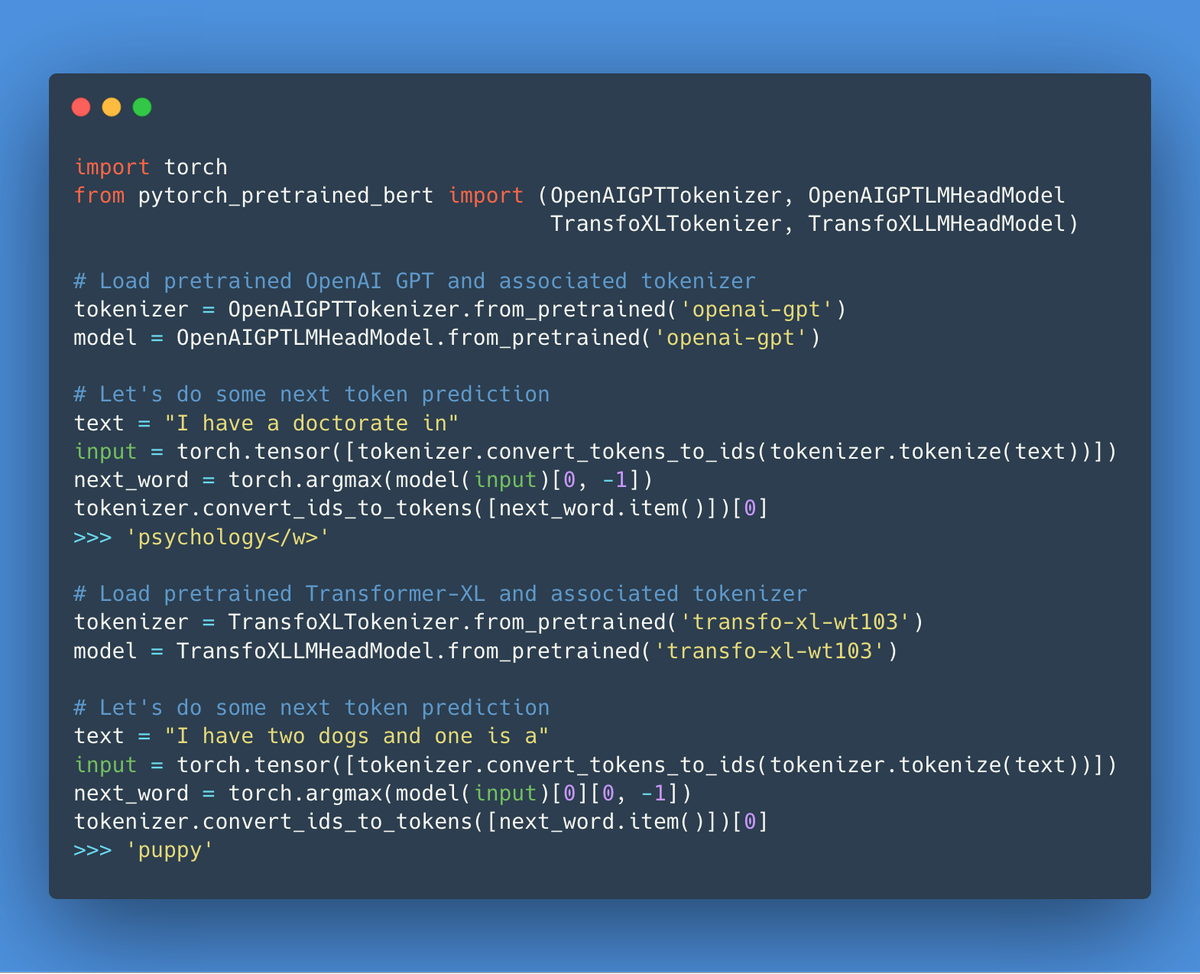
PT-BERT 0.5 out💥
Pretty big release w. not 1 but TWO new pretrained models:
-classic: OpenAI's GPT
-brand-new: Transformer-XL by Google/CMU
As always both should be super easy to use
So...BERT now stands for Big-&-Extending-Repository-of-Transformers😅
Happy Transfer Learning!