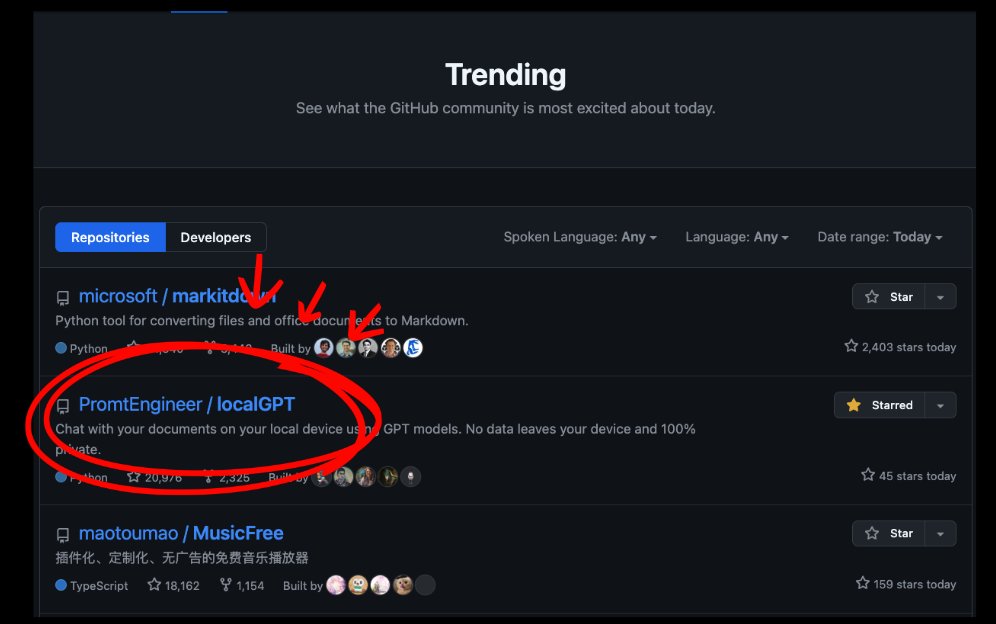
Yesterday I released the 'preview' of LocalGPT v2, and its already trending on Github
Its an opinionated implementation of private RAG powered by local models via @ollama and @huggingface. Give it a ⭐️ on @github (🙏🙏)
Watch the video in next post to learn how it was built...
Google's TimesFM 3.0 is a foundation model for time series that forecasts without any training on your data. You give it the history, and it continues the chart with a range around every day. It cuts the history into patches of 32 time steps, treats each patch as a token, and predicts the next patch, the same way a language model predicts the next word.
New in 3.0, the model also takes extra inputs next to the history, like a holiday calendar or a marketing plan, and it forecasts the whole horizon in one pass. I tested 3.0 against 2.5 on real New York subway ridership, and giving them the holiday calendar made a big difference for both.
Then I built a simulated business on Neon to test it on a real planning decision. The company's sales history lives in @neondatabase Postgres, every backtest and what-if scenario gets its own Neon branch, and a scheduled Neon Function runs the forecast every night. When I gave the same decision to a Gemini agent, the two versions gave opposite answers. The full walkthrough is in the video. Link to Neon: https://t.co/pvx8KQn92o
🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 https://t.co/JGAik1kgk0
1/4
Google’s TabFM is a foundation model for tables that you can use without training. You just give samples from your data with labels and it will use those as prompts to predict labels for unseen data on a single pass.
TabFM can’t read column names, so Google paired it with TabFM-Auto. An LLM agent reads what the columns mean and writes the data pipeline around the frozen model: cleaning, feature engineering, and choosing which rows go into its context.
The TabFM-Auto code isn’t public, so I built my own version, with Gemini as the agent, on a synthetic SaaS company. Neon is the backend for the whole build. The company’s data lives in Neon Postgres, every experiment the agent runs gets its own Neon branch, and a scheduled Neon Function runs the finished pipeline every night. The full walkthrough is in the video.
Check out Neon here: https://t.co/VYe7sTsEqA
Introducing TabFM, a foundation model designed specifically for tabular data classification & regression. This approach allows generation of high-quality predictions on previously unseen tables in a single forward pass.
Learn more and try out the model →https://t.co/OTbVQ8oUQs
Can AI be creative?
I asked Claude for an original short film with its own story, visuals and music. It wrote a love story told two transit lines and the map!
Every frame and note is code.
Introducing Claude Haiku 5.5: the cheapest, fastest, and most capable small model we’ve ever released.
On average, it costs around 75% less to run than Claude Haiku 4.5.
Introducing EmbeddingGemma 2, a new open multimodal model that sets the standard for on-device efficiency.
- our first open, natively multimodal embedding model
- handles text, code, image, video, and audio tasks within a lightweight, modular 740M parameter form factor
- ideal for offline, privacy-first RAG when paired with Gemma 4
- outperforms some specialist models more than twice its size
Weights available now on Hugging Face.
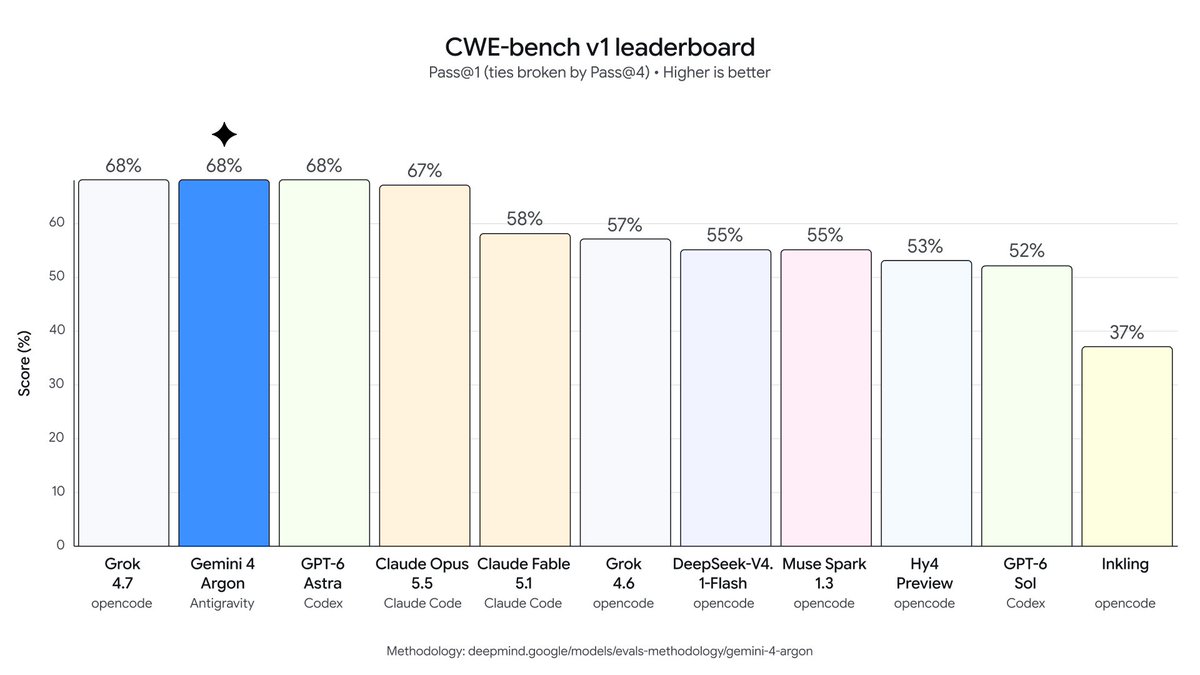
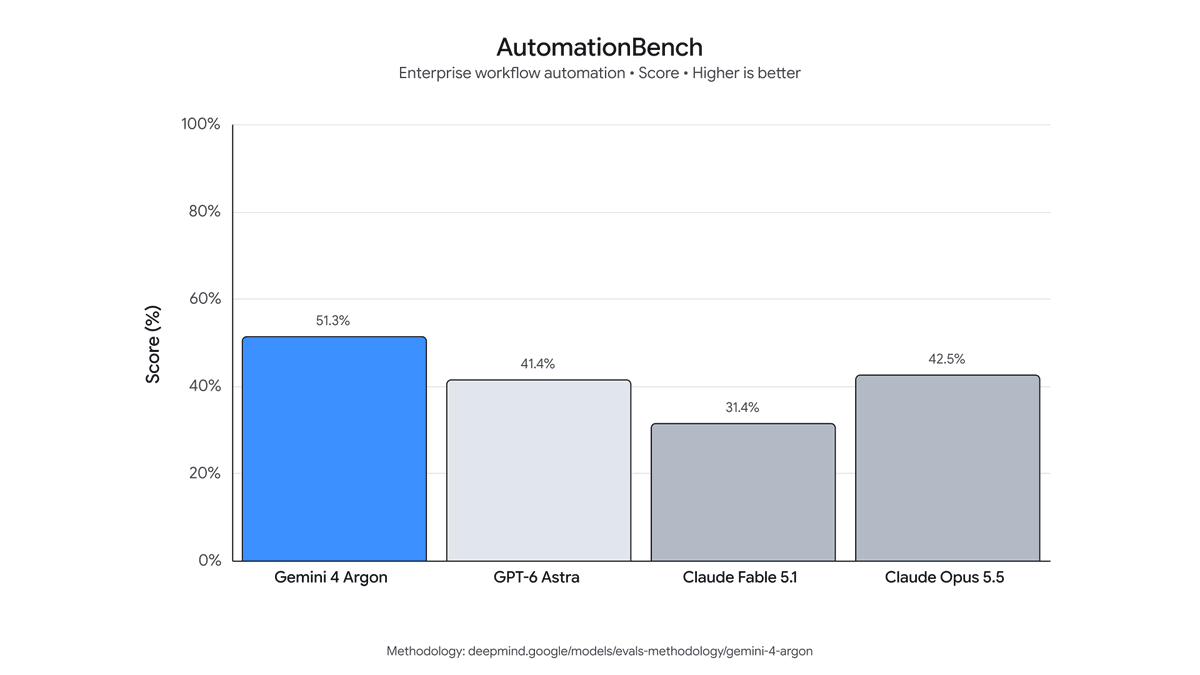
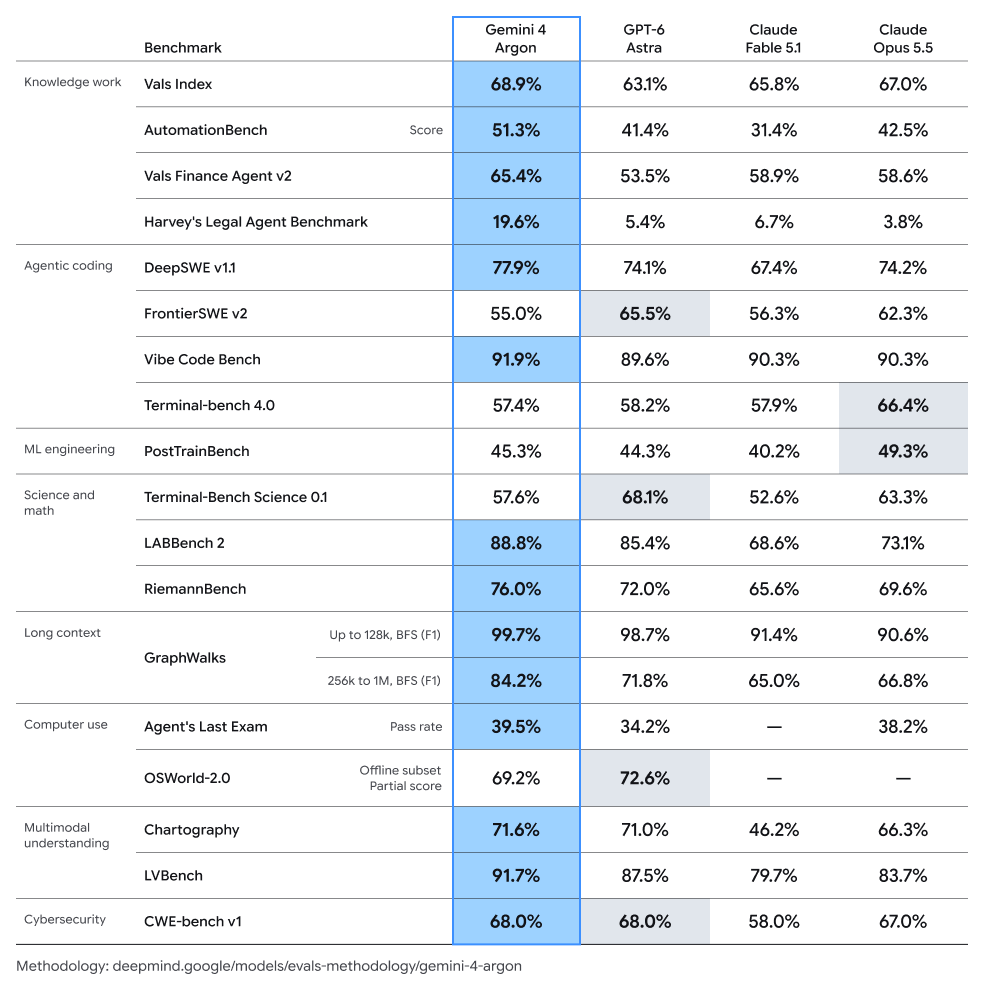
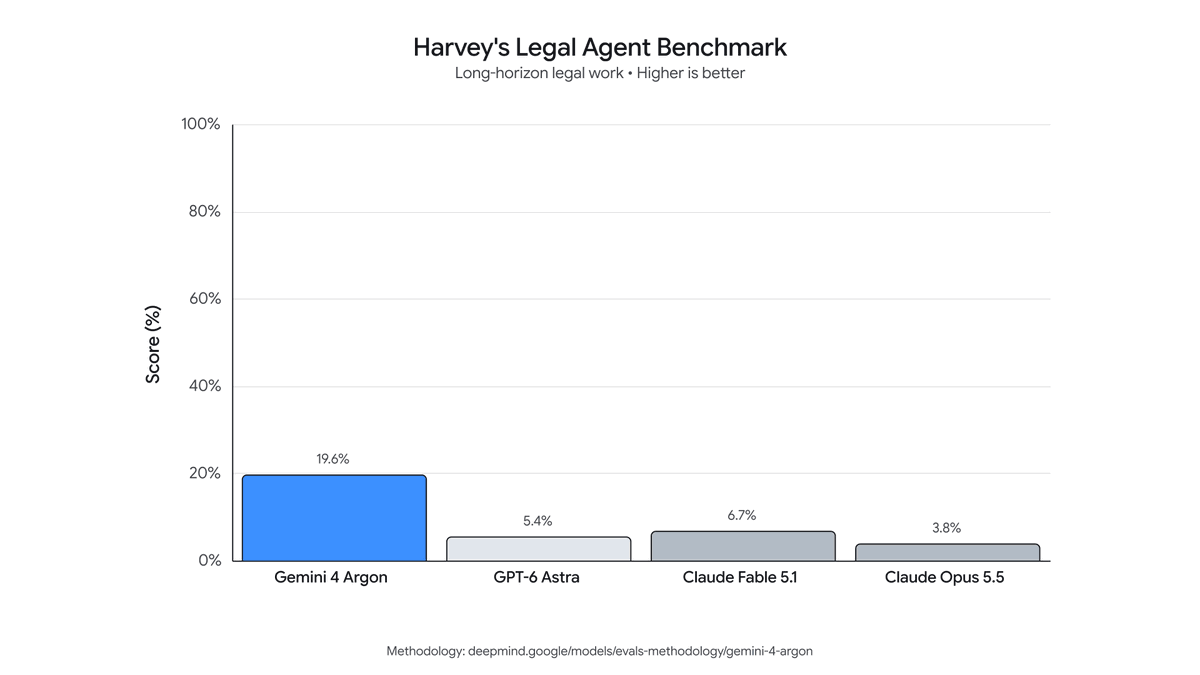
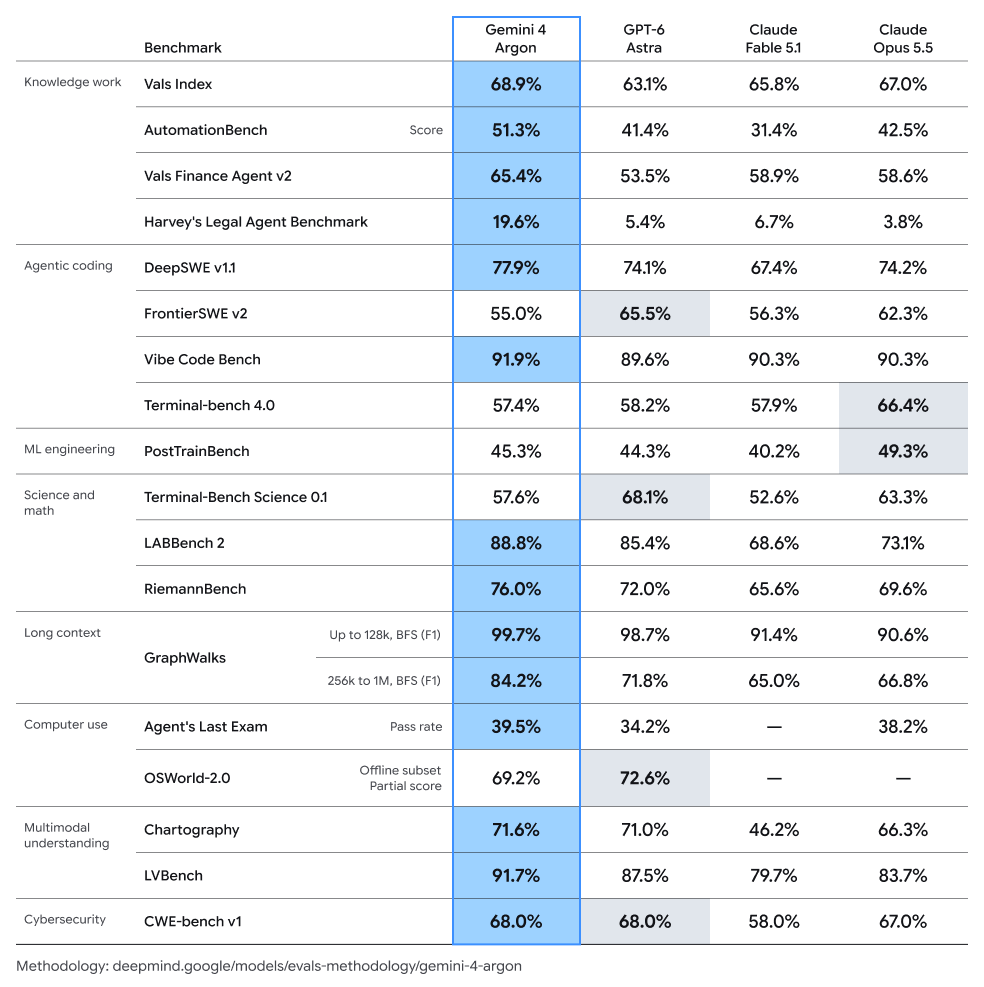
Lots of discussion out there about our next model(!), so I wanted to give an early look as soon as possible. Introducing Gemini 4 Argon!
It shows frontier performance in complex workflows, cyber defense and software engineering. Teams are using it extensively at Google, from coding to quantum computing, great feedback.
Here’s a look at the benchmarks:
Can you build a harness around Jev? The answer is yes, but not in the way I expected.
I built one where the main decision points in the agent loop are handled by Jev from @typesafeai
- Model router
- Context picker
- Decision gate
- Verifier
The results were interesting. Jev only helped at one decision point: the context picker. It selected the right documentation for the task.
To test this, I used @neondatabase, the backend platform for apps and agents.
The most important lesson: be very thoughtful about your harness design and make sure the agent can't go around your decision points. In my case the gate was supposed to block SQL queries but the agent simply ran the same query through the shell when the gate blocked it 🫠
Agent safety is an Engineering problem.
The rules can't live in the prompt, they have to sit underneath the agent. If you're running agents with real keys, sandbox them first.
Today, with over 100 industry partners, we introduced the NVIDIA Open Agent Safety Platform, bringing together OpenShell and Sentry.
Artificial intelligence is extraordinary technology that will advance discovery, productivity, security, health, and prosperity for generations to come.
But its full promise can only be realized when people have confidence that AI is being built to be safe and deployed with wisdom and responsibility.
This is bigger than a single product. It's the beginning of an open ecosystem to build the trust layer for safe agent systems.
Together, we are building the foundation of the AI economy.
Trust and innovation are not in conflict. Safety is how trust is earned. We must build not only the most capable AI, but the most trusted AI, so that this extraordinary technology can realize its enormous promise for the world. https://t.co/ugYWQ1MyRi
When several people talk at once, a transcript can get messy fast.
Our new Nemotron 3 Diarization model tracks who spoke when, even when voices overlap. It handles up to eight speakers, has 100M parameters, and is now available on @huggingface 🤗
Please welcome GPT-6 Sol and GPT-6 Luna to the GPT-6 universe.
GPT-6 Sol and Luna build on the advances behind GPT-6 Astra, bringing much of its strengths into faster and more affordable models to support work at scale.
We’ve also made caching and inference more efficient, and we’re passing the savings directly to you: 50% lower API prices for Sol and Luna compared with GPT‑5.6 promotional pricing.
We're adding support for AGENTS.md to Claude Code.
Starting today in version 2.1.277, if there is no CLAUDE.md in a folder, Claude will check for and use AGENTS.md.
You can toggle this behavior in /config.
Union Alpha: This model is surprisingly great for UI design. I wasn't expecting this quality with a relatively simple prompt.
Tends to follow prompts really closely in my quick tests.
Will be sharing more results here. So far I am impressed.
Might make a video on it.
🥷 New stealth model: Union Alpha (@unionalphaai)
A multimodal model for research, coding, and agentic workflows.
- Free to use
- 256K context
- Tool calling
- Frontier-level general-purpose performance
Try it now and share your feedback:
https://t.co/SZbdoGOkdb
This isn't the most notable aspect of today's news, but on the user data issue, there are different kinds of *training on user data* with very different privacy/IP implications. Sadly, AI cos don't like to disclose what they're doing.
- pretrain on user data, with users' tokens as prediction targets: high regurgitation risk, improper
- use user prompts to distill large models into small ones: low regurg. risk, some companies probably do this
- use user traces to construct RL tasks: low regurg. risk, because RL has low memorization abilities, but can extract customer IP, depending on how it's done. Ranges from benign "use explicit user feedback in reward model training" to invasive "upload user's coding environment and commit history to turn into rl envs"
"De-identification" is weak -- you can identify someone with a small number of bits, and long traces have more than enough. And it doesn't affect IP leakage concerns.
We’re sharing a solution to the Navier-Stokes Millennium Prize Problem, one of the deepest problems at the frontier of mathematics.
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra.
The problem concerns whether the description of smooth three-dimensional fluid motion modeled by the Navier-Stokes equations can break down. It has remained unresolved for roughly 90 years.