🎉 Introducing 𝙾𝚙𝚎𝚗𝙼𝚞𝚜𝚎
An open source, self-hostable personal assistant that works with any agent harness.
Includes:
- Computer use: browser, terminal & files
- Connectors for your personal apps
- Ideas, goals & progress tracking
- Built for Mobile and Web
Repo → https://t.co/wfVccqlpru
Powered by @CopilotKit and AG-UI.
Clone this template and customize it however you want.
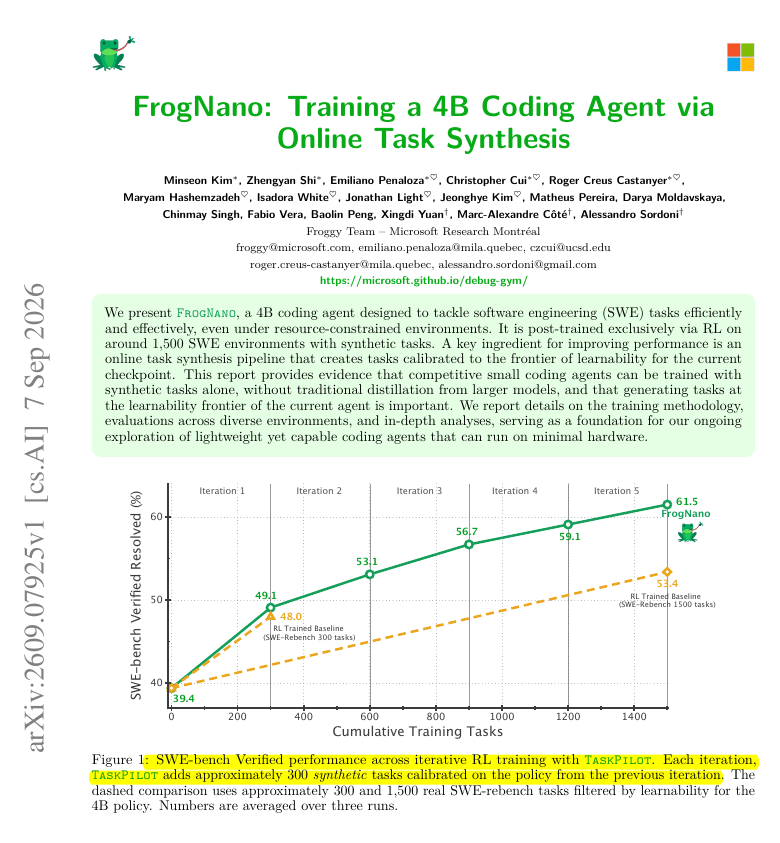
A 4B coding agent reached 61.5% on SWE-bench Verified without frontier-model distillation by combining a simpler tool interface with synthetic tasks that keep adapting to what the model can currently learn.
FrogNano starts from Qwen3.5-4B and is trained with RL on about 1,500 synthetic software-engineering tasks.
The important part is how those tasks are chosen.
As the model improves, the system generates fresh problems that are challenging but still learnable, so the curriculum improves with the agent.
The interface matters just as much.
Switching to a simpler 5-tool setup moved the base model from 8.3% to 37.2% on SWE-bench Verified.
After 5 rounds, FrogNano reached 61.5%.
– arxiv. org/abs/2609.07925
Title: "FrogNano: Training a 4B Coding Agent via Online Task Synthesis"
They were building in stealth for 2 years, I was building in stealth for 2 hours…
Happy to open source Qwen-2.5-1B-RLCD, 5x faster on-device inference for JSON workloads that need to be type-safe.
⚡️Demo below on a M4 MacBook⚡️
every LLM has the ability to efficiently batch inference every key of a JSON at the same time and generate probabilities from a set of possible categories. No new training required, but it’s easy to optimize if you need!
On hugging face now!
tested Jev as a real-time robotics policy in MuJoCo
it struggled at first, so i split each update into two calls: decide what to do next, then decide how to move the arm and gripper
Jev doesn’t accept images, it gets simplified geometry and contacts as text here
We release Needle 3: A Sliceable 8-29MB automation foundation model that can match DeepSeek V4 Flash.
One set of weights, every depth from 2 to 20 layers a model of its own, 25-121M parameters at CQ2-bit, built on our Simple Attention Networks and running locally at up to 4k tokens/sec decode speed on a Raspberry Pi 5.
Needle does not chat. Every turn is a function call: give it the tools your app exposes and it picks the right ones and fills every argument from what the user said, or hand it a schema and it returns a typed record. Ask for something no tool covers and you get an empty list, not a guess.
That trade is lets 121M parameters trained on 360B tokens of structured data beat models 10x their size on mobile tool calls and match 2-3x bigger models on structured JSON extraction.
It runs on mobiles, wearables, smart home devices, small robots and microcontrollers, with prebuilt engines for macOS, Linux, Windows, Android, iOS, watchOS, tvOS, the browser and WASI hosts. Try it in your browser: https://t.co/dLK2tILvG2
Latest recipe for the Qwen3.8-27B
Dynamic DFlash2
n=10 for c1-c2
n=8 for c3-c4
n=7 for c5-c8
n=6 for c9-c10
… and so on since DFlash acceptance is inversely correlated to concurrency
You get the best of whatever concurrency you are choosing to use.
https://t.co/04O2wj6hSj
Superintelligence should learn from experience through RL.
Introducing FlashREINFORCE:
Critic-Free, Single-Rollout, Asynchronous RL for Agentic Language Models
Reinforcement Learning Should Do REINFORCE!
https://t.co/Wz5S57F6B7
🚀 Sol-H3 on DGX Spark: 768p in Under a Minute 🤩
Monday: 8×B300, 5s 768p in 1.65s — faster than playback.
Today: the same stack on one desktop Spark — about 56s hot E2E.
Five seconds of 1344×768 video at 24 FPS with stereo audio, on a single NVIDIA DGX Spark (GB10).
Two-stage, not the datacenter profile:
384p H3 draft → latent ×2 → H3-to-LTX VAE adapter → 768p LTX refine → VAE decode
No decode/re-encode between stages. Stage 2 is conditioned on the draft latent, so Gemma stays off the box. Quantized weights stay resident; sparse attention cuts the rest.
Stage 1 takes any MiniMax-H3 few-step LoRA. Timing is hot E2E (encode → both stages → video/audio VAE); cold start and MP4 mux are separate. Apache 2.0.
Server was realtime. Edge is one box, under a minute.
🔗 https://t.co/rfo0EVkJsI
Amazing team effort—full credits in the blog.
@haopengl33@lawrence_cjs@yitongli165665@shanasaimoe ,Jingyu Xin, @HaochengXiUCB@songhan_mit