@Nayberryk@tszzl@tszzl
https://t.co/NDIzPOTifu
if you want access to a small subset of the benchmark for internal testing, my DMs are open.
would be great to be proven wrong / shown that the US has some hands too.
@sudooapt@uzairakrum this is based on people misinterpreting my benchmark results, I got early access for codename hawk and duck:
https://t.co/miM4G6Hf2n
@spnichol people are extrapolating way too much from my benchmark results which is what started this saying:
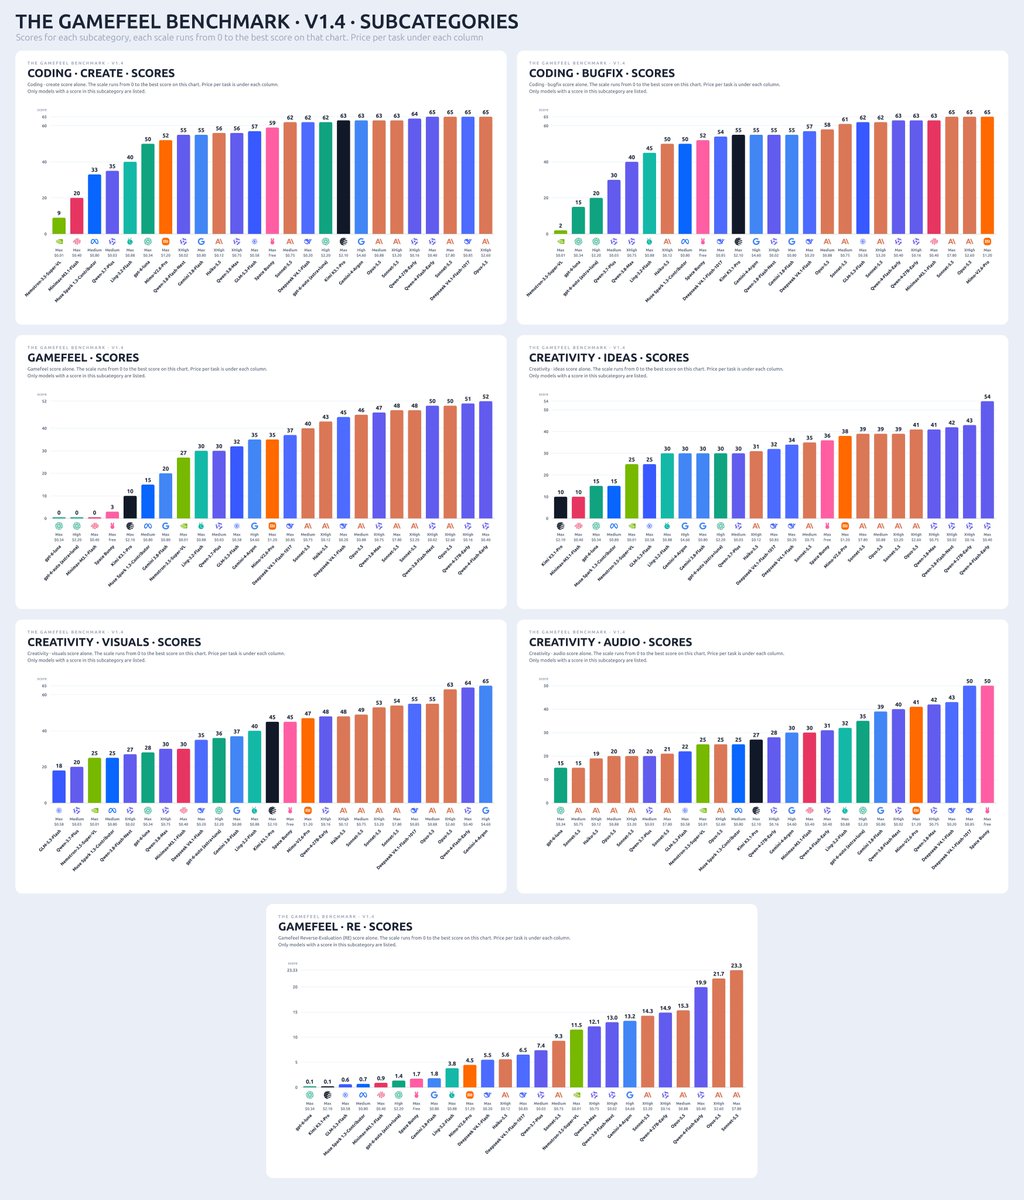
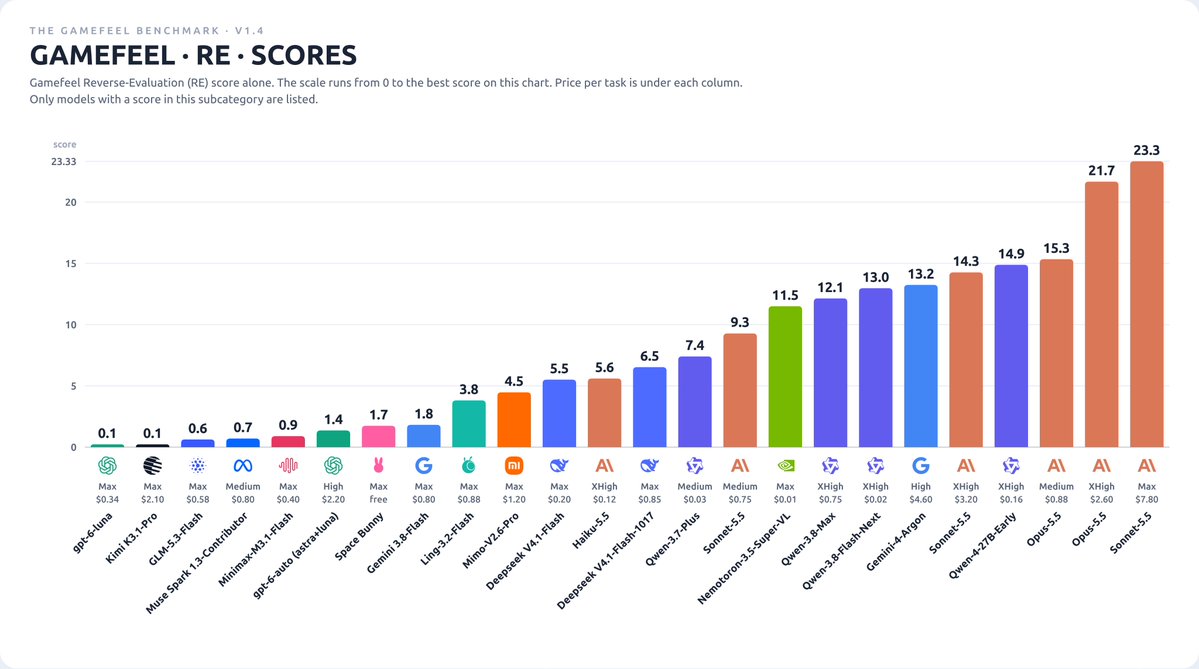
GameFeel Bench measured Game balancing abilities not general capabilities, and that's where qw4-27b was *almost* on level with opus-5.5
more details here :
https://t.co/1WQdBHagI2
@MarcoGiacobbe15@mfranz_on I did not make that assumption, I was given concrete confirmation about the api endpoint I was using to be a 27b-class model.
A better description of what the benchmark measures :
https://t.co/1WQdBH9ISu
@Chaos2Cured One thing that kept the reputation of this benchmark low today:
People keep misinterpreting and misquoting these results as measuring general capabilities, when its a benchmark set specially built around game balancing and gamedev related creative thinking.
'QoDuck' (qwen-4-27b early checkpoint) added after reaching out to alibaba and being granted access.
only beaten by Opus 5.5-Max and Xhigh on GameFeel bench, SoTA for open source by far!
Yes, all of this from a 27b model, I am shocked at these results.
@spnichol people are extrapolating way too much from my benchmark results which is what started this saying:
GameFeel Bench measured Game balancing abilities not general capabilities, and that's where qw4-27b was *almost* on level with opus-5.5
more details here :
https://t.co/1WQdBHagI2
@vincentack122 this about game balancing and game development check out the details and methodology used for this benchmark here:
https://t.co/NDIzPOTQ52
@BranchGhost@MichaelLee009@grok Hi! its my benchmark and it is NOT meant to represent general capabilities, it is measuring game balancing and game feel capabilities
Read more about what the benchmark actually measures here:
https://t.co/NDIzPOTQ52
@sebuzdugan only Qwen-4-27b needed correcting!
and yes this has caused some people to circulate incorrect results for Qwen-4-27b
as the lower audio score result brought down the average on overall from 47 to 44.6
@selzer25 More information about the benchmark here:
https://t.co/1WQdBH9ISu
the benchmark mainly tests game balancing 'feel', not necessarily correlated with general capabilities.