@antirez Mi ricordo che in un video avevi accennato al bot Telegram che usi per le notifiche delle sessioni Codex.
Ho creato Codex Relay: app iOS + relay self-hosted per gestirle da iPhone su più macchine.
https://t.co/xEWRpxWxYS
@gitsocialspace Thanks for the mention! The analysis only covers 3 personal repos, missing most of my work at YAI Labs: https://t.co/E21gjfRwR6.
The stats are therefore incomplete and misleading. Could you include organization contributions?
I keep ending up with Codex spread across my MacBook, Linux workstation and DGX.
SSH works. Codex Remote in the ChatGPT app works too. But neither feels like the way I want to manage the whole setup from my phone.
So I built Codex Relay:
https://t.co/xEWRpxWxYS
Since Astra dropped, everyone's rest days have increased. I was worried I'd burned through my weekly limit in two days, but it turns out we are all on a break.
@thsottiaux I'm a pro user and I worked better with Astra than Sol, but in two days I’ve used up the equivalent of one of my typical five-day sessions with Sol.
@shub0414 I'm a pro user and I worked better with Astra than Sol, but in two days I’ve used up the equivalent of one of my typical five-day sessions with Sol.
@ivanfioravanti One of those projects might be YVEX. I’m building a native C/CUDA compiler/runtime for local open-weight inference. DeepSeek-V4-Flash-DSpark now runs end to end on a DGX Spark. I’m consolidating the execution architecture before measured GB10 optimization.
https://t.co/ZkEYJc4DhV
YVEX now generates text end to end on a single DGX Spark.
Its first complete model path is DeepSeek-V4-Flash-DSpark, compiled into a mixed IQ2_XXS/Q2_K GGUF and executed by YVEX’s own C/CUDA runtime.
No llama.cpp. No external inference engine.
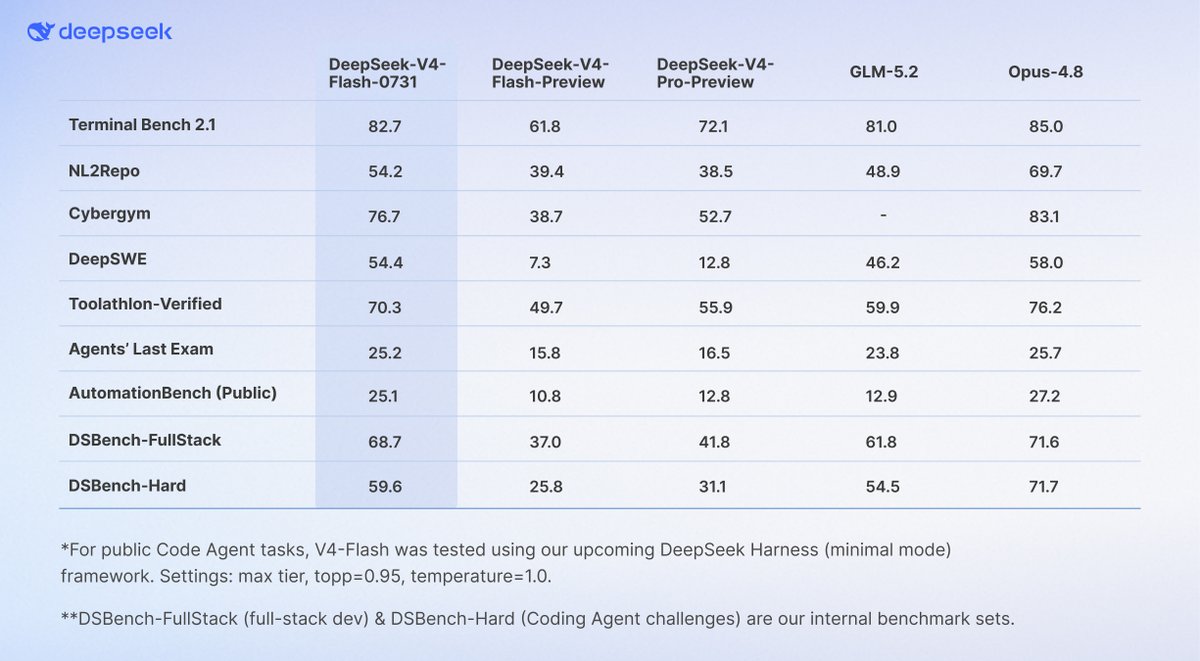
🚀 DeepSeek-V4-Flash Official API is now LIVE in public beta!
🔷 We’ve massively upgraded its Agent capabilities—benchmark scores are now far surpassing the V4-Pro-Preview. Check out the massive performance leap below! 👇
🔷 The official V4-Flash now natively supports the Responses API format and is fully adapted for Codex!
Check out the configuration details in our official API docs: https://t.co/smCwQZMeiq
Bit slow, but apparently possible. Local inference is becoming something we can actually build around. Hardware is opening the way, software will decide what becomes practical.