I will be presenting two posters at #EMNLP2025 on Nov 5 (Hall C):
• 1–2 PM — FaviComp: Familiarity-Aware Evidence Compression for RAG
• 2:30–4 PM — Code Execution as Grounded Supervision for LLM Reasoning
Come chat about RAG and grounded reasoning supervision for LLM!
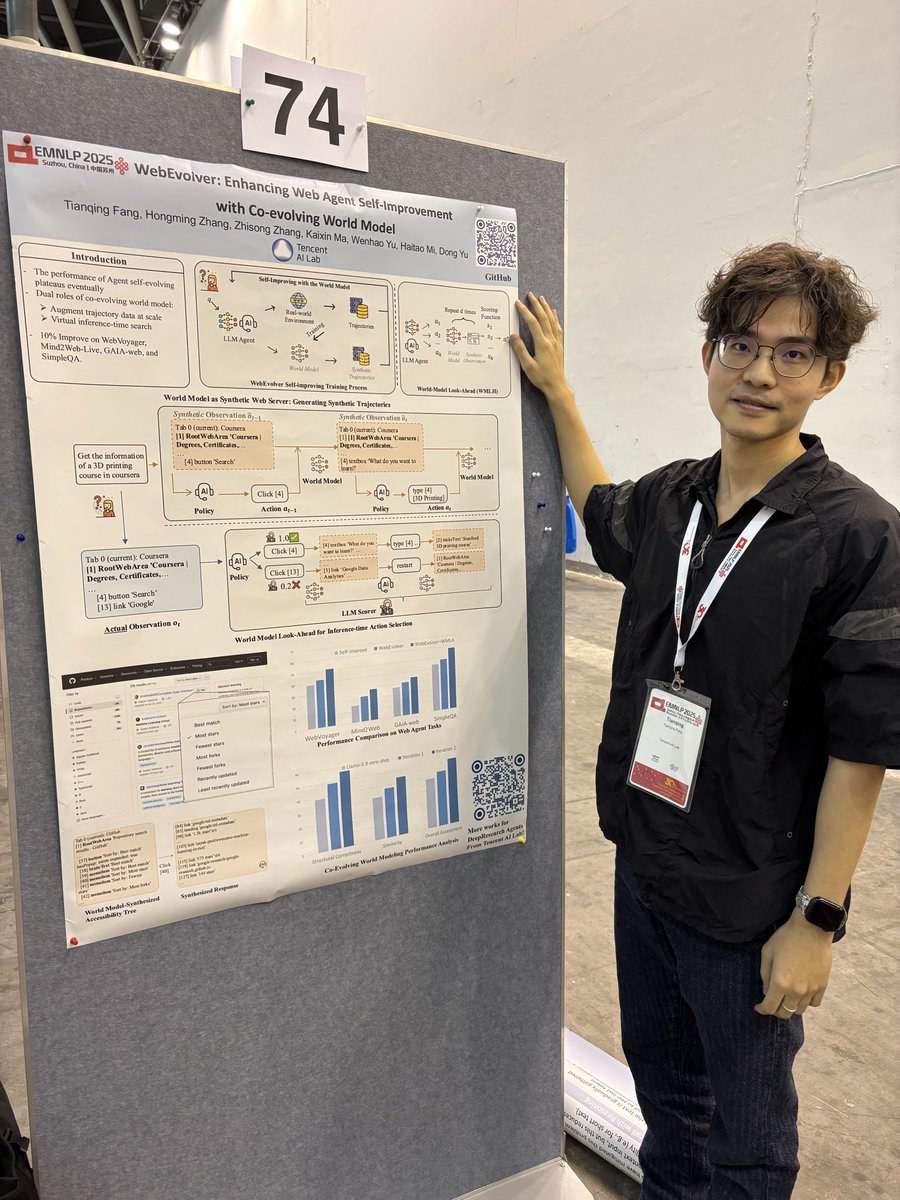
#emnlp2025 I’m presenting several papers I authored at Tencent AI Lab about agent self evolving and LLM memory. There will also be an oral presentation on the WebEvolver paper at Thu. Nov 6 at 16:30-18:00 Location: A110. Come and chat with me 😆
Sad I can’t make it to EMNLP in person this year, but I’ll be presenting our paper virtually! Catch me on Nov 6, 8 AM CST / Nov 5, 9 PM EST at GatherTown booth 1715 (https://t.co/P3N4a7WIEh)! Drop by and say hi!
Last year, I led an unlearning effort at Amazon with the Nova Responsible AI and Pretraining teams, focusing on controlling model knowledge and behavior. We hosted an LLM unlearning challenge at Semeval and developed LUME unlearning bechmark a multitask optimization method, and a selective unlearning approach. I'm excited to see our insights contribute to the recently released Amazon Nova Customization feature. We will be presenting two of these papers at EMNLP and I'd be happy to connect with anyone interested in this topic. See more details in the following post from Rahul. https://t.co/QPWobTLItR
🧠🚀 Excited to introduce Supervised Reinforcement Learning—a framework that leverages expert trajectories to teach small LMs how to reason through hard problems without losing their minds. 🤯
Better than SFT && RLVR.
Read more: https://t.co/taEL8Vk4X5
#llms#RL#reasoning
🆕Drop from Gemini VibeCoding Team:
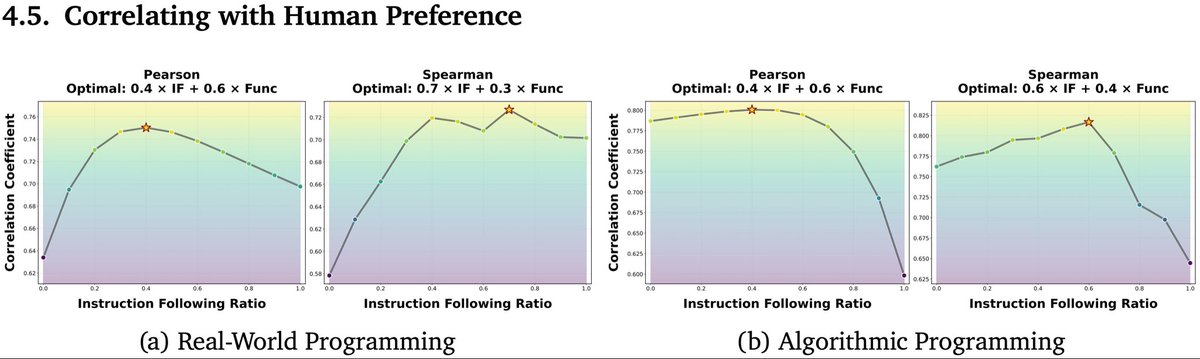
Why does code functionality correctness NOT necessarily translate to 𝗯𝗲𝘁𝘁𝗲𝗿 𝘂𝘀𝗲𝗿 𝗽𝗿𝗲𝗳𝗲𝗿𝗲𝗻𝗰𝗲 𝗳𝗼𝗿 𝗰𝗼𝗱𝗶𝗻𝗴 tasks?
In 𝗩𝗶𝗯𝗲𝗖𝗵𝗲𝗰𝗸𝗲𝗿: https://t.co/SINlvRIumJ, we find that the human preference correlates the best with a composite score of functional correctness and instruction following capability.
To evaluate the instruction following capability of LLM for coding, we propose a taxonomy of 𝟯𝟬 𝘃𝗲𝗿𝗶𝗳𝗶𝗮𝗯𝗹𝗲 𝗰𝗼𝗱𝗶𝗻𝗴 𝗶𝗻𝘀𝘁𝗿𝘂𝗰𝘁𝗶𝗼𝗻𝘀 together with their corresponding deterministic checkers.
We evaluated 31 leading LLMs and
show that even the strongest models struggle to comply with multiple instructions and exhibit clear functional regression!
Please take a look at our paper and let us know how you like it!
We also look forward to seeing the community extend the work on real user coding prompts to understand how we can improve 𝗿𝗲𝗮𝗹-𝘄𝗼𝗿𝗹𝗱 𝘂𝘀𝗲𝗿 𝗰𝗼𝗱𝗶𝗻𝗴 𝗲𝘅𝗽𝗲𝗿𝗶𝗲𝗻𝗰𝗲, let us know if you want to collaborate on these topics! (0/1)
[Belated update]
Excited to share I’ll be starting my PhD with @johnhewtt at Columbia!
I’m deeply grateful to my advisors Prof. @robinomial and Prof. @muhao_chen, my mentor @fwang_nlp, Prof. @_jessethomason_, Prof. Hao Zhou at TsinghuaAIR, and all my peers @USC.
🧵
In addition, we show a rubric-based reward can help steering models’ thinking/reflection process, potentially key to future directions on infusing constraints in reasoning.
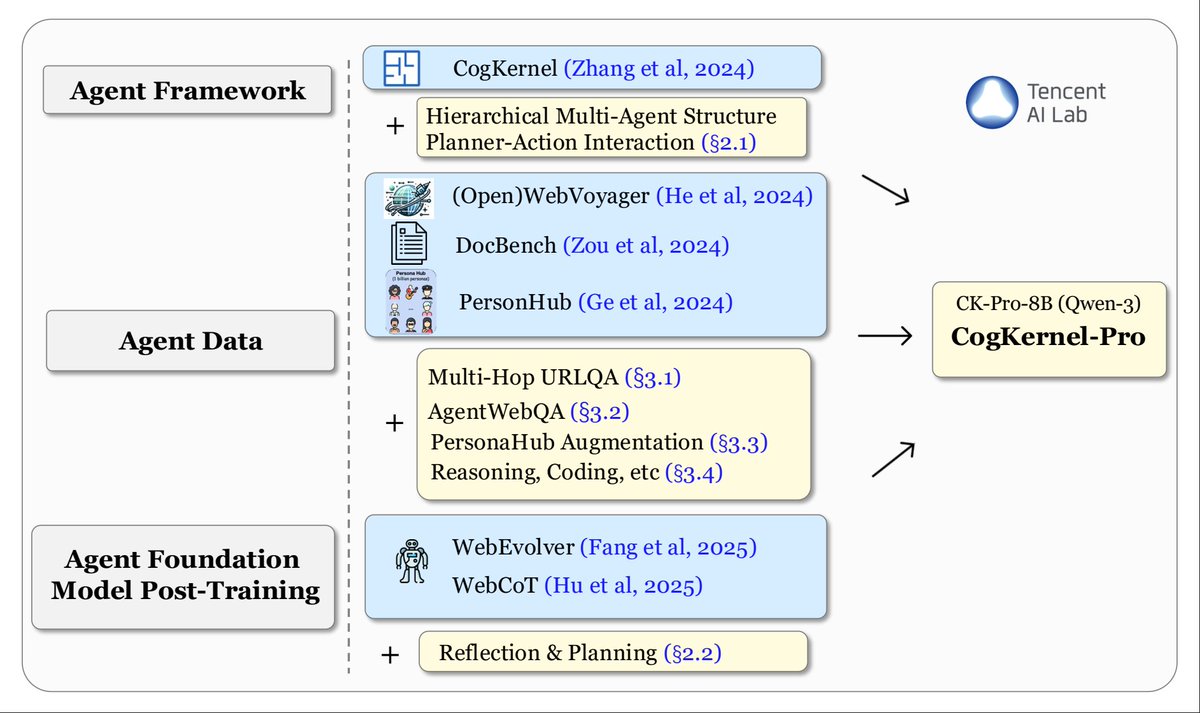
🚀 We are thrilled to release a new open-source Deep Research Agent, Cognitive Kernel-Pro, from Tencent AI Lab! We focus on building a fully open-source agent with (to the maximum extent) free tools, showcasing impressive performance on GAIA with Claude-3.7-sonnet and surpass the counterpart, SmolAgents by a large margin.
In addition, we study the training recipe for an open-source Deep Research Agent Foundation Model. We curate high-quality training data (queries, trajectories, and verifiable answers across web, file, code, and reasoning domains). Our finetuned Qwen3-8B (CK-Pro-8B) surpasses WebDancer and WebSailor with the similar model size on the text-only subset of GAIA.
📜 Paper: https://t.co/CHLs2U0JLy
🔧 Code: https://t.co/8dxtnjdsxn
🤗 Data & Model:
https://t.co/jzaV1LywnK
https://t.co/KD8k9WqGM9
This work builds on the previous efforts of Tencent AI Lab (Fig. 2). Be sure to check them out if you're interested!
1+1=3
2+2=5
3+3=?
Many language models (e.g., Llama 3 8B, Mistral v0.1 7B) will answer 7. But why?
We dig into the model internals, uncover a function induction mechanism, and find that it’s broadly reused when models encounter surprises during in-context learning. 🧵
A little late but nevertheless happy to share that our paper “Outlier Gradient Analysis: Efficiently Identifying Detrimental Training Samples for Deep Learning Models” was accepted as an oral presentation at #ICML2025 (top 1%). More details here: https://t.co/0E5wkLUA8X!
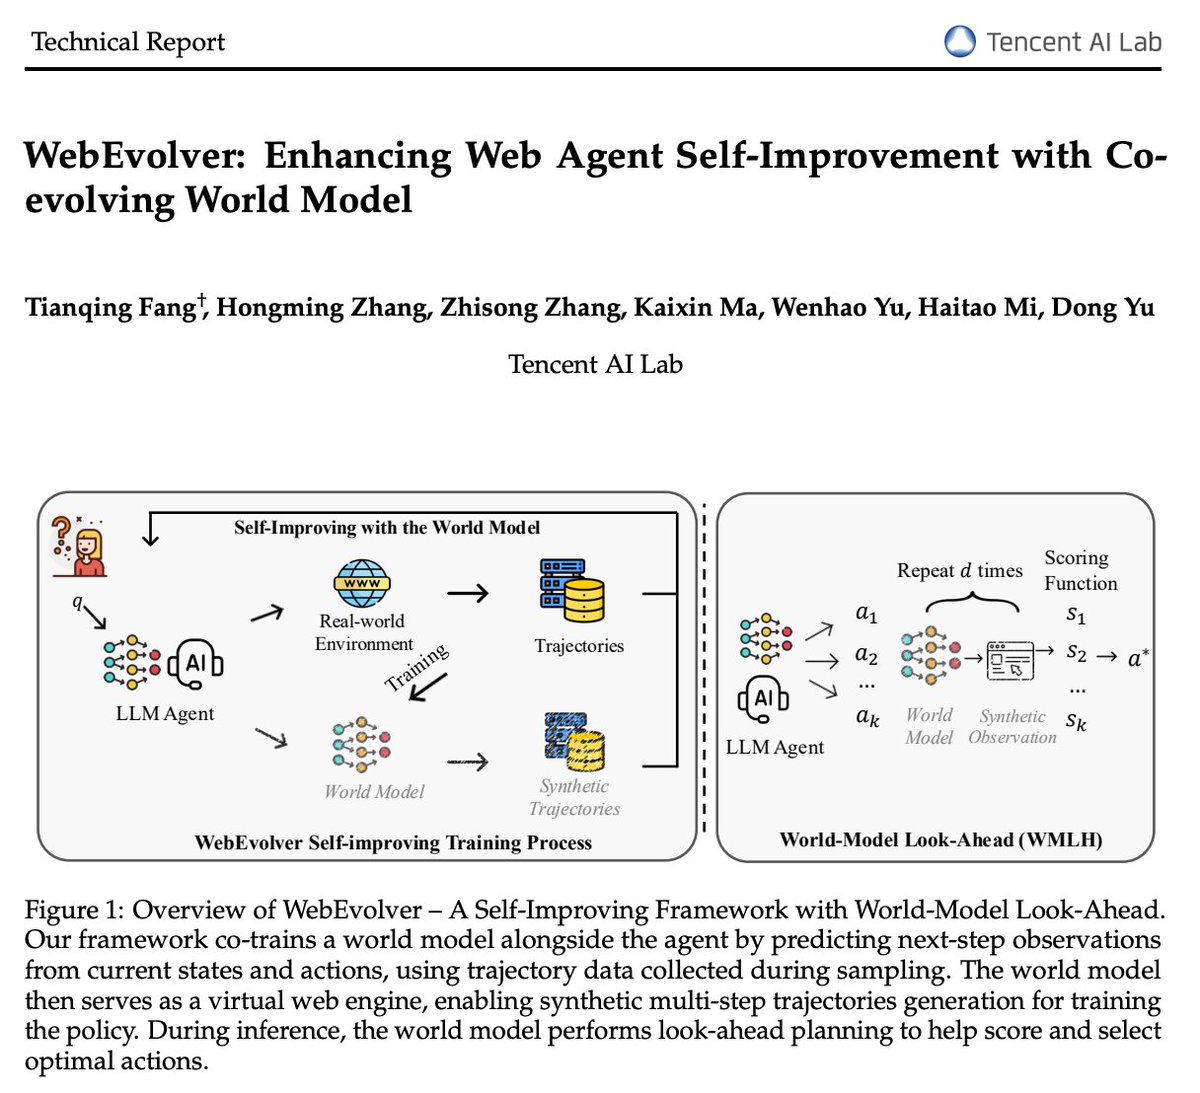
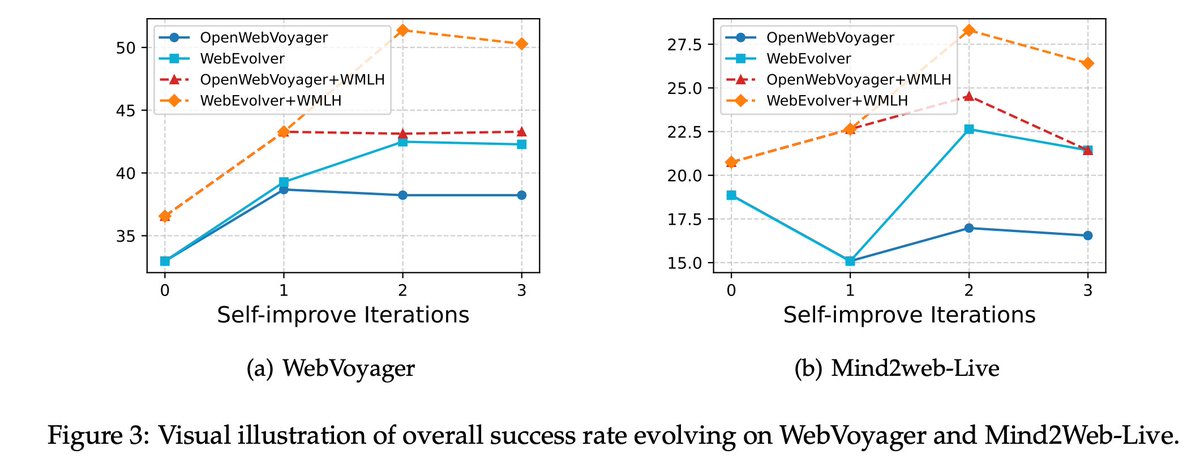
🚀 Check out our paper: WebEvolver: Enhancing Web Agent Self-Improvement with Coevolving World Model, from Tencent AI Lab!.
We present a world model-driven framework for self-improving web agents, addressing critical challenges in self-training—such as limited exploration and performance plateaus.
🔍 Key Innovations:
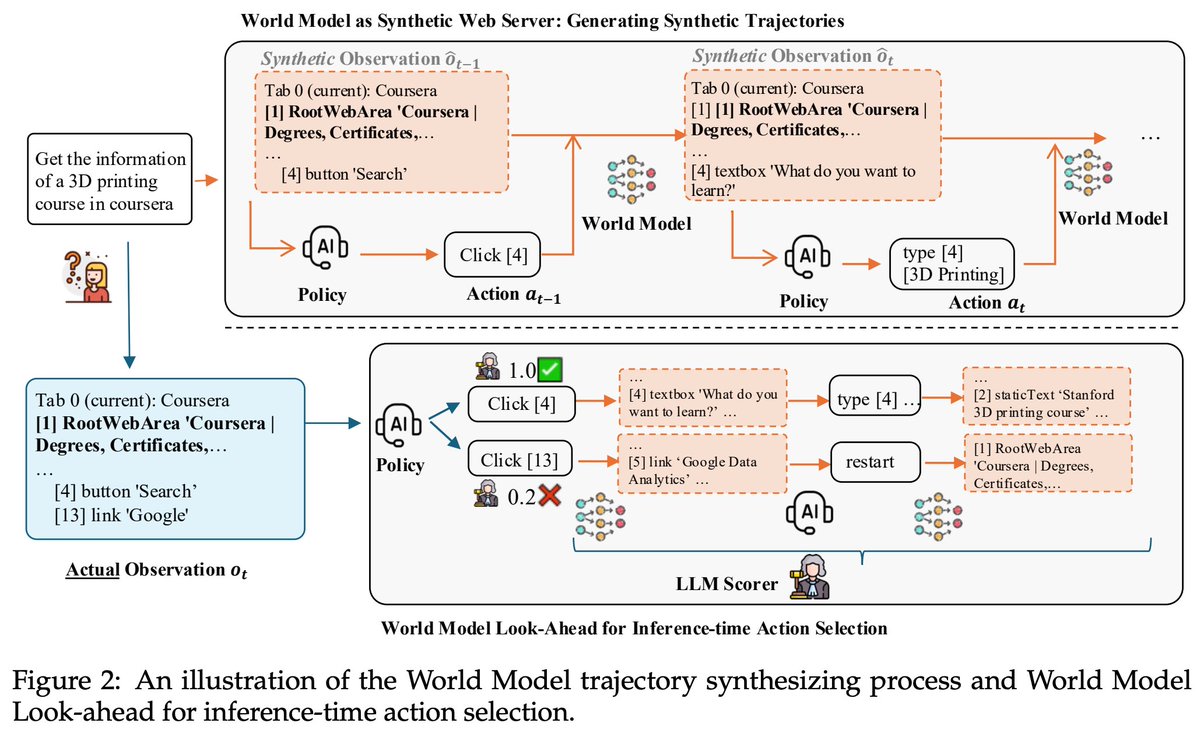
- Co-Evolving World Model:
The world model is implemented as an LLM that predicts the next webpage state (observation) given the current state and a planned action.
In addition to fine-tuning the agent's policy model using self-generated trajectories, the same data is repurposed to train the world model.
- World Model as Web Server
Training Phase: sample pseudo trajectories by replacing the real web server with the world model.
Inference Phase: simulate the outcome of candidate actions with 1-2 step look-ahead planning, to help better select actions.
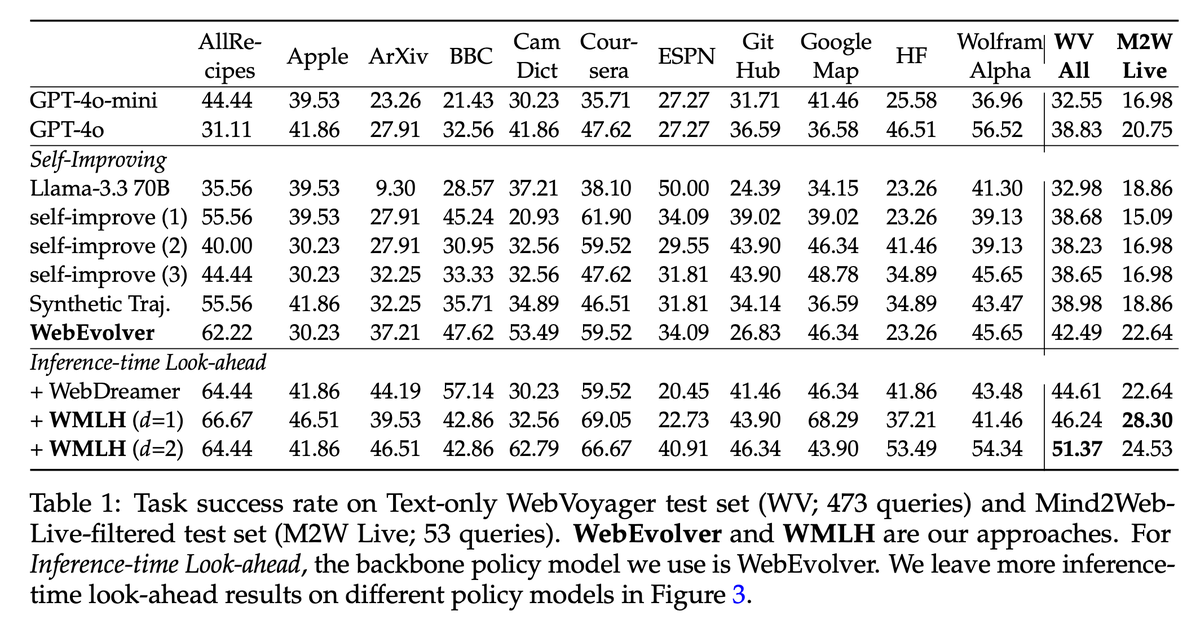
📊 Results on Real-World Tasks (Mind2Web-Live & WebVoyager):
✅ ~10% higher success rate vs. pure self-training.
✅ significantly fewer environment interactions—efficient yet powerful!
arxiv: https://t.co/7tMVy4iI0J
code: https://t.co/wzutAx8zNR
🚨 New paper accepted to #ACL2025!
We propose SudoLM, a framework that lets LLMs learn access control over parametric knowledge.
Rather than blocking everyone from sensitive knowledge, SudoLM grants access to authorized users only.
Paper: https://t.co/gzzs9L6S1z
🧵[1/6]👇
🔦 Speaker Spotlight: Sercan Ö. Arık (@sercanarik)
We're thrilled to welcome Sercan, Senior Staff Research Scientist at Google Cloud AI, as an invited speaker at the ICML 2025 Workshop on Computer Use Agents!
Sercan's focuses on democratizing AI and applying it to impactful use cases across various industries. We're excited to hear his insights on making AI agents more interpretable, robust, and reliable.
#ICML2025 #ComputerUseAgents #LLMAgents #AI