Introducing Griffin, the first model to pass the video Turing test.
48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.
It’s the first Human Interaction Model (HIM).
We turned Qwen3.8-27B into a multimodal decision model.
It beat Pokémon FireRed’s elite four and champion with sub-100 ms decisions from live game state.
With SGLang’s native /v1/decisions, you can now turn LLMs and VLMs into classification and scoring models.
We also added /v1/systemone so Jev-like open models can work with the TypeSafe SDK.
Okay I built it!
🍰 Infinite Slop
https://t.co/wz0a7VSBtS
An infinite and interactive AI generated live stream of slop that goes on forever and ever
Anything that you write in the chat is generated next and AI will try to connect it to the previous video so there's an actual sequence and story line
Idea by @marcantoinefon and @rehan_shei's original stream so I made it
It'd be very expensive to run this so @fal very generously sponsors this
They also fine-tuned the model that makes this possible for the first time, making Minimax H3 50x faster and as "Max" and it can now generate videos faster than you can watch them, very cool!
Let me know what you think!!!! 😊
Built a control plane for my DGX Spark, lets me switch models in one click, manage the local cache, and monitor live workloads in real time.
https://t.co/kntBP5Dtzz
CVE-2026-34348 exploitation demo from my #BHUSA "Pass-the-Passkey Family of Attacks" talk: WebAuthn assertion from recent YubiKey authentication is extracted from Windows Event Log and replayed against Microsoft Entra ID using Passkey Injector.
Whitepaper: https://t.co/bp5sriMB5z
☁️Mistral is bringing together the inference infrastructure, open models, and long-term commitments Europe needs to control its AI future, and setting a roadmap for the world. 🧵: https://t.co/LeP53uBUES
We just launched Xirp, a vendor-neutral agentic development environment. One place to manage agent sessions across @ClaudeDevs, @GeminiApp CLI, and @OpenAI Codex. 1,300+ @Spotify engineers already use it. Now it's available for you to try. Learn more at https://t.co/Hwo8Qqx4OI.
DeepSeek V4 Flash 0731 can now be run locally! 🐳
Run DeepSeek V4 Flash lossless 4-bit on 168GB RAM and 3-bit on 110GB RAM.
V4 Flash 0731 outperforms V4 Pro. Run via Unsloth or llama.cpp. Smaller quants coming today.
Guide: https://t.co/mCZZkpa95X
GGUF: https://t.co/ac6uOI8mZA
vLLM v0.23.0 is out! 408 commits from 200 contributors (63 new). 🎉
Highlights: DeepSeek-V4 matures across backends (TRTLLM-gen attention kernel, sparse MLA decoupled from V3.2, EPLB for the Mega-MoE), Model Runner V2 now default for Llama + Mistral dense models, Gemma 4 Unified (encoder-free) + MTP, a maturing Rust frontend, multi-tier KV cache offloading with an object-store tier, and a unified reasoning + tool-call parser.
Thread 👇
Meet DiffusionGemma!
An experimental open model that explores a fast approach to text generation, released under an Apache 2.0 license.
Moving beyond sequential, token-by-token processes to generate entire blocks of text simultaneously. Here’s what’s new with DiffusionGemma: 👇
If you're interested in looking at the exact setup, the full launch script, environment variables, and raw benchmarking data are available here: https://t.co/NccoARVxTN
Spent the night benchmarking my new DGX Spark (GB10) serving Gemma-4-26B in NVFP4 via vLLM. Wrote a custom launch script to handle the initialization, which gets a local, agent-ready, OpenAI-compatible endpoint up and running smoothly.
The value here isn't speed, but the fact that the entire job fits. It handles the load near-silently at 120-240W total system draw (compared to a single high-end GPU pulling 575W on its own). Evaluating this hardware is more about what fits, and what breaks first under load.
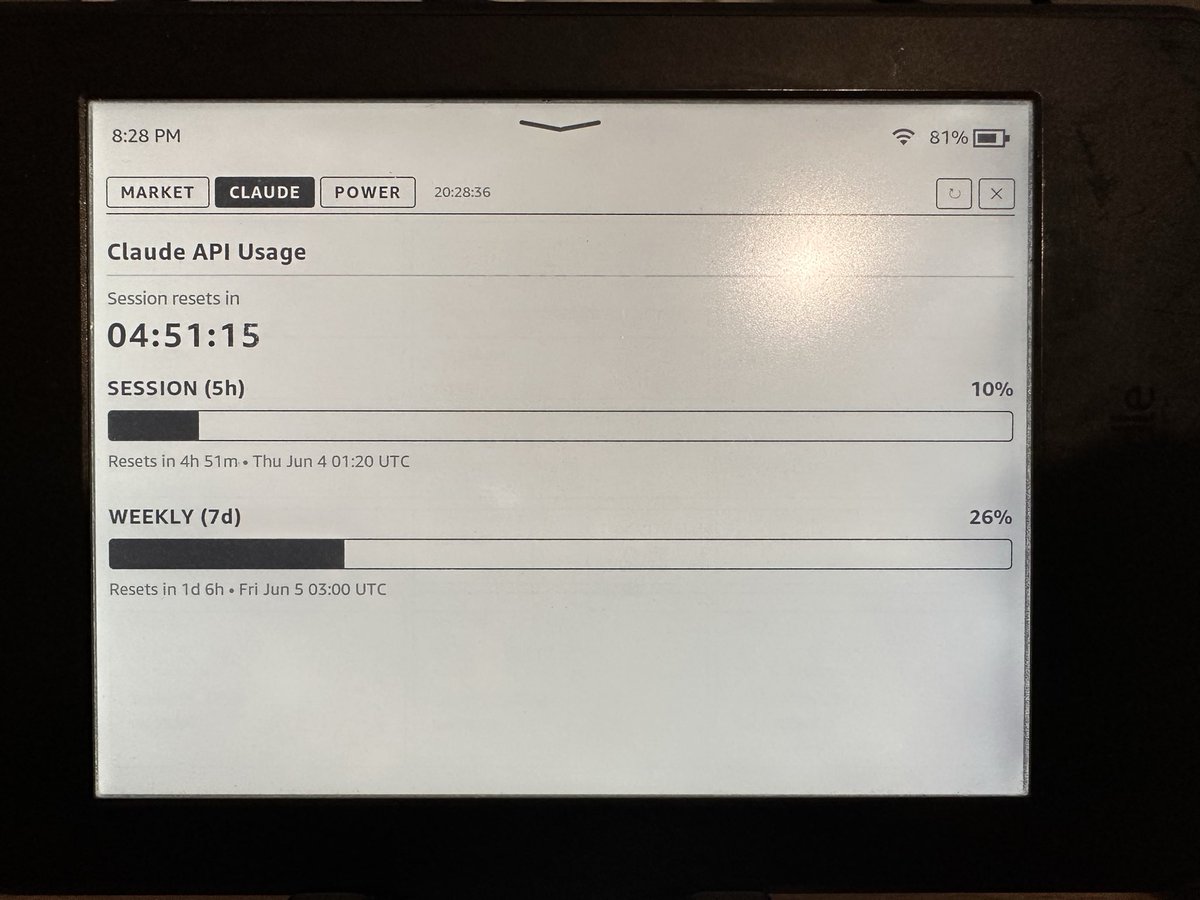
Fun weekend project: turned my 10+ year old Kindle Paperwhite 7th gen into a home dashboard for stock prices, Claude integrations, and IoT stats. It turned out way better than expected! Now thinking about adding my Hermes agent status to it next. ♻️📱