“100% 𝘕𝘦𝘵𝘳𝘢 𝘪𝘴 𝘢 𝘣𝘳𝘪𝘭𝘭𝘪𝘢𝘯𝘵 𝘵𝘰𝘰𝘭... 𝘢 𝘧𝘢𝘯𝘵𝘢𝘴𝘵𝘪𝘤 𝘵𝘰𝘰𝘭 𝘵𝘩𝘢𝘵 𝘐 𝘸𝘰𝘶𝘭𝘥 𝘴𝘵𝘳𝘰𝘯𝘨𝘭𝘺 𝘳𝘦𝘤𝘰𝘮𝘮𝘦𝘯𝘥 𝘧𝘰𝘳 𝘢𝘯𝘺𝘰𝘯𝘦 𝘴𝘩𝘪𝘱𝘱𝘪𝘯𝘨 𝘢𝘨𝘦𝘯𝘵𝘴 𝘪𝘯 𝘱𝘳𝘰𝘥𝘶𝘤𝘵𝘪𝘰𝘯.”
That is @SumukhAvadhani , CTO and Co-founder of @trypencil , on Netra.
Pencil is aiming to be a fully agentified OS for the marketing stack, with enterprise workflows across both creative and media. With 300 to 400 agents running in production, knowing an agent responded is never enough.
This is what reliable AI agents look like in practice: teams that know how well their agents are doing, not just whether they replied.
Hear the full story from Sumukh on YouTube, from how Pencil tests its agents to how it handles them at scale.
Link in the comments.
Make your AI agents reliable with https://t.co/2edqhjr4Ap
𝗧𝗵𝗶𝘀 𝗶𝘀 𝗮𝗹𝗹 𝗶𝘁 𝘁𝗮𝗸𝗲𝘀 𝘁𝗼 𝗴𝗲𝗻𝗲𝗿𝗮𝘁𝗲 𝘁𝗲𝘀𝘁 𝗰𝗮𝘀𝗲𝘀 𝗳𝗼𝗿 𝘆𝗼𝘂𝗿 𝗔𝗜 𝗮𝗴𝗲𝗻𝘁 𝗶𝗻 𝗡𝗲𝘁𝗿𝗮: 𝗮 𝗽𝗿𝗼𝗺𝗽𝘁 𝗮𝗻𝗱 𝗼𝗻𝗲 𝗰𝗹𝗶𝗰𝗸.
Then Netra can auto-suggest the evaluators too. Need more control? There is a way to do that as well. You can pick an agent, upload docs, set paths, and choose how many test cases you want.
Watch the video to see how it’s done.
Link in the comments.
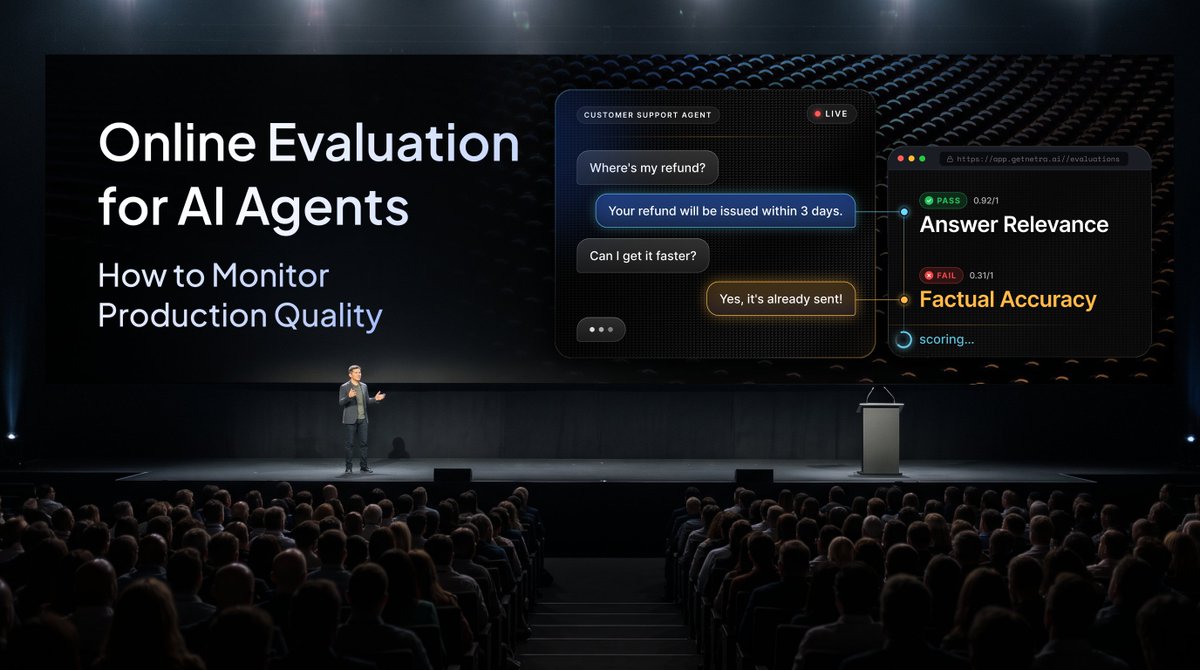
Testing your AI agent before launch is only half the job. The other half begins when real users start interacting with it. That half is called online evaluation.
Online evaluation scores real conversations as they happen, so you catch quality drops before your customers do.
You see which agent or route is struggling. You find the failures your test set never covered. And every failure can become a test case, so the same issue is less likely to come back.
This blog shows how to set up online evaluation in five steps, and how it works in Netra.
Link in the comments.
𝗩𝗼𝗶𝗰𝗲 𝗮𝗴𝗲𝗻𝘁𝘀 𝗮𝗿𝗲 𝗯𝗲𝗰𝗼𝗺𝗶𝗻𝗴 𝗽𝗮𝗿𝘁 𝗼𝗳 𝗺𝗼𝗿𝗲 𝗰𝘂𝘀𝘁𝗼𝗺𝗲𝗿 𝗲𝘅𝗽𝗲𝗿𝗶𝗲𝗻𝗰𝗲𝘀 𝗲𝘃𝗲𝗿𝘆 𝗱𝗮𝘆, 𝗮𝗻𝗱 𝗼𝘂𝗿 𝗶𝗻𝘁𝗲𝗿𝗮𝗰𝘁𝗶𝗼𝗻𝘀 𝘄𝗶𝘁𝗵 𝘁𝗵𝗲𝗺 𝗸𝗲𝗲𝗽 𝗿𝗶𝘀𝗶𝗻𝗴.
But a voice agent can keep the conversation going and still get it wrong. It can mishear someone, miss an accent, or miss the urgency in a caller’s voice. Nothing crashes. The call just becomes a bad experience, and you might lose a customer.
So how do you catch that before your customers do?
With Netra voice agent testing, you connect your agent and choose who is calling, the scenario, the conditions, and which evaluators to use, or add your own custom ones. You can also give Netra the context of your agent or a PRD, and it can generate test cases automatically. Then start the simulation. Netra runs every call automatically, transcribes it and scores it. You see where your agent falls short, fix it, and test again to make your voice agent reliable.
To see how it works, watch the video and check out the full playlist. You will see what voice agent testing with Netra is like, how to set it up, and a quick demo of what it finds once the test runs.
Full playlist link in the comments
𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗸𝗻𝗼𝘄 𝘆𝗼𝘂𝗿 𝘃𝗼𝗶𝗰𝗲 𝗮𝗴𝗲𝗻𝘁 𝗶𝘀 𝗿𝗲𝗮𝗱𝘆 𝗳𝗼𝗿 𝗿𝗲𝗮𝗹 𝗰𝗮𝗹𝗹𝗲𝗿𝘀?
The frustrated caller on a noisy street. The fast talker who interrupts. The one who asks something your agent shouldn’t answer.
You won’t find out by waiting for them to call.
Here’s how we test voice agents in Netra, step by step.
Link in the comments.
𝗪𝗵𝗮𝘁 𝗶𝗳 𝘁𝗲𝘀𝘁𝗶𝗻𝗴 𝘆𝗼𝘂𝗿 𝘃𝗼𝗶𝗰𝗲 𝗮𝗴𝗲𝗻𝘁 𝗮𝗴𝗮𝗶𝗻𝘀𝘁 𝗵𝘂𝗻𝗱𝗿𝗲𝗱𝘀 𝗼𝗳 𝗱𝗶𝗳𝗳𝗲𝗿𝗲𝗻𝘁 𝗰𝗮𝗹𝗹𝗲𝗿𝘀 𝘁𝗼𝗼𝗸 𝗷𝘂𝘀𝘁 𝗮 𝗳𝗲𝘄 𝗰𝗹𝗶𝗰𝗸𝘀?
Meet Voice Simulation in Netra.
Connect your voice agent, pick who should call and what they need, and start the simulation. Netra takes it from there.
Every call is made, recorded, transcribed and scored for you. You see how well your agent understood the caller, how natural it sounded and whether it kept the conversation on track.
Callers can be angry, confused, fast or slow, and speak with different accents and languages. Requests can be simple or messy. Backgrounds can be a quiet office or a crowded cafe. Use prebuilt personas or create your own.
Find the issues. Fix them. Run it again.
Make your voice agents reliable.
Link in the comments.
𝗬𝗼𝘂𝗿 𝗮𝗴𝗲𝗻𝘁 𝗽𝗮𝘀𝘀𝗲𝗱 𝗲𝘃𝗲𝗿𝘆 𝘁𝗲𝘀𝘁. 𝗦𝗼 𝘄𝗵𝘆 𝗱𝗶𝗱 𝗶𝘁 𝗰𝗼𝗻𝘁𝗿𝗮𝗱𝗶𝗰𝘁 𝗶𝘁𝘀𝗲𝗹𝗳 𝗳𝗶𝘃𝗲 𝗺𝗲𝘀𝘀𝗮𝗴𝗲𝘀 𝗶𝗻?
Single-turn tests stop at one response. Conversations keep going.
We put together a guide on testing AI agents through multi-turn simulation, using Netra.
From first scenario to root cause in one read.
Link in the comments.
Do your evals stop the day your agent ships?
Testing before release covers the scenarios you planned for. Real users bring the rest.
We put together a guide on how to evaluate AI agents before and after deployment, using Netra.
Curious how it’s done?
Link in the comments.
𝗧𝗵𝗮𝘁’𝘀 𝗮 𝘄𝗿𝗮𝗽 𝗳𝗼𝗿 𝗡𝗲𝘁𝗿𝗮 𝗮𝘁 𝗖𝘆𝗽𝗵𝗲𝗿 𝟮𝟬𝟮𝟲.
For three days, one question kept opening up conversations at our stall:
How are you testing your AI agents, and how do you know they’re reliable?
What we heard was interesting.
Most teams are familiar with observability and evaluations. But the conversations changed when we started showing how deep agent evaluation can go, and how reliability needs more than checking a response once.
We also met teams using separate platforms for observability and evaluations, building their own evaluators, or still relying heavily on manual testing.
That gave us the opportunity to show a different approach.
Netra brings AI agent observability, evaluation, simulation, and security testing together in one platform, built for text, voice, image, and video agents.
Simulation, Agent Insights, security testing, and online evals were some of the areas that sparked the most curiosity. People wanted to understand how these different layers could work together to help them build more reliable agents.
And we learned just as much from hearing about the reliability challenges teams are facing in the real world.
On stage, Prasanth, Co-founder and CTO of Netra, took that conversation deeper with “Why AI That Works Once Is Not Enough: The Agent Testing Ladder.”
From founders and CEOs to data scientists and AI agent builders, it was great meeting everyone who stopped by, played the AI Agent Evaluator quiz, shared what they are building, and spent time with us.
That’s Cypher 2026 for Team Netra.
Want to see how Netra helps you make your AI agents more reliable? Link in the comments.
#Cypher2026 #AIAgents #AIReliability #AgenticAI #AIObservability
𝗗𝗮𝘆 𝟮 𝗮𝘁 𝗖𝘆𝗽𝗵𝗲𝗿 𝟮𝟬𝟮𝟲 𝘄𝗮𝘀 𝗮𝗯𝗼𝘂𝘁 𝘀𝗵𝗼𝘄𝗶𝗻𝗴 𝗽𝗲𝗼𝗽𝗹𝗲 𝘄𝗵𝗮𝘁 𝗔𝗜 𝗮𝗴𝗲𝗻𝘁 𝗿𝗲𝗹𝗶𝗮𝗯𝗶𝗹𝗶𝘁𝘆 𝗹𝗼𝗼𝗸𝘀 𝗹𝗶𝗸𝗲 𝗶𝗻 𝗽𝗿𝗮𝗰𝘁𝗶𝗰𝗲.
One thing we heard repeatedly was how fragmented agent testing still is.
Some teams use one platform for observability and another for evaluations. Some build their own evaluators. Others still rely heavily on manual testing.
And despite all of that, the reliability challenges remain.
So we spent Day 2 showing teams how we approach it at Netra: bringing the different layers of agent reliability together in one platform, so teams can understand what their agents are doing, evaluate them, test how they behave, and keep improving them as they evolve.
The conversations also made one thing clear.
A lot of teams are building AI agents fast, but testing still tends to happen in parts, or not deeply enough.
That is where the reliability gap shows up.
Reliable agents need layers.
And that’s what we got to show throughout Day 2.
#Cypher2026 #AIAgents #AIReliability #AgenticAI #AIObservability
𝗗𝗮𝘆 𝟭 𝗮𝘁 Cypher 2026 𝗳𝗼𝗿 𝗧𝗲𝗮𝗺 𝗡𝗲𝘁𝗿𝗮 𝘄𝗮𝘀 𝗳𝘂𝗹𝗹 𝗼𝗳 𝗰𝗼𝗻𝘃𝗲𝗿𝘀𝗮𝘁𝗶𝗼𝗻𝘀 𝗮𝗯𝗼𝘂𝘁 𝗼𝗻𝗲 𝘁𝗵𝗶𝗻𝗴: 𝗵𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗺𝗮𝗸𝗲 𝗔𝗜 𝗮𝗴𝗲𝗻𝘁𝘀 𝗿𝗲𝗹𝗶𝗮𝗯𝗹𝗲?
Our team interacted with founders, CEOs, data scientists, and AI agent builders working on very different problems.
Different teams. Different agents. Different use cases.
But one pattern was clear. A lot of AI agents are being built. Testing them with the same depth is still catching up.
We got to show people how we think about making AI agents more reliable, while also learning about the problems they are running into and how they are approaching testing today.
And in between the conversations, visitors got to try our AI Agent Evaluator quiz, an interactive game that put their agent evaluation instincts to the test.
We shared a lot. We learned a lot too.
A great first day at Cypher 2026, India’s biggest AI summit and expo.
Looking forward to more conversations on Day 2.
@Analyticsindiam