$10 to give your Claude, ChatGPT, Opencode subscription a VM
Open source
Free texting (iMessage, reactions, voice notes)
Hosted Pages
Image generation
1,400+ app connections
Live note taking
Integrated with @bee__computer
World class memory powered by @mem0ai
Computer use that works
and so much more...
$10 a month
Introducing 1Helm:
BYOK/BYOSub (ChatGPT/Claude/Opencode)
Every agent gets its own VM
Mac, iOS, Android, Web apps
Connects to 1,400+ apps
Cowork on files with your agent
Host websites/artifacts
Just $10/mo if you use your existing subscription, or $30 if you want us to handle AI
$10 to give your Claude, ChatGPT, Opencode subscription a VM
Open source
Free texting (iMessage, reactions, voice notes)
Hosted Pages
Image generation
1,400+ app connections
Live note taking
Integrated with @bee__computer
World class memory powered by @mem0ai
Computer use that works
and so much more...
$10 a month
Introducing 1Helm:
BYOK/BYOSub (ChatGPT/Claude/Opencode)
Every agent gets its own VM
Mac, iOS, Android, Web apps
Connects to 1,400+ apps
Cowork on files with your agent
Host websites/artifacts
Just $10/mo if you use your existing subscription, or $30 if you want us to handle AI
Introducing 1Helm:
BYOK/BYOSub (ChatGPT/Claude/Opencode)
Every agent gets its own VM
Mac, iOS, Android, Web apps
Connects to 1,400+ apps
Cowork on files with your agent
Host websites/artifacts
Just $10/mo if you use your existing subscription, or $30 if you want us to handle AI
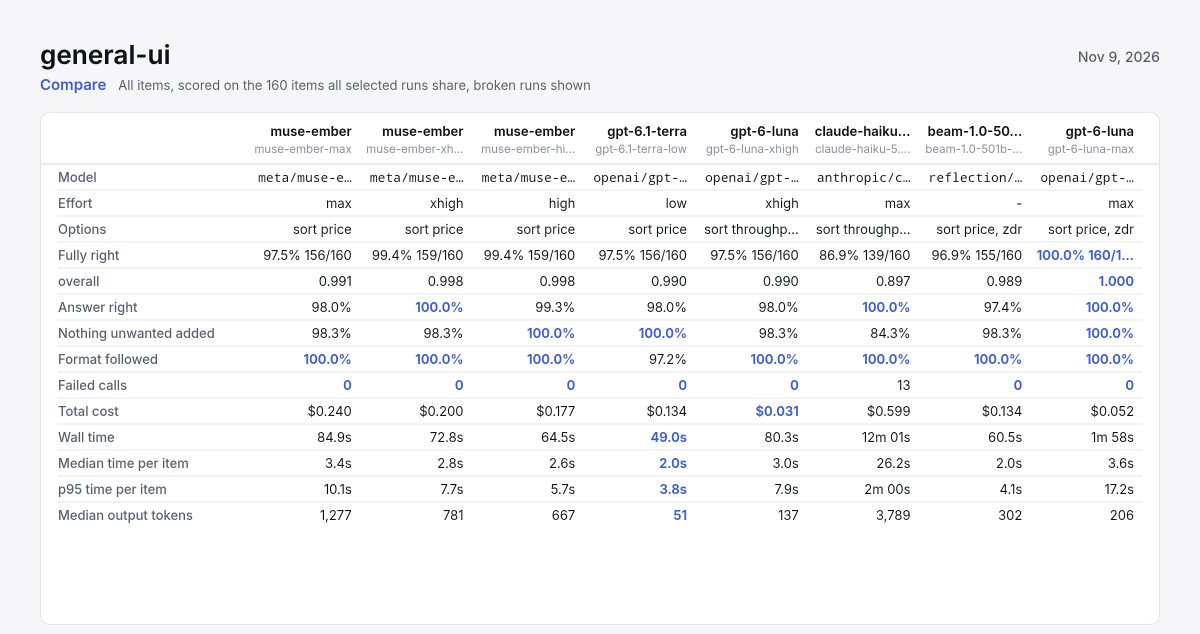
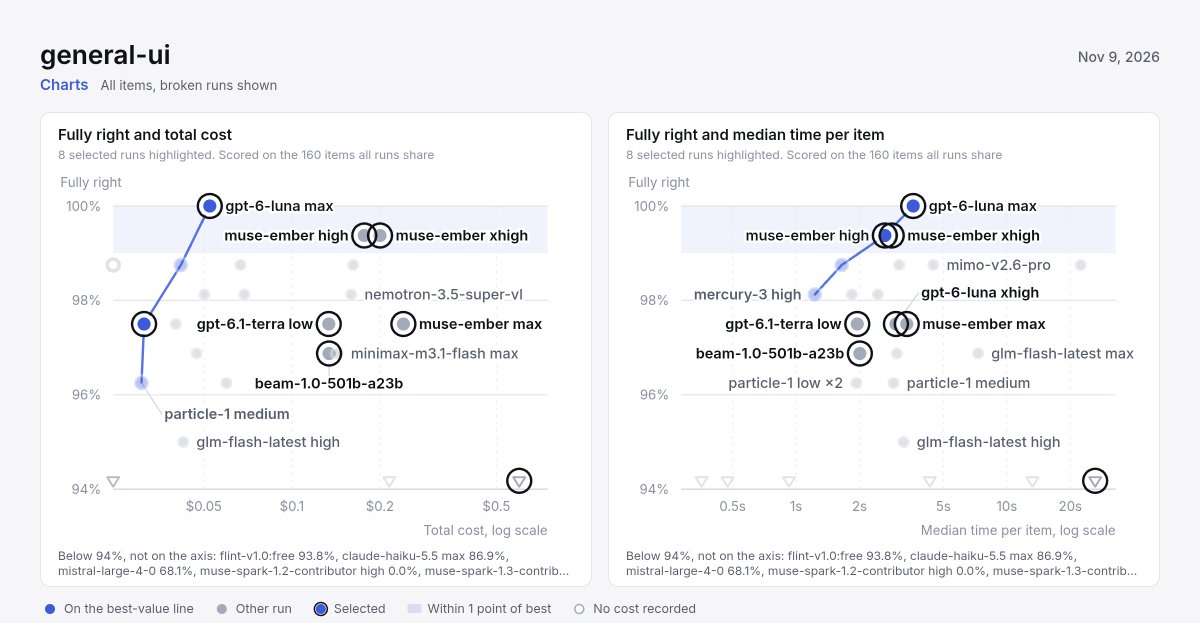
I tested @AIatMeta's new Ember model on @1helmcloud internal evals. It has excellent throughput and wall time, but even with lower input and output prices, it cost more than GPT-6.1 Terra across the 160-item test.
~4x more expensive than Luna Max
~7x more expensive than Luna xhigh
~1.5x more expensive than 6.1 Terra low
~2x cheaper than Haiku max
Ember generated far more output tokens, which appear to outweigh its lower token prices.
Love seeing smaller models increase intelligence though and curious if @alexandr_wang and team will release the weights.
Also, a contributor tier would be cool. At their standard ~90% discount, Ember would cost:
$0.008/M Input
$0.0235/M output
which would make it highly enticing even with the high output tokens.
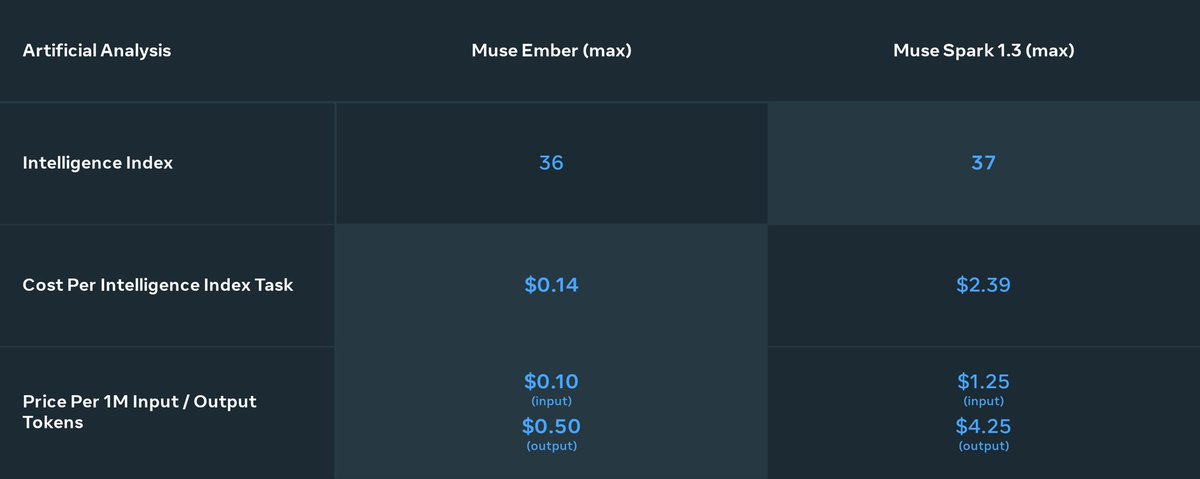
today we released our smallest model yet: Muse Ember 🔥
Muse Ember offers nearly Muse Spark 1.3 (max) intelligence at a 17x cheaper price point (per AA)
Muse Ember is the first model we’ve released trained using Muse Wonder Full
excited for y’all to try on API and muse code!
there are at least 3 full generations of developers who cannot fathom this being the case and will die on the hill that humans need to be deeply and meticulously involved with every LoC before they consider it anything less than "AI slop".
yes, even the ones using AI to develop. the gap between "AI helps me code" and "I tell AI what to code" is bigger than anyone is ready to admit.
there are AI pilled people who HAVE seen full stack apps, massive refactors, huge projects that used to take months and teams of developers collapse into a single dev and a few days with claude. they do exist. just not in any meaningful positions.
We're going to see a LOT MORE of what X just did.
At Town, we've rebuilt systems in 4 days with one engineer. Before AI coding agents, that would've taken us 2 months.
If you're rebuilding something where you already know the requirements and how everything is supposed to behave, agents can do an incredible amount of the work because you can verify.
It's a very different problem from building a new product where you're still figuring out what users want.
https://t.co/QKokjNhKU6
It was marketed as:
- 2 years until permanent underclass
- you’ll all lose your jobs
- your skills will be worthless
- we’re going to replace you
- your entire career is now a $20/month subscription
All in an already terrible job market btw. Possibly the most important technology humanity has ever built, with some of the worst marketing imaginable. The labs completely failed communicating the tech, miserably bad and only improved just end of last year. How did anyone expect that to make people excited?
Vibe coding naked on your local environment is a major security risk, yet almost every enterprise is doing this with Claude Desktop rolled out to business teams.
These workloads must move to locked down cloud sandboxes with a kill switch for IT and Security teams.
I'm not very good at promoting but here goes:
@1helmcloud was launched in July before the wave of personal assistants really took off.
If you've used Muse, Dots, OpenClaw, etc. it will be a familiar & a better experience.
Instead of list out the features, since most share the basics, here's what sets 1Helm apart:
1. World class memory. Can't say enough about how good the memory is.
2. You can text with your agent, for free.
3. Native connections to over 1,500 apps and API's
4. Subscribe to one of the tiers with AI included, or BYOK
5. Incredible live notes
6. A lot more features
Yes, there are plenty of Grok Bot/Muse/Personal Assistants - a vast majority of these came in response to the wave in their popularity.
1Helm came out of personal need, trial and error, and happened to be very early to, what I had no idea, would become the most popular thing since the ChatGPT launch.
Give it a try, a lot of thought and development and intentionality are baked in, I can nearly guarantee that everyone will find a lot of value in it.
https://t.co/Hpw3xxJW2U
Quick explainer for anyone confused why this didn’t happen or was the worst sting attempt in history.
1. A black-hat group that somehow possesses an “FBI-level” volume of real attack data already has the resources, talent, and infrastructure to run their own post-training. They don’t need to outsource RL.
2. Groups that actually steal and hoard that kind of data don’t politely DM Twitter influencers offering “astronomical” money. That’s not how operational security works.
3. Real black-hat crews do not outsource the most sensitive part of their capability (training an offensive model on their proprietary exploit data) to a random open-source AI guy.
4. The entire story requires believing multiple highly improbable things at once. The holes are large enough to drive a planet through.
This didn’t happen.
Yesterday, an anonymous black hat group reached out with an insane RL request.
They offered an astronomical amount of money to post-train open-weight models on exploit data.
The amount of attack data they claim to hold is unlike anything I have ever seen. If someone told me this was an undercover FBI dataset, I would have believed it.
For context, a white-hat project I worked on using GLM-5.3 used less than one percent of that volume, and it already outperformed frontier models by a huge margin.
Of course, I turned it down. But what genuinely scares me is knowing someone else will eventually take the deal.
What is a looped language model—and why should anyone care?
Yesterday SenseNova-Loop-9B-Preview was released and I quantised it to NVFP4 on my DGX Spark.
Here's everything you need to know: 🧵
I think most people have heard of a looped transformer without being certain what it is, why it can be slow, or how to address that slowness.
Tldr: A looped transformer runs through the same layers multiple times instead of adding more layers.
It’s whether repeated computation can buy enough capability to make smaller models more useful—and whether runtimes can make that trade practical.
Parameter count tells you how much machinery you own. It doesn’t tell you how many times you use it.