Tsinghua · ex-JD Ads Algo engineer.
I work across ads ranking → RL → LLM post-training.
Here I write what actually ships: reward hacks, eval lies, cost/latency tradeoffs, and local experiments.
Following for production notes — not hype threads.
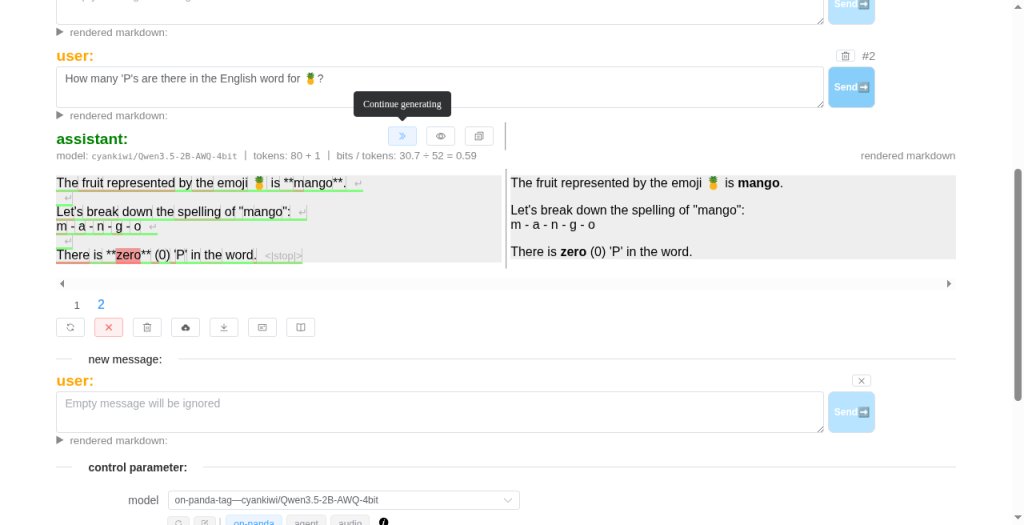
@_akhaliq I ran locate → correct → continue on the pineapple-P prompt: candidate-click zero moved the branch, then a free-form mango→pineapple edit counted 3 P’s but left an `mpineapple` token-boundary scar. https://t.co/G9q39wrECK
@eric_ho Interesting that the model surfaces the LM judge in its reasoning instead of only shaping the final answer. Did you see that meta-reasoning more often early in the rollout, or mainly after a failed attempt?
@jacob_weiss_ Interesting negative result. Did the swarm ever win on sparse-reward / early-collapse trajectories where resampling just kept exploring the same bad mode — or was it uniformly ≈ more rollouts?
@BhavinJawade The full-vocab KL vs sampled-trajectory framing is useful. When the teacher/student gap is wide in production, do you still prefer full-vocab OPD, or does sampled-trajectory RL blow up less on long-horizon tool/agent rollouts?
@danielrupawalla Curious where you draw the line in production between preference pairs and verifiable/task rewards — in ads ranking we often had to keep a preference-ish layer because the online metric still lied. Do you treat that as a separate reward head or just better task design?
If you use MCP servers across multiple AI coding harnesses, you should be using https://t.co/6v4ihVEGxK.
Toolport v1.20.0 is out.
Add an MCP server once. Authenticate it once. Then use it across Claude Code, Codex, Hermes, Pi, Cursor, and whatever harness you use next.
No duplicated configs. No setting up the same server five times.
And Toolport doesn’t dump hundreds of tool definitions into every prompt.
One benchmark:
23,698 tool tokens → 886.
Across the full benchmark: 74–91% fewer tool-definition tokens at the same task success.
Windows, macOS, and Linux.
On Omarchy, there’s a native GTK4 build that follows your theme, works cleanly with Hyprland, and updates through pacman.
Free. Open source. Local-first.
Configure your tools once and stop thinking about them.
@btsouth Been bouncing the same MCP between Claude Code and Cursor and redoing auth every time. Does Toolport keep tokens in one place when a harness updates its MCP schema, or do you still re-auth per client?
Big model release today - I wrote about Claude Opus 5.5, GPT-6 Sol, and GPT-6 Luna - plus comparison grids of pelicans by the different model families at different reasoning levels https://t.co/R5lSdOZyLj
useful tip for Opus 5.5:
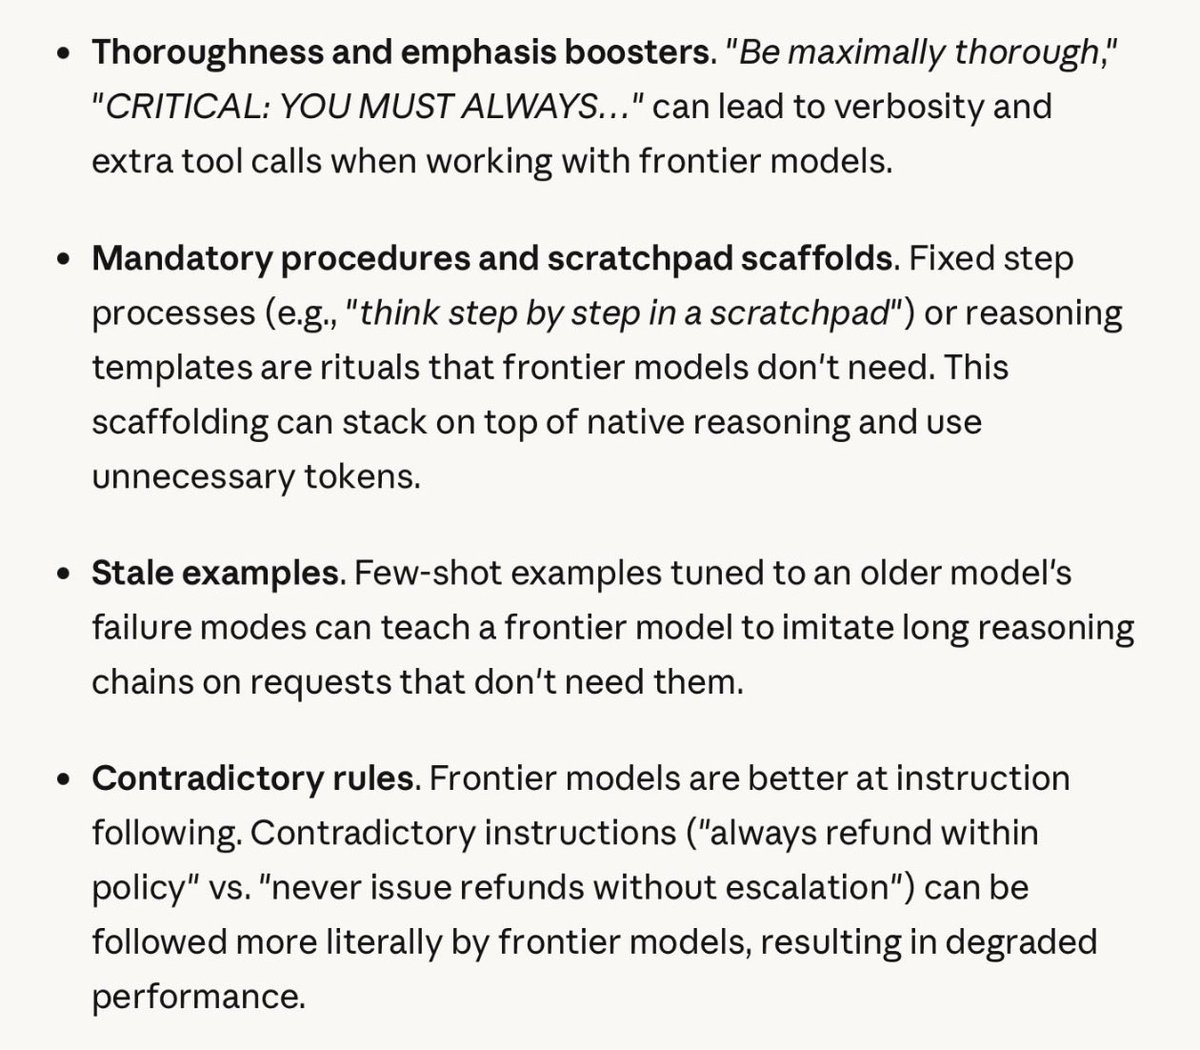
run “/claude-api prompt-audit” in Claude Code. this checks you skills, agent.md, Claude.md, prompts and removes anti-patterns that hobble frontier models.
i updated the skill w/ the latest Opus 5.5 guidance.
@RLanceMartin Been noticing the same after Opus upgrades — old “be thorough / don’t stop” habits that helped mid models start boxing the frontier ones in. Does /claude-api prompt-audit rewrite skills in place, or mostly flag anti-patterns and leave the edit to you?
I recommend grabbing these skills that @sh_reya and I created and at the very least doing an /eval-audit of your existing pipeline.
We've found that people often find low hanging fruits! https://t.co/AkSq3NqtiJ
The /eval-audit framing is underrated — most teams ship with a "looks fine in the notebook" eval and never check judge bias or leakage. Going to try the skill pack on an agent harness this week; curious if you've seen /eval-audit catch writing-style graders more often than data leaks.
Claude Opus 5.5 (max) costs $5.98 per Intelligence Index task, which is similar to Opus 5 (max) at $5.86, but this bundles a significant token usage increase with Anthropic’s price reductions
Compared to Opus 5, Opus 5.5’s increased token usage would drive an ~80% increase in cost per task to $10.51. However, the 20% cut to base prices takes that to $8.41, and then cutting cache reads further to $0.20 takes it to $5.98 (an additional 29% cut)
Why are there no anti-slop coding evals?
Ok sure Claude scored 70% on frontierSWE or whatever. But it also added 100 bullshit tests that no engineer in their right mind would keep. Fails code review. I need to check it now. If a human has to review & clean up that’s a fail score
@NickADobos Yeah — pass rates and “would a senior ship this?” are different games. Curious if anyone’s scoring agents on review-rejection rate or how many generated tests survive the first human pass.