How Anthropic's new results post would read without the PR:
Claude orchestrated open-source protein design models, PXDesign, RFdiffusion, Genie, BoltzGen, from a 30k-token expert prompt and 12,500 H100-hours of compute, and designed binders against 14 of 15 targets. Hit rates of 22–35% against a 10–15% baseline, where some of those tools already report similar numbers on their own.
The orchestration is genuinely impressive. But the open-source models did most of the lifting, and they came from the Baker lab, Columbia, MIT, ByteDance Seed, and most of them were already wet-lab validated before Claude touched them.
Which also sets the ceiling. All these generators share a single PDB-shaped training distribution, so calling four of them doesn't diversify away the blind spot, since they fail together. The targets that worked are the well-studied ones.
So the valid claim is that an agent can now drive this stack competently in the regime where the stack already works.
Instead, we got this announcement:
Speaking as an author whose work Anthropic distilled (which I'm fine with!) I do think it's awfully hypocritical for them to turn around and complain about distillation by others.
So proud of our security team! They caught, contained & publicly disclosed an attack unlike anything we've seen before, and did it at record speed.
Also massively grateful to @Zai_org: they shared GLM5.2 as open weights (for free!) with the world and it became a key part of our defense.
This is day one for cybersecurity in the age of agents & we're all learning that secrecy is not the answer & that all defenders (not just a few selected ones) everywhere need more powerful models without restrictions, especially open ones!
Anthropic: “Fable is an agentic coding superweapon, capable of developing cyber- and bio-weapons at unprecedented speed and scale. We cannot in good faith release it without guardrails.”
China: “lmao here’s Fable but open-source. Good fkn luck”
#CVPR2026 Can frontier LLMs write PhD-level 3D vision code?
We introduce GeoCodeBench, a benchmark that asks models to read real 3D geometric vision papers and implement core functions.
Best result so far: GPT-5 reaches only 36.6%.
This suggests that scientific coding in 3D vision remains far from solved.
Paper: https://t.co/tgl2LxNmFL
Project: https://t.co/GAm2ajFlAt
I spent almost 5 hours last night with different models to get a niche code working. I am so drained from the coding style of these models, that I am going to turn off model-assisted coding for a few weeks.
This is an unwise statement that can only make people confused about what LLMs can or cannot do. Let me tell you something: Math is NOT about solving this kind of ad hoc optimization problems. Yeah, by scraping available data and then clustering it, LLMs can sometimes solve some very minor math problems. It's an achievement, and I applaud you for that. But let's be honest: this is NOT the REAL Math. Not by 10,000 miles.
REAL Math is about concepts and ideas - things like "schemes" introduced by the great Alexander Grothendieck, who revolutionized algebraic geometry; the Atiyah-Singer Index Theorem; or the Langlands Program, tying together Number Theory, Analysis, Geometry, and Quantum Physics. That's the REAL Math. Can LLMs do that? Of course not.
So, please, STOP confusing people - especially, given the atrocious state of our math education.
LLMs give us great tools, which I appreciate very much. Useful stuff! Go ahead and use them AS TOOLS (just as we use calculators to crunch numbers or cameras to render portraits and landscapes), an enhancement of human abilities, and STOP pretending that LLMs are somehow capable of replicating everything that human beings can do.
In this one area, mathematics, LLMs are no match to human mathematicians. Period. Not to mention many other areas.
Calling on my friend @ericweinstein and @GaryMarcus, who has been one of the few sane expert voices on these matters lately. 🙏
h/t @hellheff
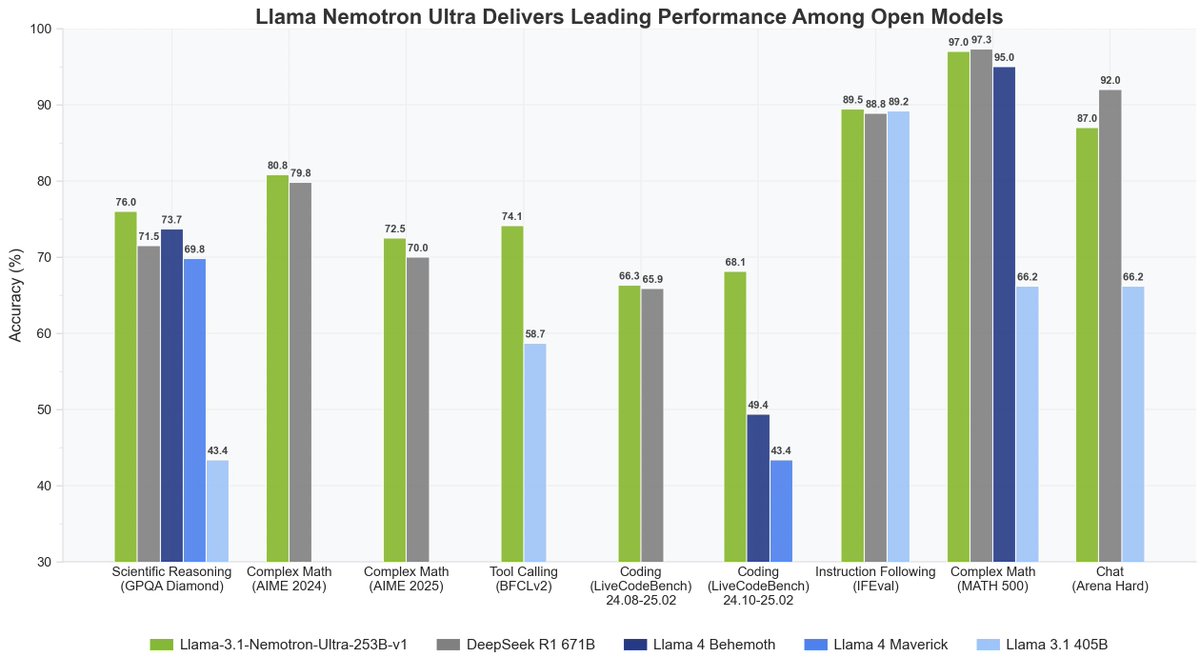
We are excited to release Llama-Nemotron-Ultra! This is a reasoning ON/OFF, dense 253B model. Open weights and post-training data. https://t.co/dCTacylBR8 We started with llama-405B, changed it via NAS pruning then followed by reasoning-focused post-training: SFT + RL in FP8.
I wanted to add a 'Login with Github' option to my website. Didn't work right away and decided that I had to break my rule and just push through. 10+ hours later all my LLM calls are now mocked, half my website features seem to be missing and my login still isn't working
Very informative discussion with Mark Kachelrieß on the scatter correction in CBCT at #SPIEMedicalImaging. Stop by my poster if you want to know more about our work at @Planmeca Research (Finland) with @simosarkka on Scatter correction. @SPIEtweets
Open source AI foundation models will wipe out closed and proprietary AI models for the same reason Wikipedia wiped out generalist commercial encyclopedia: crowd-sourced human contributions to open platforms can cater to a high diversity of interests, cultures, and languages.
Very strange anti-openness argument from Microsoft President Brad Smith in response to my open source AI platform advocacy.
I thought Microsoft had long abandoned its anti open source stance.
Doesn't Azure run on Linux?