

Top Tweets for #bentoML


📸 Live from #Ai4 2025 in Las Vegas!
🍱 The Bento team is here at Booth #346, showing how we help enterprises run, scale, and optimize inference for mission-critical AI workloads.
Come say hi 👋 If you’re here, tag us in your photos!
@Ai4Conferences #AIInference #BentoML



Just wrapped up my talks at KubeCon + CloudNativeCon Hong Kong and KubeCon Japan!
Great to connect with the cloud native community and share some ideas. Thanks to everyone who joined! 🙌
#KubeCon #CNCF #CloudNative #Kubernetes


#BentoFriday 🍱 — Add a Web UI with @Gradio
Real-world #AI apps don’t just need a model. They need interfaces users can interact with.
But building a custom frontend is time-consuming and managing it separately from your backend adds unnecessary complexity. 😵💫
With #BentoML, you can mount a #Gradio UI directly into your AI service — all in Python.
✅ Build a slick web UI with Gradio
✅ Connect it to a scalable backend powered by BentoML
✅ Serve both APIs and UI in one deployment
✅ Efficient #LLM inference, multi-model pipelines, async queues and adaptive batching
✅ Auto-package into a Docker image with built-in metrics and health checks
✅ Deploy to #BentoCloud with optimized model loading and fast autoscaling
📚 Docs: https://t.co/aH00sEPf7o
Here’s what it looks like 👇

🚀 #Magistral, @MistralAI’s first reasoning model, is here and now deployable with #BentoML!
This release features two variants:
- Magistral Small: 24B parameter open-source version
- Magistral Medium: Enterprise-grade, high-performance version
Highlights of Magistral Small:
🔧 Built on Mistral Small 3.1
🧠 Purpose-built for step-by-step, transparent reasoning
🔬 Optimized for legal, finance, healthcare, engineering, and creative applications
⚖️ High performance: AIME24 70.68%, GPQA 68.18%
📈 Up to 128k context window (best performance under 40k)
🌍 High-fidelity multilingual reasoning
🔓 Apache 2.0 license
👉 Customize your inference with BentoML: https://t.co/cmVYhBdWB2
👉 Prebuilt Bento available on #BentoCloud. See the demo below ⬇️
#OpenSource #LLM #ReasoningModel #AI
👀 Update on DeepSeek-R1-0528 https://t.co/2tqLlUdcDp
🧠 Built on V3 Base
📈 Major reasoning improvements
🛡️ Reduced hallucination
⚙️ Function calling + JSON output
📦 Distilled Qwen3-8B beats much larger models
📄 Still MIT
See our updated blog ⬇️
#AI #LLM #BentoML #OpenSource

#BentoFriday 🍱 — Inference Context with 𝘣𝘦𝘯𝘵𝘰𝘮𝘭.𝘊𝘰𝘯𝘵𝘦𝘹𝘵
Building #AI/ML APIs isn’t just about calling a model. You need a clean, reliable way to customize your inference service.
𝘣𝘦𝘯𝘵𝘰𝘮𝘭.𝘊𝘰𝘯𝘵𝘦𝘹𝘵 is one of those abstractions in #BentoML that gives the control you need:
✅ Access request headers
✅ Set response headers, cookies, or status codes
✅ Use a temp directory 𝘤𝘵𝘹.𝘵𝘦𝘮𝘱_𝘥𝘪𝘳 to write files
✅ Track per-worker state with 𝘤𝘵𝘹.𝘴𝘵𝘢𝘵𝘦
All that while keeping your logic clean and readable.
Here’s an example serving the FLUX.1-schnell model, logging metadata, customizing the response, and saving the generated image 👇
📖 Learn more: https://t.co/xCVImahnC5

🚀 Build CI/CD pipelines for #AI services with #BentoML + #GitHubActions
Automate everything with pipelines that:
✅ Deploy services to #BentoCloud
✅ Trigger on code or deployment config changes
✅ Wait until the service is ready
✅ Run test inference
📘 Step-by-step guide: https://t.co/ViQA5w3vs1

#BentoFriday 🍱 — Lifecycle Hooks in #BentoML
When deploying real-world #AI services, the work doesn’t end at inference. You also need to manage everything that happens before, during, and after a request hits your model.
In practice, that often means:
🔧 Setting up global resources at startup
📚 Loading databases or caches
🩺 Checking service health and readiness
🧹 Releasing memory and cleaning up connections
Without a clean structure, you may end up with messy boilerplate, missed init logic, painful resource leaks, and hard-to-trace bugs. ⏳ 𝗪𝗵𝗮𝘁'𝘀 𝘄𝗼𝗿𝘀𝗲, 𝗶𝘁 𝘁𝗮𝗸𝗲𝘀 𝘁𝗶𝗺𝗲 𝘁𝗼 𝗴𝗲𝘁 𝗿𝗶𝗴𝗵𝘁.
That’s why BentoML makes it simple with lifecycle hooks. Just add a few decorators:
✅ @𝘣𝘦𝘯𝘵𝘰𝘮𝘭.𝘰𝘯_𝘥𝘦𝘱𝘭𝘰𝘺𝘮𝘦𝘯𝘵: One-time setup before spawning workers
✅ @𝘣𝘦𝘯𝘵𝘰𝘮𝘭.𝘰𝘯_𝘴𝘵𝘢𝘳𝘵𝘶𝘱: Per-worker initialization (sync/async supported)
✅ @𝘣𝘦𝘯𝘵𝘰𝘮𝘭.𝘰𝘯_𝘴𝘩𝘶𝘵𝘥𝘰𝘸𝘯: Graceful cleanup during shutdown
✅ __𝘪𝘴_𝘢𝘭𝘪𝘷𝘦__ & __𝘪𝘴_𝘳𝘦𝘢𝘥𝘺__: Health & readiness checks for /𝘭𝘪𝘷𝘦𝘻 and /𝘳𝘦𝘢𝘥𝘺𝘻
Build cleaner and safer AI services with just a few lines of code. Learn more: https://t.co/G9epaMU101
Here’s a simple example:

Tasks like image/video generation or complex agentic workflows can take time.
With #BentoML’s task API, you can handle them asynchronously — fire-and-forget, and let users retrieve results later. 🔁
In this real-world example, we build a #LangGraph agent using Ministral 8B, capable of searching the web via DuckDuckGo 🌐
The query runs in the background with a BentoML task endpoint — no blocking, just smooth UX.
📖 Read the blog post https://t.co/rhXptGUcgU
🎥 Watch the demo 👇
#LLM #AIAgents #OpenSource @langchain
Learn how #Yext cut time-to-market & compute costs by re-platforming #AI Inference on #BentoML:
Key wins:
✅ 𝟯× 𝗳𝗮𝘀𝘁𝗲𝗿 model delivery (70 % less dev time)
✅ 𝗨𝗽 𝘁𝗼 𝟴𝟬 % 𝗚𝗣𝗨 𝘀𝗮𝘃𝗶𝗻𝗴𝘀 with cloud‑agnostic autoscaling
✅ 𝟮× 𝗺𝗼𝗿𝗲 𝗺𝗼𝗱𝗲𝗹𝘀 𝘀𝗵𝗶𝗽𝗽𝗲𝗱 — 150+ AI services running in production today
“𝘞𝘩𝘢𝘵 𝘶𝘴𝘦𝘥 𝘵𝘰 𝘵𝘢𝘬𝘦 𝘥𝘢𝘺𝘴 𝘯𝘰𝘸 𝘵𝘢𝘬𝘦𝘴 𝘫𝘶𝘴𝘵 𝘩𝘰𝘶𝘳𝘴. 𝘉𝘦𝘯𝘵𝘰𝘔𝘓 𝘭𝘦𝘵𝘴 𝘋𝘢𝘵𝘢 𝘚𝘤𝘪𝘦𝘯𝘤𝘦 & 𝘌𝘯𝘨𝘪𝘯𝘦𝘦𝘳𝘪𝘯𝘨 𝘮𝘰𝘷𝘦 𝘪𝘯𝘥𝘦𝘱𝘦𝘯𝘥𝘦𝘯𝘵𝘭𝘺 𝘢𝘯𝘥 𝘴𝘩𝘪𝘱 𝘸𝘪𝘵𝘩 𝘪𝘯𝘤𝘳𝘦𝘥𝘪𝘣𝘭𝘦 𝘦𝘧𝘧𝘪𝘤𝘪𝘦𝘯𝘤𝘺.” — Michael Misiewicz, Director of Data Science, @yext
When enterprises scale AI, rigid pipelines, costly GPUs, and cross‑team bottlenecks can stall innovation. Yext solved all three with BentoML’s unified, multi‑cloud inference platform.
Read the full story to see how the BentoML platform makes AI inference management effortless so your teams can ship AI faster and stay focused on innovation.👇
🔗 https://t.co/gOlh5DkCTb
#GenAI #LLM #InferencePlatform
#BentoFriday 🍱 — Distributed Services in #BentoML
#AI deployments are going distributed. Some examples:
🔧 Disaggregated #LLM serving
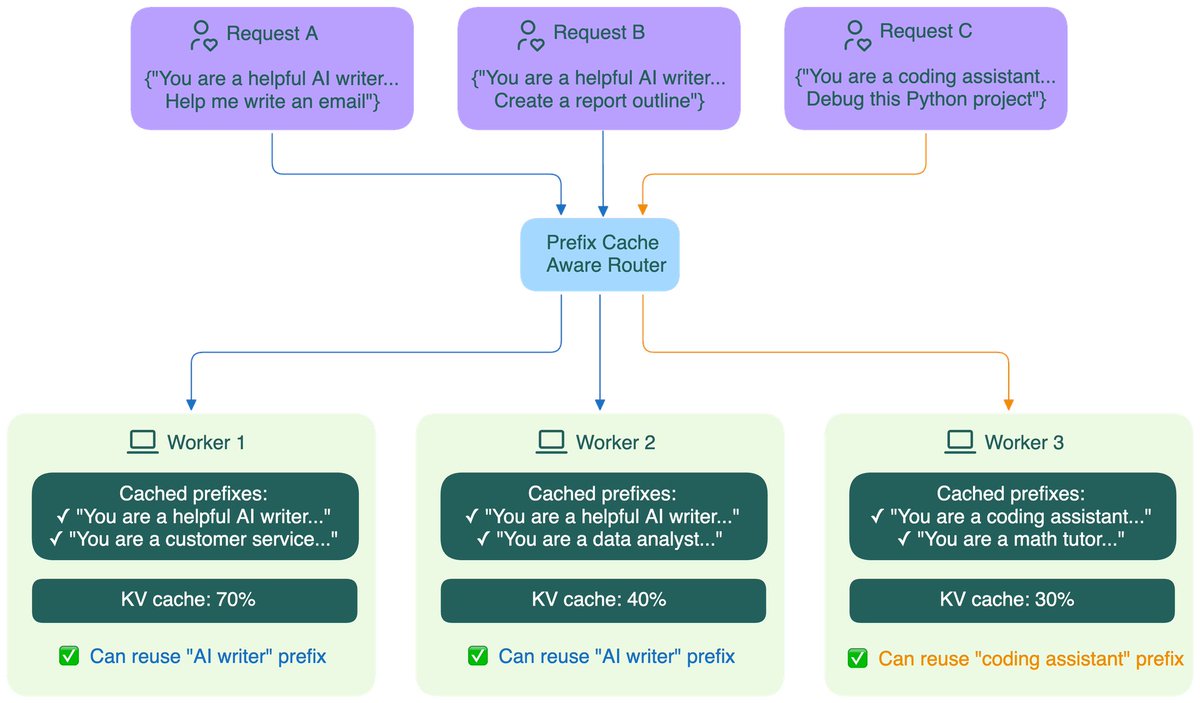
🔍 KV-aware LLM routing
🧠 Multi-model Computer Vision pipelines
🔐 LLM safety & moderation layers
🔁 #RAG pipelines
In these systems, components are tidily coupled. Running them all on a single node (heterogeneous CPU/GPU/IO compute) often leads to compute waste and reduced throughput. To optimize compute utilization and latency, you often want to break them into individual components, leading to complex micro-services architecture.
What if you could develop such distributed application all in one Python file, and easily orchestrate it across distributed infrastructure for evaluation and deployment?
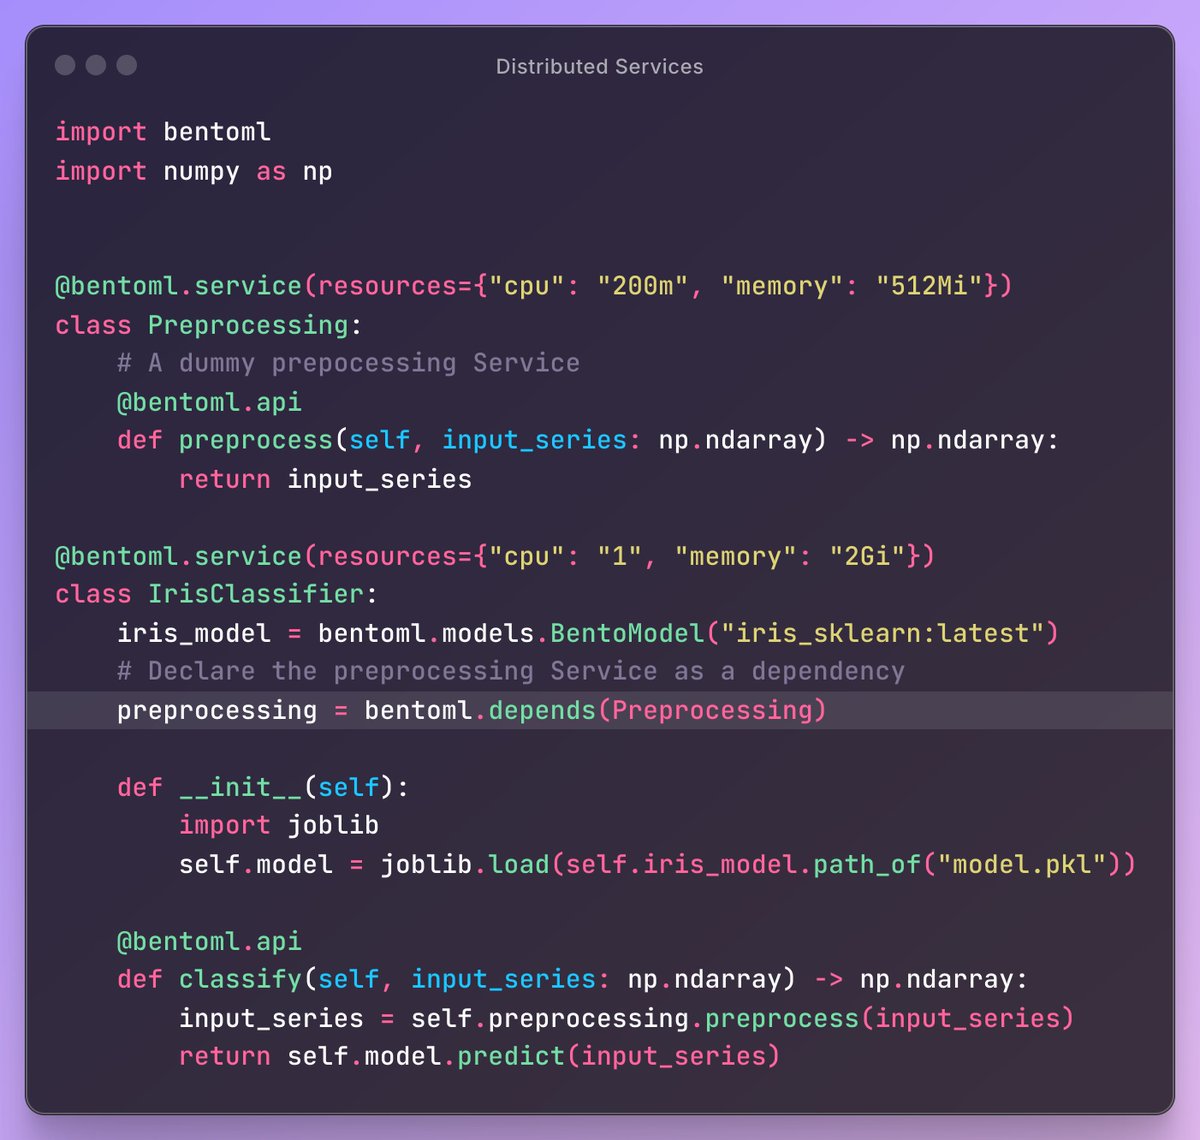
That’s what 𝗕𝗲𝗻𝘁𝗼𝗠𝗟 𝗗𝗶𝘀𝘁𝗿𝗶𝗯𝘂𝘁𝗲𝗱 𝗦𝗲𝗿𝘃𝗶𝗰𝗲𝘀 are built for:
✅ Use 𝘣𝘦𝘯𝘵𝘰𝘮𝘭.𝘥𝘦𝘱𝘦𝘯𝘥𝘴() to wire them together
✅ Each component with their own environment, scaling strategy, models and hardware specifications (CPU/GPU)
✅ Call dependent service APIs as if they were local Python functions
✅ Automatic service discovery & routing
✅ Simplified control over concurrency, throughput, and resource utilization
📚 Learn more: https://t.co/0lYza2E1sq

A critical RCE vulnerability (CVE-2025-27520) has been found in BentoML. Affects versions 1.3.8–1.4.2 - Update to v1.4.3 ASAP.
Read: https://t.co/mTFrjBSghr
#CyberSecurity #BentoML #Vulnerability #AI #Python
#BentoFriday 🍱 — BentoCloud Unified Inference Platform
Developers love #BentoML for its ease of building scalable #AI inference services and distributed real-time AI applications. With #BentoCloud, we are taking this vision of simplifying AI inference operations further to enterprises.
Learn how you can one-click deploy #Llama4 to your AWS/GCP account via BentoCloud, and unlock the path to advanced inference setups and customizations:
🍱 Various pre-built #Bentos with the latest models like Llama 4
⌨️ Custom APIs, inference setups, business logic, and more
🔁 Autoscaling with fast cold starts & scale-to-zero
📊 Real-time logs & dashboards for full observability
🔒 Full control with Bring Your Own Cloud (#BYOC) and on-prem support
…and many more!
#OpenSource #BentoML #BentoCloud #MachineLearning
Looking to build semantic search, #RAG, or recommendation systems with 𝗲𝗺𝗯𝗲𝗱𝗱𝗶𝗻𝗴 𝗺𝗼𝗱𝗲𝗹𝘀?
#BentoML makes it easy to 𝘀𝗲𝗿𝘃𝗲 𝗮𝗻𝗱 𝘀𝗰𝗮𝗹𝗲 𝗮𝗻𝘆 𝗼𝗽𝗲𝗻-𝘀𝗼𝘂𝗿𝗰𝗲 𝗲𝗺𝗯𝗲𝗱𝗱𝗶𝗻𝗴 𝗺𝗼𝗱𝗲𝗹:
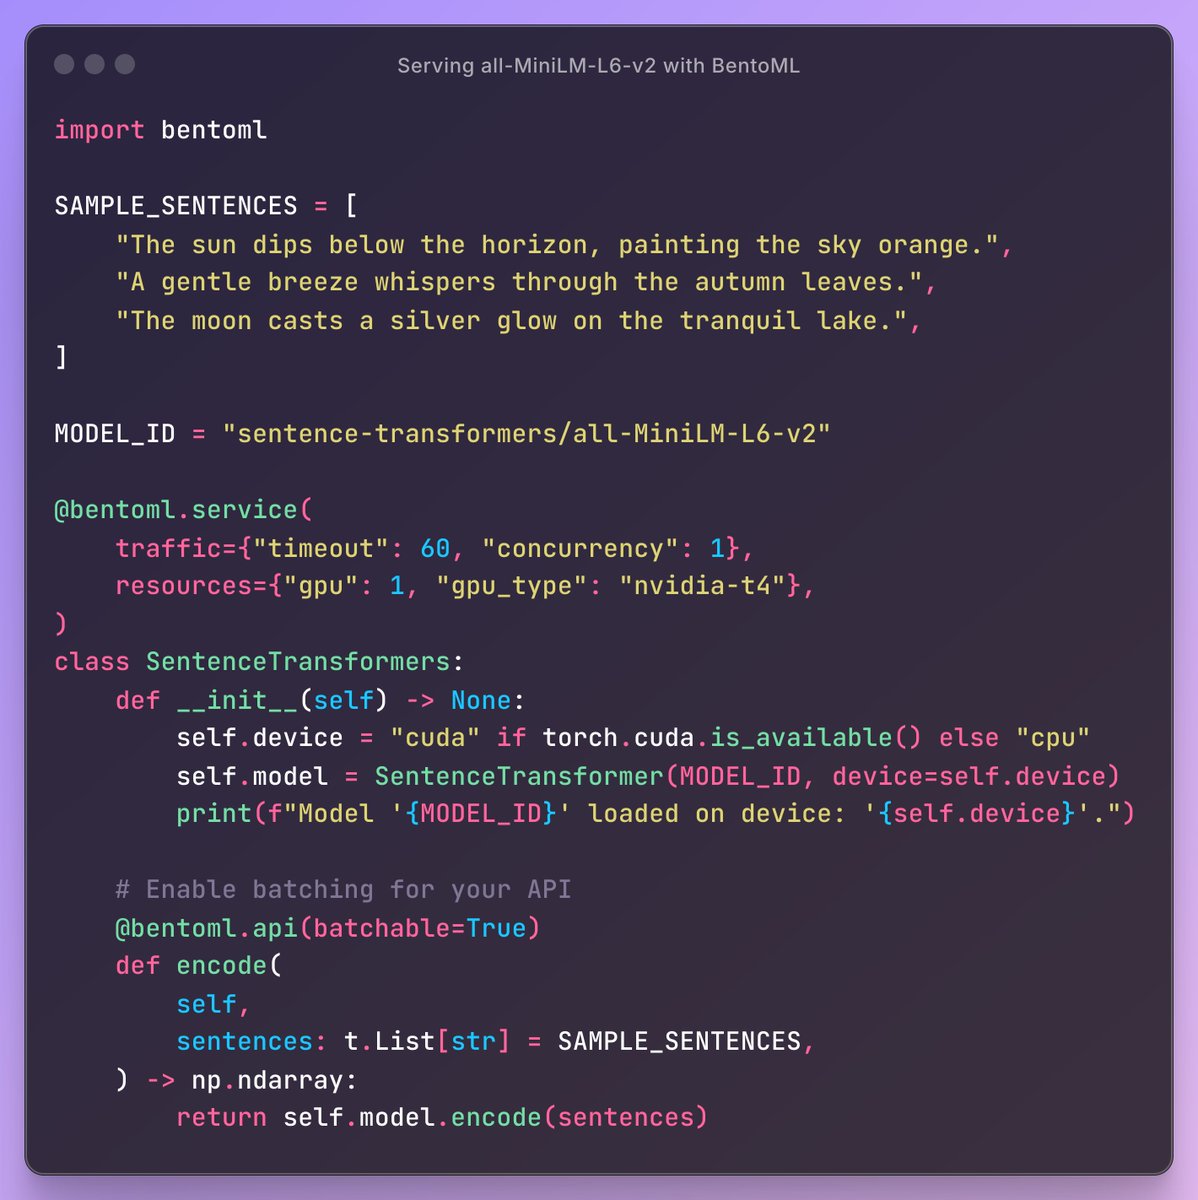
✅ Batching requests for embedding generation
✅ Batch size & window adjusted based on traffic
✅ Custom logic around embedding pipeline
✅ Fast autoscaling
✅ Easy integration with #LLMs and other services
✅ Higher throughput & lower latency
📖 Check out this blog post to explore top open-source embedding models: https://t.co/J26WVIs2fU
📧 Contact us if you have questions of building AI systems with #EmbeddingModels: https://t.co/HUo5Mb5ZQ3
👀 Here’s how to serve an embedding model 𝘢𝘭𝘭-𝘔𝘪𝘯𝘪𝘓𝘔-𝘓6-𝘷2 with BentoML's adaptive batching enabled 👇
🔍 Read our guide to take your #ML models from experiments to production with @MLflow & #BentoML 👉 https://t.co/aPTRM67ZJ9
✅ Log & track models with #MLflow
✅ Serve with BentoML
✅ Enforce input validation & adaptive batching
✅ Standardize ML workflows for large teams
Turn your ML models into production-ready APIs today 🚀
#AI #OpenSource #MachineLearning #MLOps
Want to deploy #DeepSeek privately? We've got you covered!
✅ Easy self-hosting with #OpenLLM https://t.co/PVhLM89LSc
🛠️ Custom logic? Use #BentoML + #vLLM https://t.co/YeawhsoREX
🔥 Support DeepSeek R1, V3, and all distilled versions
☁️ Deploy to #BentoCloud in one command for secure, private use ⬇️
#AI #OpenSource #LLM
Building Voice AI Applications just got a whole lot easier! 🎯 https://t.co/wMP1gEK98u
Gone are the days of wrestling with #STT, #TTS, streaming, and #LLMs! We've worked with @twilio to show you how to create a powerful voice #AI app using #TwilioConversationRelay and #BentoML!
In this article, you’ll learn to build a system that:
✅ Handles real-time conversations via a Twilio phone number
✅ Supports dynamic interruptions
✅ Offers streaming responses with minimal latency
✅ Eliminates the complexity of setting up a WebSocket server
✅ Allows easy deployment of an open-source LLM and code customization with BentoML
✅ Autoscales with traffic
Special thanks to the Twilio team for the collaboration! Full guide 👇
#VoiceAI #OpenSource #MachineLearning #AIAgent
Last Seen Hashtags on Sotwe
ts facetime
Seen from United States
JAV
Seen from United States
mulanvuitton
Seen from Netherlands
StashdiveSaturday
Seen from United States
xxprettyfaacee
tamilshemale
Seen from India
audrisummer
Seen from Canada
omegle video**
Seen from Turkey
勾引直男
Seen from Malaysia
snapchat
Seen from United States
Most Popular Users

Elon Musk 
@elonmusk
241M followers

Barack Obama
@barackobama
118.8M followers

Cristiano Ronaldo
@cristiano
114.5M followers

Donald J. Trump
@realdonaldtrump
111.9M followers

Narendra Modi
@narendramodi
107M followers

Rihanna
@rihanna
98.7M followers

NASA
@nasa
92.2M followers

Justin Bieber
@justinbieber
91.8M followers

KATY PERRY
@katyperry
90M followers

Taylor Swift
@taylorswift13
84M followers

Lady Gaga
@ladygaga
75.5M followers

Virat Kohli
@imvkohli
73.4M followers

Kim Kardashian
@kimkardashian
70.8M followers

YouTube
@youtube
68.7M followers

Neymar Jr
@neymarjr
66.4M followers

Bill Gates
@billgates
65.2M followers

Selena Gomez
@selenagomez
63.1M followers

The Ellen Show
@theellenshow
62.2M followers

CNN
@cnn
61.7M followers

X
@x
60.6M followers