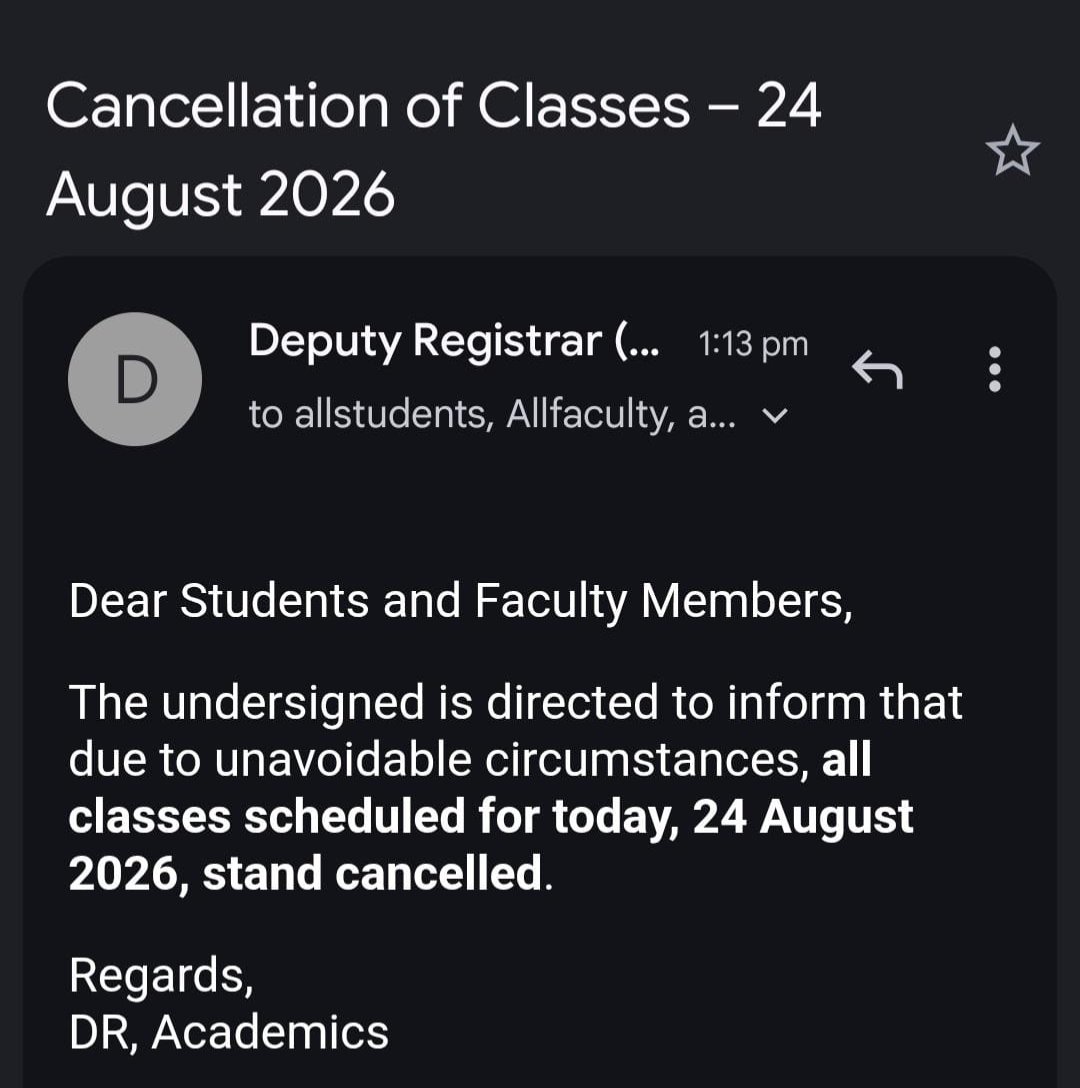
IIT Delhi Director has signed the receipt of the demands presented by students. The administration has been asked to communicate its decision on all demands by EOD. All classes at IIT Delhi have been suspended for 24 August.
#IITDelhi#StudentProtest
Our paper “IndicSafeEval: Safety Robustness of Large Language Models under Multilingual Persuasive Jailbreak Attacks” has been accepted to EMNLP 2026 Findings!
Grateful to my co-authors Mamta Mamta, Deeksha Varshney, Oana Cocarascu & Asif Ekbal! 🙌
#EMNLP2026#LLMSafety
END OF DAY 16 OF #CLIMATEFAST
I continue to feel drained & lower & lower in energy...
Hence a final appeal to the Prime Minister of India.
Sharing the unfair treatment meted out to people of Ladakh on Safeguards under 6th Schedule of constitution.
4 years of dilly dallying and a No in the end... after making clear promises in 2 elections in written manifestos
#SaveLadakh #SaveHimalayas #SaveGlaciers #6thSchedule
Recently saw the video titled "How @zomato improved its search by identifying intent using NLP" by @arpit_bhayani and I tried to think why this particular design choice was made by Zomato.
Zomato's search system identifies three primary entities:
1. Dish+Dish
2. Dish+Restaurant
3. Dish/Restaurant + place/others
Zomato uses Word2Vec with BPE(Byte Pair Encoding) followed by BiLSTM+CRF to do NER(named entity recognition).
That's a pretty heavy system. Also, CRF requires a lot of labeled data, which is a problem.
I tried to solve this problem in a different way.
What if we simply used BERT with BPE and did unsupervised clustering of each word? There are language-agnostic BERTs so we wouldn't have to worry about mixed queries like "Pizza from Dominos" or "Dominos ka pizza". Also, since the number of tags isn't many, this approach would work
1. Because of BERT's capability to generate well-defined embeddings.
2. We wouldn't need any labeled data! Totally unsupervised.
For instance, we could simply run BERT+BPE on "dominos ka pizza" and get tags, "Restaurant" + "Food" or "Chhole Bhature" and get tags "Food"+ "Food"
But there's a catch.
Consider this case "Best Chinese near Thai Café". The user is looking for a Chinese Restaurant near a place.
If we used BERT(unsupervised) on each word, we would get tags as
"Chinese"-> Food
"near" -> place
"Thai" -> Food and "Cafe" -> Restaurant.
Which is incorrect. That's why need CRF. CRF is used to model the relationship between output labels(generally used in information extraction). CRF can handle such complex queries and model conditional distribution among tags.
But why does Zomato still use word2vec with BPE and not BERT with BPE, given that BERT outperforms every other benchmark?
The answer is latency. word2vec is relatively faster while BERT is heavy and milliseconds in delays in result fetch can cause orders to get dropped.
PS: do correct me wherever my analysis is wrong.
@motorolaindia This feature is turned on from settings..but when I go for turning on the flash by shaking hand, not working I am facing this issue from last month
Save the date!
102nd Convocation of #BHU
Date: 10.12.2022
Venue: Swatantrata Bhawan
काशी हिन्दू विश्वविद्यालय का 102वां दीक्षांत समारोह
तारीखः 10.12.2022
स्थानः स्वतंत्रता भवन
#BHUConvocation#Convocation#BanarasHinduUniversity