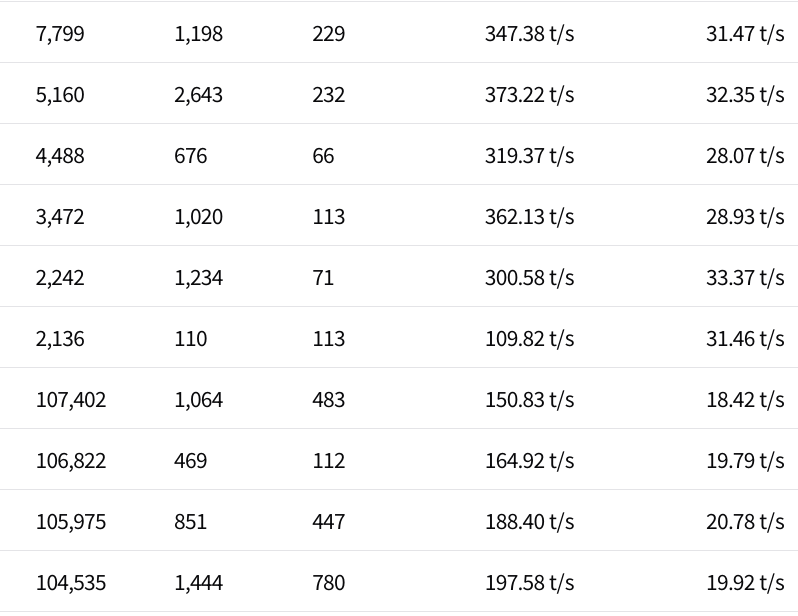
Qwen 3.8 flash is truly impressive, and llama.cpp has been rapidly getting better and better at processing it
columns are: pre-existing prompt, new prompt, generated, input tok/s, output tok/s
This is on my laptop (strix halo). I think we're very close to the point where you can just use local models for a large share of tasks, and for anything more advanced, workflows like "use your local model to orchestrate queries to powerful models so your queries don't leak your personal information" actually become viable.
@thsottiaux They represent only a small group of users. However, this could very well impact the majority of users who use the service normally, including myself.