Is model scaling the only source of agent improvement?
We @henryqin1997@YaxinLu1997@VITAGroupUT@VictorKaiWang1 are glad to share our work: We reach 95.3% Raw Accuracy, or a $15 Frontier Run (88.8% with DeepSeek-v4-Flash, matching GPT-5.6 Sol Max), on Terminal-Bench 2.1 via Harness Scaling.
Human effort -> Non scalable ❌
Agent direction? Local optimization ❌
Human direction + agent action = better workflow control✅
StateM:
1. Open-source model + StateM -> Close-source frontier, everyone can try!
2. Training free, significantly improve frontier agents.
3. Zero-transfer-cost on same family of agents. [1/8]🧵
📄https://t.co/GjM1VOzWUN
🌐 https://t.co/KapEB3kjXr
Interesting work!
We are actually doing so (let agent improve agent) on Terminal-Bench 2.1, and we found agents are not smart enough yet. They currently lack the ability to do deep failure attribution and conduct control at correct abstraction level. Therefore, we are actually doing semi-self-improving with a human-agent collaborative way. If interested, can find more details at https://t.co/AODqVEAyc9.
Is model scaling the only source of agent improvement?
We @henryqin1997@YaxinLu1997@VITAGroupUT@VictorKaiWang1 are glad to share our work: We reach 95.3% Raw Accuracy, or a $15 Frontier Run (88.8% with DeepSeek-v4-Flash, matching GPT-5.6 Sol Max), on Terminal-Bench 2.1 via Harness Scaling.
Human effort -> Non scalable ❌
Agent direction? Local optimization ❌
Human direction + agent action = better workflow control✅
StateM:
1. Open-source model + StateM -> Close-source frontier, everyone can try!
2. Training free, significantly improve frontier agents.
3. Zero-transfer-cost on same family of agents. [1/8]🧵
📄https://t.co/GjM1VOzWUN
🌐 https://t.co/KapEB3kjXr
An orthogonal scaling axis to Stanford/Berkeley’s LLM-as-a-Verifier:
Verifier scaling improves selection over candidate trajectories.
StateM makes execution explicit and stateful: each state defines the context, contract, transition checks, persistence, and recovery.
Two axes
@VictorKaiWang1@jietang@jietang Hi Prof Tang, we initially plan to adapt StateM runbook on GLM. I bought two month GLM code plan, but the API was not stable enough. Could you help with this so we can measure on GLM-5.3?
@jackyk02 Still feel interesting after reading your work yesterday. Our two works are complementary, with LLM-as-a-Verifier scaling in width and StateM scaling in depth. What if we distill the verifications into a StateM runbook? I made a comparison here, FYI.
Hi Lucas, thanks for the valuable feedback! Would like to take an update. For counter, I will consider it as an optional schema. For fail-closed config, I will do a quick fix. For goto --dry-run, let me check. Would appreciate if you could share the runbook + notes in pull request in the git repo! Thanks!
Is model scaling the only source of agent improvement?
We @henryqin1997@YaxinLu1997@VITAGroupUT@VictorKaiWang1 are glad to share our work: We reach 95.3% Raw Accuracy, or a $15 Frontier Run (88.8% with DeepSeek-v4-Flash, matching GPT-5.6 Sol Max), on Terminal-Bench 2.1 via Harness Scaling.
Human effort -> Non scalable ❌
Agent direction? Local optimization ❌
Human direction + agent action = better workflow control✅
StateM:
1. Open-source model + StateM -> Close-source frontier, everyone can try!
2. Training free, significantly improve frontier agents.
3. Zero-transfer-cost on same family of agents. [1/8]🧵
📄https://t.co/GjM1VOzWUN
🌐 https://t.co/KapEB3kjXr
We now release the StateM runbook to achieve 88.8% on Terminal-Bench-2.1 at https://t.co/sDKL5an2yc! Everyone can try!
Note: it was adapted from the 95.3% GPT runbook, so...
Is model scaling the only source of agent improvement?
We @henryqin1997@YaxinLu1997@VITAGroupUT@VictorKaiWang1 are glad to share our work: We reach 95.3% Raw Accuracy, or a $15 Frontier Run (88.8% with DeepSeek-v4-Flash, matching GPT-5.6 Sol Max), on Terminal-Bench 2.1 via Harness Scaling.
Human effort -> Non scalable ❌
Agent direction? Local optimization ❌
Human direction + agent action = better workflow control✅
StateM:
1. Open-source model + StateM -> Close-source frontier, everyone can try!
2. Training free, significantly improve frontier agents.
3. Zero-transfer-cost on same family of agents. [1/8]🧵
📄https://t.co/GjM1VOzWUN
🌐 https://t.co/KapEB3kjXr
Interesting point on the growing risks with more capable models.
As agents get stronger, environment design and execution control seem increasingly critical.
Have you considered harness scaling as a complementary axis — not just for safer training/evaluation environments, but also for more reliable long-horizon agent applications?
We’ve been exploring this direction here:
https://t.co/AODqVEAyc9
Is model scaling the only source of agent improvement?
We @henryqin1997@YaxinLu1997@VITAGroupUT@VictorKaiWang1 are glad to share our work: We reach 95.3% Raw Accuracy, or a $15 Frontier Run (88.8% with DeepSeek-v4-Flash, matching GPT-5.6 Sol Max), on Terminal-Bench 2.1 via Harness Scaling.
Human effort -> Non scalable ❌
Agent direction? Local optimization ❌
Human direction + agent action = better workflow control✅
StateM:
1. Open-source model + StateM -> Close-source frontier, everyone can try!
2. Training free, significantly improve frontier agents.
3. Zero-transfer-cost on same family of agents. [1/8]🧵
📄https://t.co/GjM1VOzWUN
🌐 https://t.co/KapEB3kjXr
Interesting work on the expanded CoT monitoring!
One question: does token-level monitoring risk being too fine-grained? It seems challenging to align a global task-level intention with per-token classification.
We’ve been exploring state-level explicit control recently (durable states + checked transitions + state awareness):
https://t.co/AODqVEAyc9
Curious if you think a state-level classification objective with stateful control, or action level classification with state awareness, might be a better-aligned alternative, or complementary?
Is model scaling the only source of agent improvement?
We @henryqin1997@YaxinLu1997@VITAGroupUT@VictorKaiWang1 are glad to share our work: We reach 95.3% Raw Accuracy, or a $15 Frontier Run (88.8% with DeepSeek-v4-Flash, matching GPT-5.6 Sol Max), on Terminal-Bench 2.1 via Harness Scaling.
Human effort -> Non scalable ❌
Agent direction? Local optimization ❌
Human direction + agent action = better workflow control✅
StateM:
1. Open-source model + StateM -> Close-source frontier, everyone can try!
2. Training free, significantly improve frontier agents.
3. Zero-transfer-cost on same family of agents. [1/8]🧵
📄https://t.co/GjM1VOzWUN
🌐 https://t.co/KapEB3kjXr
Glad to see a concurrent and complementary agent scaling work with our work StateM! One can directly distill the correct verification into StateM runbook: https://t.co/X68rlH3uWj
I feel like:
Scaling self-verification/agent team: scaling agent width
StateM: scaling agent depth (with search and self-distill)
Is model scaling the only source of agent improvement?
We @henryqin1997@YaxinLu1997@VITAGroupUT@VictorKaiWang1 are glad to share our work: We reach 95.3% Raw Accuracy, or a $15 Frontier Run (88.8% with DeepSeek-v4-Flash, matching GPT-5.6 Sol Max), on Terminal-Bench 2.1 via Harness Scaling.
Human effort -> Non scalable ❌
Agent direction? Local optimization ❌
Human direction + agent action = better workflow control✅
StateM:
1. Open-source model + StateM -> Close-source frontier, everyone can try!
2. Training free, significantly improve frontier agents.
3. Zero-transfer-cost on same family of agents. [1/8]🧵
📄https://t.co/GjM1VOzWUN
🌐 https://t.co/KapEB3kjXr
@Lucastcaraujo34@YaxinLu1997@VITAGroupUT@VictorKaiWang1 In general, unrecoverable handoffs should be checked carefully before entering next steps. And other things could be figured out during developing and eval on a separate golden set
Glad to see a concurrent and complementary work with StateM! One can directly distill the correct verification into StateM runbook: https://t.co/X68rlH3uWj
I feel like:
Scaling self-verification/agent team: scaling agent width
StateM: scaling agent depth (with search and self-distill)
For StateM, with correct failure analysis and direction, agents could solve 0-pass very-long-horizon questions. Width scaling may speed up intermediate step search.
Will soon release a multi-agent version of StateM!
@VictorKaiWang1@VITAGroupUT@Richard91316073
Scaling self-verification with DeepSeek V4 Flash beats Claude Fable 5 on Terminal-Bench 2.1, while being 11x cheaper 💰
As open-source models become more capable, they can now generate large numbers of high-quality candidate solutions and verify their own outputs at very low cost.
For example, we find that sampling just 5 solutions with DeepSeek V4 Flash and ranking them using the same model with LLM-as-a-Verifier can lead to a significant boost in accuracy (79% → 88%), outperforming closed frontier models on Terminal-Bench.
Try it out today: https://t.co/UhudjKDaYI
More on verification scaling in my previous post.
What is learned into the StateM control layer? Here are the mechanisms.
We also found:
- task ambiguity could lead to task-tuned parameters (for video frame extraction precision requirement)
- wrong verifier feedback could lead to wrong practice learned (on DNA tasks, Terminal-Bench 3.2 is using leftmost insertion as verfier only). [7/8]🧵
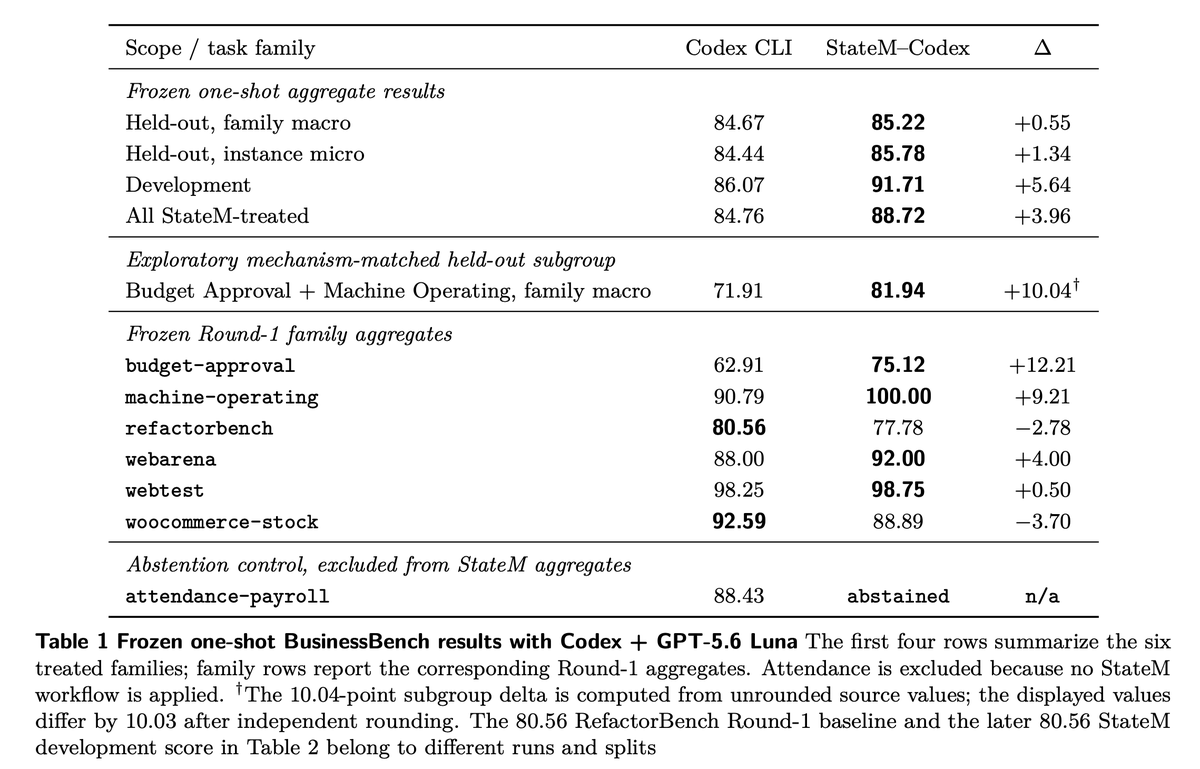
As Terminal-Bench 2.1 doesn't has a developing set and test set split, we further test it on a BusinessBench with manually splitting instances.
The result is suggesting: harness scaling is generalizable, while the generalization follows mechanism match.
We thank @Richard91316073 and Mengxuan Wu for discussion. We main authors have been thinking about this idea for years. Stay tuned.🥳[8/8]🧵